I've been enjoying Eric Kidd's articles on probability theory with Haskell. So I thought I'd follow them up with two things: (1) finding the underlying algebraic structure and (2) showing how it's general enough to do more than just probability.
Firstly, Eric found a really neat factoring of the probability monad as a 'product' of two monads: the Perhaps monad and the List monad. This factoring can be interpreted algebraically.
A monoid is defined to be a set m with a binary operator (typically written as abuttal, ie. the product of a and b is ab) that is associative, and with an element, 1, that is an identity for the binary operator. The List monad gives rise to the monoid freely generated by a set, in other words it defines the smallest monoid containing the set and with no extra relationships between the elements that don't come from the definition of a monoid. The binary operator for List is called ++ and we embed the original set in the monoid using the function \x -> [x], otherwise known as return. [] is the identity. It's not hard to see that we have asociativity as (a ++ b) ++ c == a ++ (b ++ c). If we use Set instead of List then we get the free commutative monoid instead, ie. one where a+b=b+a.
(Eh? Where's my paragraph on m-sets. Don't tell me I have to format all those HTML subscripts again! I hate it when computers do that. I wrote a paragraph and it just vanished. Oh well, maybe version 2.0 will be better. But without subscripts this time...)
If m is a monoid then an m-set is a set s with an action of m on it. An action of a monoid on a set is a scheme that converts each element of the monoid, say g, into a map g*:S→S so that 1* is the identity map and g*h*=(gh)*. The type Writer m s corresponds to pairs in s×m but this also doubles as the free m-set. We simply define f*(x,g)=(x,fg). It's free because we never get f*(x,f')=g*(x',g') unless x=x', so we never get any surprising equalities that aren't inherent in the definition of an m-set. Perhaps, which is actually a pseudonym for Writer Float, defines an R-set, where R is the monoid of reals under multiplication.
In an earlier post I showed how you could layer up algebraic structures. There I showed that you could combine a commutative monoid structure with a monoid structure to get a semiring. So what happens if we layer up a commutative monoid and an m-set? We'll get something that has a commutative binary operator but that can also be acted on my elements of m. Specialise to the case when m is a field like the real or complex numbers. Does this sound like a familiar structure? I hope so, it's a description of a vector space. What Eric Kidd has shown is that we can build a vector space monad by applying an m-set monad transformer (with m a field) to a commutative monoid monad. (This isn't a completely trivial fact and it depends on the fact that the definition of PerhapsT handles distributivity correctly.) I think that's pretty neat. But I'm getting slightly ahead of myself here as I haven't shown what Eric's stuff has to do with vector spaces.
A probability distribution can be thought of as a vector with outcomes forming a basis. Any distribution attaches a probability 'weight' to each possible outcome in the same way that a vector can be written as a weighted sum of basis elements. Each time we have a probabilistic transition, we're effectively multiplying our distribution vector by a stochastic matrix. Eric (and others)'s monad allows you to write these matrix multiplications in a very natural way.
A vector space forms a monad in a straightforward way. If V(B) is the vector space generated by basis B, and V(C) is another vector space, then any function B→V(C) can be lifted to a linear map V(B)→V(C). This lift is clearly of type (B→V(C))→(V(B)→V(C)). With a little flip we get V(B)→(B→V(C))→V(C). This is the main step in showing V to be a monad. And what the probability monad allows us to do is write our stochastic matrices in terms of what happens to the individual basis elements (ie. outcomes) instead of having to write out the entire matrix.
Anyway, this is all just waffle and it really needs some code to make it more concrete. I have an ulterior motive here. It's not just probability theory that is described by vector spaces. So is quantum mechanics. And I plan to work my way up to defining quantum computers and implementing a bunch of well known quantum algorithms in Haskell. In the next installment I expect to get at least as far as writing the code to play with the square root of NOT operator.
PS This idea of layering up algebraic structures is one I haven't found in the textbooks yet. I'm guessing it's in Mac Lane, but I haven't yet justified the cost of that book to myself. But I don't actually have a clue what a category theorist would call a monad transformer and don't recall reading about them in any texts that weren't specifically about computer science. Maybe someone else can fill me in. I do know that it's absolutely standard to get free algebraic structures from monads.
Errata: As notfancy points out, I should really be talking about multisets rather than sets, otherwise we have a+a=a. As programmers often use lists to represent both sets and multisets it can sometimes get confusing.
Sunday, February 25, 2007


Sunday, February 18, 2007
The Essence of Quantum Computing
A popular view of quantum computation is that its power (at least the power of certain well known quantum algorithms) derives from a form of parallel computation coming from the fact that the state of a quantum computer can be a superposition of many classical states. I want to argue that this is in fact a bit of a red herring because there are other models of computation that allow formal superpositions and yet clearly don't provide a form of parallel computation. Instead, the essence of quantum computing is derived from a kind of non-convexity property and this is the common feature of all of the well known quantum algorithms that isn't shared by classical algorithms.
Before continuing there's something important I should say. Let me quote Bennett et al. in Strengths and Weaknesses of Quantum Computing
In other words, what I am saying is in direct contradiction with what is said by some of the founding fathers of quantum computing. Actually, I think that's a good thing, it means that whether I'm right or wrong, I must be saying something non-trivial.
Consider a probabilistic computer. We can represent the probability of its being in any state by an element of a vector space whose basis is the set of possible states and where the coefficient of each basis element is the probability of the computer being in that state. Given any pair of vectors that represent possible ditributions of states. v1 and v2, then av1+bv2, where a,b>=0 and a+b = 1 is also a possible distribution.In other words we can form superpositions exactly analogously to the way we can form superpositions of quantum computer states. The mathematics that describes the notion of a quantum computer performing computations in parallel by superposing N states is formally almost identical to the mathematics describing a probabilistic computer as a superposition of states.
So if we can superpose N states in both classical probabilistic computers and quantum computers, why do neither seem to offer an N times speedup? In the case of quantum computers one popular explanation is that then though we run N states in parallel, we can't perform I/O with those N states in parallel. When we observe a quantum computer we cause a wavefunction collapse (it doesn't matter whether you are a believer in such collapse, that is how we model quantum computers) and instead we make a single observation from a probability distribution. Mathematically this is identical to what happens in a probabilistic machine - a superposition is nondeterministically mapped into one of many definite states.
So whatever the difference is between probabilistic computers and quantum computers, it doesn't lie in the fact that you can form superpositions. Mathematically speaking, probabilistic computers and quantum computers are almost identical in this respect.
But we know that quantum algorithms can do things that no probabilistic algorithm can, so there must be some difference. There is of course. Here's an approach to seeing what it is.
Consider a probabilistic branching process:
Starting at state 1 we can either go to state 2 or state 3, and from there we end up at either A, B or C. Assume that the choice of branch is nondeterministic and that we can assign probabilities to each branch. Suppose also that the branch probabilities are all non-zero. The important thing to note in that diagram is that there are two ways to reach it. The probability of reaching A is the sum of the probabilities for each of the different ways to reach A. The key point I want to make here is that A is more likely because there are two ways to reach it. If I were to replace one or other of the A's with a D then the likelihood of finding our process in state A at the end is reduced.
But in quantum mechanics we replace probabilities with complex 'amplitudes'. When we make our observation at the end, the probability of any outcome is given by the modulus of the amplitude squared. The amplitudes still add, just as in probability theory. But this has a very important consequence. If the amplitudes for the two different ways to reach A lie in opposite directions in the complex plane, then the probability of ending up in state A after observation is reduced by having two ways of reaching A. This is completely different to the probabilistic case. We can paradoxically make something less likely by adding a new way to achieve it. This is where the essence of quantum computing lies.
Pick up just about any paper describing a quantum algorithm and you'll see that the important step is a 'conspiracy' to make the amplitudes of 'undesirable' states sum to zero (or at least something small). Probably the simplest example is counterfactual computation where it is arranged that the computation is executed along two different branches with equal and opposite amplitudes. The neatest example is probably Shor's cycle discovery algorithm that forms the basis of his factoring algorithm. By clever use of the Fourier transform he arranges that branches leading to non-cycles cancel each other out leaving only the periods of cycles with high amplitudes.
However, I think it's important to stress that given any individual quantum computer Bennett et al. and I probably don't disagree on what it actually does. This is an issue of semantics. But semantics does make a difference. The notion of a quantum computer as a super-parallel machine is one being promulgated in the popular science press and I think this causes much confusion with people expecting all kinds of algorithms to run in O(1) time.
So why do people talk about parallel computation if that's not what quantum computer do? I think it's because people aren't comfortable with quantum computers yet. This means they don't want to think of quantum computers as something fundamental and irreducible and instead want to reduce them to something classical. The easiest classical model is the parallel one and so they 'reduce' it to that.
PS This is essentially a specialisation of an old post to the context of quantum computing.
Before continuing there's something important I should say. Let me quote Bennett et al. in Strengths and Weaknesses of Quantum Computing
"The power of quantum computers comes from their ability to follow a coherent superposition of computation paths."
In other words, what I am saying is in direct contradiction with what is said by some of the founding fathers of quantum computing. Actually, I think that's a good thing, it means that whether I'm right or wrong, I must be saying something non-trivial.
Consider a probabilistic computer. We can represent the probability of its being in any state by an element of a vector space whose basis is the set of possible states and where the coefficient of each basis element is the probability of the computer being in that state. Given any pair of vectors that represent possible ditributions of states. v1 and v2, then av1+bv2, where a,b>=0 and a+b = 1 is also a possible distribution.In other words we can form superpositions exactly analogously to the way we can form superpositions of quantum computer states. The mathematics that describes the notion of a quantum computer performing computations in parallel by superposing N states is formally almost identical to the mathematics describing a probabilistic computer as a superposition of states.
So if we can superpose N states in both classical probabilistic computers and quantum computers, why do neither seem to offer an N times speedup? In the case of quantum computers one popular explanation is that then though we run N states in parallel, we can't perform I/O with those N states in parallel. When we observe a quantum computer we cause a wavefunction collapse (it doesn't matter whether you are a believer in such collapse, that is how we model quantum computers) and instead we make a single observation from a probability distribution. Mathematically this is identical to what happens in a probabilistic machine - a superposition is nondeterministically mapped into one of many definite states.
So whatever the difference is between probabilistic computers and quantum computers, it doesn't lie in the fact that you can form superpositions. Mathematically speaking, probabilistic computers and quantum computers are almost identical in this respect.
But we know that quantum algorithms can do things that no probabilistic algorithm can, so there must be some difference. There is of course. Here's an approach to seeing what it is.
Consider a probabilistic branching process:
    __ A
   /
  2
 / \__ B
1   __ A
 \ /
  3
   \__ C
Starting at state 1 we can either go to state 2 or state 3, and from there we end up at either A, B or C. Assume that the choice of branch is nondeterministic and that we can assign probabilities to each branch. Suppose also that the branch probabilities are all non-zero. The important thing to note in that diagram is that there are two ways to reach it. The probability of reaching A is the sum of the probabilities for each of the different ways to reach A. The key point I want to make here is that A is more likely because there are two ways to reach it. If I were to replace one or other of the A's with a D then the likelihood of finding our process in state A at the end is reduced.
But in quantum mechanics we replace probabilities with complex 'amplitudes'. When we make our observation at the end, the probability of any outcome is given by the modulus of the amplitude squared. The amplitudes still add, just as in probability theory. But this has a very important consequence. If the amplitudes for the two different ways to reach A lie in opposite directions in the complex plane, then the probability of ending up in state A after observation is reduced by having two ways of reaching A. This is completely different to the probabilistic case. We can paradoxically make something less likely by adding a new way to achieve it. This is where the essence of quantum computing lies.
Pick up just about any paper describing a quantum algorithm and you'll see that the important step is a 'conspiracy' to make the amplitudes of 'undesirable' states sum to zero (or at least something small). Probably the simplest example is counterfactual computation where it is arranged that the computation is executed along two different branches with equal and opposite amplitudes. The neatest example is probably Shor's cycle discovery algorithm that forms the basis of his factoring algorithm. By clever use of the Fourier transform he arranges that branches leading to non-cycles cancel each other out leaving only the periods of cycles with high amplitudes.
However, I think it's important to stress that given any individual quantum computer Bennett et al. and I probably don't disagree on what it actually does. This is an issue of semantics. But semantics does make a difference. The notion of a quantum computer as a super-parallel machine is one being promulgated in the popular science press and I think this causes much confusion with people expecting all kinds of algorithms to run in O(1) time.
So why do people talk about parallel computation if that's not what quantum computer do? I think it's because people aren't comfortable with quantum computers yet. This means they don't want to think of quantum computers as something fundamental and irreducible and instead want to reduce them to something classical. The easiest classical model is the parallel one and so they 'reduce' it to that.
PS This is essentially a specialisation of an old post to the context of quantum computing.
Modular arithmetic with regular expressions
Problem: Find a regular expression, compatible with GNU grep, that recognises strings of 1's and 0's that form the binary expansion of multiples of 7. (Consider the empty string to be zero.)
Solution:
Here's one (though not necessarily a good one):
The standard approach to solving this problem is probably to construct a finite state automaton to compute the remainder modulo 7 of a binary string and then use the proof of Kleene's theorem to convert the automaton to a regular expression. But as I have some regular expression code left over from a previous post I thought I'd try a purely algebraic approach. Although it's ultimately equivalent to deriving a finite state automaton I thought it might be more fun to use intuitions about linear algebra to get to the solution. And anyway, drawing diagrams with HTML is hard...
Consider first recognising multiples of 3. Assume we have three regular expressions, A, B and C. A corresponds to multiples of 3, B corresponds to numbers that are 1 modulo 3 and C matches numbers that are 2 modulo 3. Then we know
First a note about notation: I'm using bold 0 and 1 to represent binary digits but using regular 0 to represent the regular expression matching nothing and regular 1 to represent the regular expression matching the empty string. a+b means match a or b. So we can interpret the equation for A, say, as saying that a multiple of 3 is the empty string, or a multiple of 3 followed by a 0, or a 1 after one more than a multiple of 3. Similar interpretations apply for the other two equations. We can rewrite this as
where
and
We can now use our ordinary intuitions about solving linear systems. We want to solve for A so we need to eliminate B and C. Start by eliminating C. We have
If we were doing ordinary linear algebra we could say
but for regular expressions we can neither subtract nor divide. However, arguing informally now, (1-a)-1=1+a+a²+a³+…=a* so now we can write
Anyway, those are all the principles we need. Just eliminate each variable in turn by solving for it in terms of the other remaining variables and substituting the solution back into the remaining equations. You should be able to finish the job and solve for A. But you'll notice the work gets tedious for larger integers. That's where the code comes in.
It starts as before but we can delete a whole lot of material:
My simplification rules are still really poor. (Buggy, in fact, but not buggy in a way that leads to incorrect results.) That means we don't expect the final regular expressions to be in any way efficient. But I'm not trying to get the best solution, just a solution.
I'm representing the vector v and matrix M above as simple associative arrays whose elements are found using lookup. Elements not represented are assumed to be 0. fetch handles the sparse lookup:
solve implements exactly the solution method described above. The use of Star corresponds to my abuse of the binomial series for (1-a)-1 above. However rather than manipulate equations I'm always working in terms of matrices and vectors over the regular expressions:
substituteFor substitutes a solution to an equation given by solve into the remainder of the equations.
As I describe above, a variable is eliminated by solving for it and then substituting:
Now some code to output our regular expressions in a form compatible with grep:
Now construct M and v for the equations describing the regular expressions for the classes of binary strings modulo n:
To solve a complete set of equations we reduce it one equation at a time by eliminating variables:
Print regular expression to detect multiples of 7:
Try integers besides 7. But note that the expressions get more and more complex. And of course you can use the equation solving approach for problems besides recognising multiples of integers.
PS I just noticed some of the indentation went wrong on translation to HTML. But the code appears to still compile fine with GHC.
Solution:
Here's one (though not necessarily a good one):
^\(0\|1\(1\(01*00\)*01*010\|\(0\|1\(01*00
\)*01*011\)\(10\(01*00\)*01*011\|\(0\|11\
)1\)*\(10\(01*00\)*01*010\|\(0\|11\)0\)\)
*\(1\(01*00\)*1\|\(0\|1\(01*00\)*01*011\)
\(10\(01*00\)*01*011\|\(0\|11\)1\)*10\(01
*00\)*1\)\)*$
The standard approach to solving this problem is probably to construct a finite state automaton to compute the remainder modulo 7 of a binary string and then use the proof of Kleene's theorem to convert the automaton to a regular expression. But as I have some regular expression code left over from a previous post I thought I'd try a purely algebraic approach. Although it's ultimately equivalent to deriving a finite state automaton I thought it might be more fun to use intuitions about linear algebra to get to the solution. And anyway, drawing diagrams with HTML is hard...
Consider first recognising multiples of 3. Assume we have three regular expressions, A, B and C. A corresponds to multiples of 3, B corresponds to numbers that are 1 modulo 3 and C matches numbers that are 2 modulo 3. Then we know
A = A0+B1+1
B = C0+A1
C = B0+C1
First a note about notation: I'm using bold 0 and 1 to represent binary digits but using regular 0 to represent the regular expression matching nothing and regular 1 to represent the regular expression matching the empty string. a+b means match a or b. So we can interpret the equation for A, say, as saying that a multiple of 3 is the empty string, or a multiple of 3 followed by a 0, or a 1 after one more than a multiple of 3. Similar interpretations apply for the other two equations. We can rewrite this as
x = xM+v
where
M=
0 1 0
1 0 0
0 0 1
and
x = [A B C], v = [1 0 0]
We can now use our ordinary intuitions about solving linear systems. We want to solve for A so we need to eliminate B and C. Start by eliminating C. We have
C = B0+C1
If we were doing ordinary linear algebra we could say
C(1-1) = B0
C = B0(1-1)-1
but for regular expressions we can neither subtract nor divide. However, arguing informally now, (1-a)-1=1+a+a²+a³+…=a* so now we can write
C = B01*
Anyway, those are all the principles we need. Just eliminate each variable in turn by solving for it in terms of the other remaining variables and substituting the solution back into the remaining equations. You should be able to finish the job and solve for A. But you'll notice the work gets tedious for larger integers. That's where the code comes in.
It starts as before but we can delete a whole lot of material:
> import List
> data RE a = Symbol a | Star (RE a) | Sum [RE a] | Prod [RE a]
>   deriving (Eq,Show,Ord)

> a <*> b = Prod [a,b]
> a <+> b = Sum [a,b]

> zero = Sum []
> one = Prod []
My simplification rules are still really poor. (Buggy, in fact, but not buggy in a way that leads to incorrect results.) That means we don't expect the final regular expressions to be in any way efficient. But I'm not trying to get the best solution, just a solution.
> simplify a = let b = simplify' a in if a==b then b else simplify b where
>   simplify' (Prod [a]) = simplify a
>   simplify' (Prod a) | zero `elem` a = zero
>   simplify' (Prod (a:b)) = case simplify a of
>       Prod x -> Prod $ x ++ map simplify b
>       a -> Prod $ filter (/= one) $ map simplify (a:b)

>   simplify' (Sum [a]) = a
>   simplify' (Sum (a:b)) = case simplify a of
>       Sum x -> Sum $ x ++ map simplify b
>       a -> Sum $ nub $ sort $ filter (/= zero) $ map simplify (a:b)

>   simplify' (Star (Sum [])) = one
>   simplify' (Star (Prod [])) = one
>   simplify' (Star a) = Star (simplify a)
>   simplify' a = a
I'm representing the vector v and matrix M above as simple associative arrays whose elements are found using lookup. Elements not represented are assumed to be 0. fetch handles the sparse lookup:
> type Matrix s a = [((s,s),RE a)]
> type Vector s a = [(s,RE a)]

> fetch i x = maybe zero id $ lookup i x
solve implements exactly the solution method described above. The use of Star corresponds to my abuse of the binomial series for (1-a)-1 above. However rather than manipulate equations I'm always working in terms of matrices and vectors over the regular expressions:
> solve range i (m,v) = (
>  [(j,simplify $ fetch (i,j) m <*> Star (fetch (i,i) m)) |
>        j <- range, j/=i],
>        simplify $ fetch i v <*> Star (fetch (i,i) m)
>     )
substituteFor substitutes a solution to an equation given by solve into the remainder of the equations.
> substituteFor range k (v',c') m v = (
>  [((i,j),(fetch j v' <*> fetch (i,k) m) <+> fetch (i,j) m) |
>         i <- range, i/=k, j <- range, j/=k],
>  [(i,(c' <*> fetch (i,k) m) <+> fetch i v) |
>         i <- range, i /= k]
>     )
As I describe above, a variable is eliminated by solving for it and then substituting:
> elim range s (m,v) = let (v',c') = solve range s (m,v)
>                in substituteFor range s (v',c') m v
Now some code to output our regular expressions in a form compatible with grep:
> bracket n (s,n') = if n'>=n then s else "\\(" ++ s ++ "\\)"
> pretty (Symbol a) = ([a],9)
> pretty (Star a) = (bracket 8 (pretty a) ++ "*",8)
> pretty (Prod a) = (concat $ map (bracket 7) $ map pretty a,7)
> pretty (Sum a) = (foldr1 (\a b -> a ++ "\\|" ++ b) $
>                   map (bracket 6) $ map pretty a,6)
Now construct M and v for the equations describing the regular expressions for the classes of binary strings modulo n:
> m n = [(((2*i) `mod` n,i),Symbol '0')|i <- [0..n-1]] ++
>       [(((2*i+1) `mod` n,i),Symbol '1')|i <- [0..n-1]]
> v n = [(0,one)]
To solve a complete set of equations we reduce it one equation at a time by eliminating variables:
> reduce [a] (m,v) = solve [a] a (m,v)
> reduce (a:as) (m,v) = reduce as $ elim (a:as) a (m,v)
> test n = let (_,r) = reduce [n-1,n-2..0] (m n,v n) in simplify r
Print regular expression to detect multiples of 7:
> main = putStrLn $ "^" ++ fst (pretty (test 7)) ++ "$"
Try integers besides 7. But note that the expressions get more and more complex. And of course you can use the equation solving approach for problems besides recognising multiples of integers.
PS I just noticed some of the indentation went wrong on translation to HTML. But the code appears to still compile fine with GHC.
Sunday, February 04, 2007
Exceptions, Disjunctions and Continuations
At the end of section 4 of Call-by-value is dual to call-by-name, Wadler tells a story about the Devil and a billion dollars. After a long time thinking about it, the meaning of it suddenly hit me like an epiphany a few weeks ago, and I'm finally in a position to give an explanation of what it means. (This is also an exercise in TMR6.) And just for a bit of variety I'm going to throw in some C++ and Scheme, starting with some simple C++ code:
This provides a (somewhat unreliable, I think) implementation of a discriminated union. An object of type Either<A,B> is either an object of type A or an object of type B. But unlike the ordinary union, it remembers the type of its contents. I've also provided an either function. Given a function of type A→C and a function of type B→C, then if we're handed an object of type Either<A,B> we know that we can apply one or other function to it to get an object of type C. The functon either applies the appropriate one for you. What's unusual is the way I've implemented it. I'm representing an object of type Either<A,B> as a function of no arguments (in effect a lazy value) returning something of type B (*)() throw (A). There are two paths by which an object can get out of such a function: either it is returned or it is thrown out. Having two paths is what I've used to implement of a template that represents either one thing or another. This simple example should make it clear that there is some sort of a connection between exceptions and logical or (ie. disjunction).
In functional languages exceptions tend to be handled a little differently. Whereas C++ has a throw keyword, there is no equivalent in Scheme, say. Instead
the call-with-current-continuation function acts like catch. The argument to call-with-current-continuation is a function (lambda (throw) ...) and the argument to this function (itself a function), here called throw, does the throwing. For example consider the scheme expression:
The result is 7, not 8. The 7 is thrown 'past' the (+ 1 ...) and is caught by the surrounding call-with-current-continuation. The important difference from C++ is that if any subexpression is to throw some value, it must be 'handed' a suitable throw function. Note also that Scheme is dynamically typed. In a static functional language throwing exceptions is a tiny bit more subtle. Not only must a subexpression be handed a suitable function for throwing, it must be handed a function of a suitable type. In particular, if the data thrown is to be of type a, then the subexpression must be handed a suitable 'throw' function that can take an object of type a as argument. Think of such a function as an a-consumer. So if we want to implement the C++ idea above in a statically typed functional language that supports exceptions we need to replace the function of type B (*)() throw (A) with a function that consumes an A-consumer and returns an object of type B. Such a function can either throw a result of type A or return a result of type B.
Anyway, here's a complete Scheme example (BTW it's my first bit of Scheme code longer than one line):
OK, time for some logic.
As everyone familiar with propositional calculus knows, a ∨ b = ~a → b. Or in English "a or b" is the same as "if a isn't true then b is".
Less well known is the Curry-Howard isomorphism. In a nutshell it goes like this: if you know a, and you know a → b, then you can deduce b (using modus ponens). Similarly, in a strictly typed programming language, if you have an object of type a, and a function of type a → b, then you can use them to make an object of type b (just apply the function to a). So given a bunch of propositions in 1-1 correspondence with a bunch of objects, you should be able to see that the set of propositions you can deduce by modus ponens is going to be in 1-1 correspondence with the objects you can make by function application.
But there's more to logic than modus ponens. In classical logic you also have double negation elimination. In other words, if you know ~~a then you can deduce a. So double negation elimination is like having a polymorphic function ~~a → a for any a. What does "~" mean in terms of functions? In logic, define ⊥ to be the unprovable false proposition. Then ~a is simply a→⊥. In programming define ⊥ to be the type with no instances and we can define ~a to be the type of functions a→⊥. A function of type ~a is a function that consumes an instance of type a and gives you back nothing in return. Clearly if you can make an object of type a then no function of type ~a can exist or else you could apply it to a and get an object f type ⊥, which is impossible by definition.
It's not hard to see that there can be no well behaved function that for any type a can map an ~~a to an a. An ~~a is a thing that consumes a-consumers. In a sense it's destructive. There are no raw ingredients from which you could possibly make an a for all a. So there is no function of type ~~a → a. But this type can serve very well as the type of the catch operator described above. Rewriting the scheme example above with Haskell-like notation we expect something like
catch $ \throw -> ... (throw a) ...
Because throw never returns we can assign it the type a -> ⊥ without problems and hence catch can be assigned type ~~a. This now means that the Curry-Howard isomorphism can be extended to classical logic if we throw in catch along with the usual functions you expect in a pure typed functional language.
So If we use catch to throw an exception out of a function, then the function must be handed a ~a as argument. So in order to implement Either, we must replace the C++ type B (*)() throw(A) with ~a -> b. In other words, if we use the symbol ∨ to mean either, then exactly in classical logic, we have a ∨ b = ~a → b.
You can think of the argument to catch as being a bit like a bungee cord with one end attached to the catch. If a function is handed the other end of such a bungee cord it can either use it to catapult out a value of type a, or the function can ignore it and return somehing of type b. But there's a neat twist on this. If b = ~a then the function, on being handed a bungee cord, could simply hand it back as a return value. In other words, whatever type a is, we can always construct an object of type a ∨ ~a from the identity function. This corresponds to the fact that a ∨ ~a is a tautology of classical logic.
And now you can reread Wadler's story about the Devil and see that my story about a bungee cord is really the same one.
Exercise: Implement Left, Right and either using the method above in the Haskell Cont monad.
PS Reasoning about exceptions in this way is new to me and so I don't feel I have the above on a firm footing. So expect some errors. In particular I haven't thought about what happens if you try to nest disjunctive structures this way. You can be sure that the C++ implementation will fail because the exception may be caught by the wrong try.
Update: fixed some typos. But also here's an exercise:
Exercise: a ∧ b = ~(~a ∨ ~b). What does that mean in the above context? (I haven't got my head around this yet.)
#include <iostream>
#include <string>

using namespace std;

template<class A,class B>
class Either
{
public:
    virtual B value() const throw (A) = 0;
};

template<class A,class B>
class Left : public Either<A,B>
{
    A a;
public:
    Left(A a0) : a(a0) { }
    B value() const throw (A) { throw a; }
};

template<class A,class B>
class Right : public Either<A,B>
{
    B b;
public:
    Right(B b0) : b(b0) { }
    B value() const throw (A) { return b; }
};

template<class A,class B,class C>
C either(const Either<A,B> &e,C (*f)(A),C (*g)(B))
{
    try {
        return g(e.value());
    } catch (A &a) {
        return f(a);
    }
}

string f(int a)
{
    return "int";
}

string g(float b)
{
    return "float";
}

int main()
{
    std::cout <<
        either<int,float,string>(Left<int,float>(7),f,g)
        << std::endl;
    std::cout <<
        either<int,float,string>(Right<int,float>(7.0f),f,g)
        << std::endl;
}
This provides a (somewhat unreliable, I think) implementation of a discriminated union. An object of type Either<A,B> is either an object of type A or an object of type B. But unlike the ordinary union, it remembers the type of its contents. I've also provided an either function. Given a function of type A→C and a function of type B→C, then if we're handed an object of type Either<A,B> we know that we can apply one or other function to it to get an object of type C. The functon either applies the appropriate one for you. What's unusual is the way I've implemented it. I'm representing an object of type Either<A,B> as a function of no arguments (in effect a lazy value) returning something of type B (*)() throw (A). There are two paths by which an object can get out of such a function: either it is returned or it is thrown out. Having two paths is what I've used to implement of a template that represents either one thing or another. This simple example should make it clear that there is some sort of a connection between exceptions and logical or (ie. disjunction).
In functional languages exceptions tend to be handled a little differently. Whereas C++ has a throw keyword, there is no equivalent in Scheme, say. Instead
the call-with-current-continuation function acts like catch. The argument to call-with-current-continuation is a function (lambda (throw) ...) and the argument to this function (itself a function), here called throw, does the throwing. For example consider the scheme expression:
(call-with-current-continuation
    (lambda (throw) (+ 1 (throw 7))))
The result is 7, not 8. The 7 is thrown 'past' the (+ 1 ...) and is caught by the surrounding call-with-current-continuation. The important difference from C++ is that if any subexpression is to throw some value, it must be 'handed' a suitable throw function. Note also that Scheme is dynamically typed. In a static functional language throwing exceptions is a tiny bit more subtle. Not only must a subexpression be handed a suitable function for throwing, it must be handed a function of a suitable type. In particular, if the data thrown is to be of type a, then the subexpression must be handed a suitable 'throw' function that can take an object of type a as argument. Think of such a function as an a-consumer. So if we want to implement the C++ idea above in a statically typed functional language that supports exceptions we need to replace the function of type B (*)() throw (A) with a function that consumes an A-consumer and returns an object of type B. Such a function can either throw a result of type A or return a result of type B.
Anyway, here's a complete Scheme example (BTW it's my first bit of Scheme code longer than one line):
(define (right b) (lambda (throw) b))
(define (left a) (lambda (throw) (throw a)))

(define (compose f g) (lambda (x) (f (g x))))
(define (id x) x)

(define (either f g x)
   (call-with-current-continuation
       (lambda (throw)
           (g (x (compose throw f))))))

(define (f x) (cons "left" x))
(define (g x) (cons "right" x))

(either f g (left 1))
(either f g (right 2))
OK, time for some logic.
As everyone familiar with propositional calculus knows, a ∨ b = ~a → b. Or in English "a or b" is the same as "if a isn't true then b is".
Less well known is the Curry-Howard isomorphism. In a nutshell it goes like this: if you know a, and you know a → b, then you can deduce b (using modus ponens). Similarly, in a strictly typed programming language, if you have an object of type a, and a function of type a → b, then you can use them to make an object of type b (just apply the function to a). So given a bunch of propositions in 1-1 correspondence with a bunch of objects, you should be able to see that the set of propositions you can deduce by modus ponens is going to be in 1-1 correspondence with the objects you can make by function application.
But there's more to logic than modus ponens. In classical logic you also have double negation elimination. In other words, if you know ~~a then you can deduce a. So double negation elimination is like having a polymorphic function ~~a → a for any a. What does "~" mean in terms of functions? In logic, define ⊥ to be the unprovable false proposition. Then ~a is simply a→⊥. In programming define ⊥ to be the type with no instances and we can define ~a to be the type of functions a→⊥. A function of type ~a is a function that consumes an instance of type a and gives you back nothing in return. Clearly if you can make an object of type a then no function of type ~a can exist or else you could apply it to a and get an object f type ⊥, which is impossible by definition.
It's not hard to see that there can be no well behaved function that for any type a can map an ~~a to an a. An ~~a is a thing that consumes a-consumers. In a sense it's destructive. There are no raw ingredients from which you could possibly make an a for all a. So there is no function of type ~~a → a. But this type can serve very well as the type of the catch operator described above. Rewriting the scheme example above with Haskell-like notation we expect something like
catch $ \throw -> ... (throw a) ...
Because throw never returns we can assign it the type a -> ⊥ without problems and hence catch can be assigned type ~~a. This now means that the Curry-Howard isomorphism can be extended to classical logic if we throw in catch along with the usual functions you expect in a pure typed functional language.
So If we use catch to throw an exception out of a function, then the function must be handed a ~a as argument. So in order to implement Either, we must replace the C++ type B (*)() throw(A) with ~a -> b. In other words, if we use the symbol ∨ to mean either, then exactly in classical logic, we have a ∨ b = ~a → b.
You can think of the argument to catch as being a bit like a bungee cord with one end attached to the catch. If a function is handed the other end of such a bungee cord it can either use it to catapult out a value of type a, or the function can ignore it and return somehing of type b. But there's a neat twist on this. If b = ~a then the function, on being handed a bungee cord, could simply hand it back as a return value. In other words, whatever type a is, we can always construct an object of type a ∨ ~a from the identity function. This corresponds to the fact that a ∨ ~a is a tautology of classical logic.
And now you can reread Wadler's story about the Devil and see that my story about a bungee cord is really the same one.
Exercise: Implement Left, Right and either using the method above in the Haskell Cont monad.
PS Reasoning about exceptions in this way is new to me and so I don't feel I have the above on a firm footing. So expect some errors. In particular I haven't thought about what happens if you try to nest disjunctive structures this way. You can be sure that the C++ implementation will fail because the exception may be caught by the wrong try.
Update: fixed some typos. But also here's an exercise:
Exercise: a ∧ b = ~(~a ∨ ~b). What does that mean in the above context? (I haven't got my head around this yet.)
Saturday, February 03, 2007
Comonads and reading from the future
I'm too busy reading Bernie Pope and Russell O'Connor's articles in the latest Monad Reader to think about much else right now, so I'm only going to make a brief post. I want to mention something pointed out by Nick Frisby over here. The loeb function is in fact closely related to cfix, the dual of mfix for monads, defined by Dave Menendez. (Nick Frisby's statement isn't quite correct but it's interest value outweighs its truthiness.) In fact, I can borrow Russell's language to say that whereas mfix sends data back in time, cfix and loeb read data from the future!
Think of it like this: when you use cobind with a comonad you provide some function that distills down a comonadic data structure into a single value and then cobind applies this distillation repeatedly at every point in the comonadic structure to give you another comonadic structure. My canonical example is the cellular automaton where you give a rule that defines how to compute each individual cell as a function of the whole grid, and cobind applies this throughout an entire input grid to give you back an entire output grid. The functions cfix and loeb allow you to give rules for each cell where you're allowed to make reference to the entire output grid. If you think of the output grid as something in the future that you haven't yet computed, then cfix and loeb allow you to read from the future.
Here's an example of cfix it in use (where I make [] a comonad by interpreting it as a kind of one-sided zipper):
In the expression test we can use head and tail to refer to the sublist to the right of each element from within the list itself. For example, in the subexpression 2*head.tail the head.tail is being applied to cfix [1+head.tail,17].
Note how in this example (1) loeb gives you back an entire list, not just one element and (2) cfix respects the comonadic structure in the sense that you can only refer to elements to the right of the current one whereas loeb lets you refer to the entire output list. I think this helps to make clear the differences and similarities between cfix and loeb.
That wasn't too brief. But I did cheat by copying and pasting code from an old post. Anyway, back to tinkering with my implementation of dropWhile...
Think of it like this: when you use cobind with a comonad you provide some function that distills down a comonadic data structure into a single value and then cobind applies this distillation repeatedly at every point in the comonadic structure to give you another comonadic structure. My canonical example is the cellular automaton where you give a rule that defines how to compute each individual cell as a function of the whole grid, and cobind applies this throughout an entire input grid to give you back an entire output grid. The functions cfix and loeb allow you to give rules for each cell where you're allowed to make reference to the entire output grid. If you think of the output grid as something in the future that you haven't yet computed, then cfix and loeb allow you to read from the future.
Here's an example of cfix it in use (where I make [] a comonad by interpreting it as a kind of one-sided zipper):
> instance Show (x -> a)
> instance Eq (x -> a)

> instance (Num a,Eq a) => Num (x -> a) where
>     fromInteger = const . fromInteger
>     f + g = \x -> f x + g x
>     f * g = \x -> f x * g x
>     negate = (negate .)
>     abs = (abs .)
>     signum = (signum .)

> class Comonad w where
>    coreturn :: w a -> a
>    cobind :: (w a -> b) -> w a -> w b

> instance Comonad [] where
>     coreturn (x:xs) = x
>     cobind f [] = []
>     cobind f (x:xs) = f (x:xs) : cobind f xs

> cfix :: Comonad d => d (d a -> a) -> a
> cfix d = coreturn d (cobind cfix d)

> ouroboros = [2*head.tail,1+head.tail,17]
> test = cfix ouroboros
In the expression test we can use head and tail to refer to the sublist to the right of each element from within the list itself. For example, in the subexpression 2*head.tail the head.tail is being applied to cfix [1+head.tail,17].
Note how in this example (1) loeb gives you back an entire list, not just one element and (2) cfix respects the comonadic structure in the sense that you can only refer to elements to the right of the current one whereas loeb lets you refer to the entire output list. I think this helps to make clear the differences and similarities between cfix and loeb.
That wasn't too brief. But I did cheat by copying and pasting code from an old post. Anyway, back to tinkering with my implementation of dropWhile...
Friday, January 26, 2007
The Monads Hidden Behind Every Zipper
Uustalu points out that behind every zipper lies a comonad. I used this in my cellular automaton example. What he doesn't mention is that there is also a monad lurking behind every zipper and that it arises in a natural way. The catch is that it's a monad in the wrong category making it tricky to express in Haskell.
Firstly, what does "wrong category" mean? In the category of vector spaces, every object is equipped with a commutative binary + operator. We can make no such assumption in Haskell. What's more, Haskell doesn't easily allow us to restrict type constructors to instances of Num say. So we can't easily implement monads in the category of vector spaces as instances of Haskell'sMonad. Nonetheless, we can always write our own bind and return constrained by Num, and that's what I'll do here. I believe there are workarounds that don't involve GADT abuse but really I just want to illustrate an idea, not write a complete working application.
As I've mentioned on #haskell, convolution is comonadic. A convolution (more specifically, a discrete convolution) is a function that maps a (doubly infinite) sequence of real numbers to another such sequence of real numbers in such a way that each number in the new sequence is a weighted sum of numbers in the old sequence and the weights depend only on the relative positions of the numbers. For example: replacing each number in the sequence with the average of it and its neighbours is a convolution.
Here's a simple example. Consider the sequence ...0,0,1,2,3,0,0,... We'll replace each number with the sum of its neighbours and twice itself. So this maps to ...,0,0+0+1,0+2*1+2,1+2*2+3,2+2*3+0,3+2*0+0,0,... The structure of this computation is very similar to the structure of cellular automaton evaluation and we can reuse that code here:
When we run test we get [1,4,8,8,3].
Now think about the structure of this computation. We write a function f that gathers up the value at a cell and its neighbours and computes the weighted sum. cobind then applies this function all the way through our sequence to get our result. The important thing is that f pulls in the data it needs, distilling it down to one value, and that's why it has type Zipper a -> a.
There's another approach to convolution. We could push or scatter data. At each point in the sequence we could take the value and push one copy left, one copy right, and leave double the original value in place. Each cell will end up with three values left in it and all we have to do is sum the values deposited in a cell. What we want therefore is to take a value in a cell, of type a, and generate an entire zipper full of values pushed from it, ie. a Zipper a. We'd then like bind for the monad to sum over the returned zippers, staggering them right and left as appropriate. Here's a table illustrating what I mean:
Unfortunately, as I pointed out above, bind for a monad can't perform summations, so I have to define bind' and return' instead.
Note that I'm going to assume that elements past the end of a list (so to speak) actually represent zero and define new versions of left and right that produce the required zeros on demand:
Here's our fake monad:
Run test' and we get the same result as before by a quite different method.
You should be able to see that in some sense comonads describe lazy computations and monads represent strict ones. In strict languages you evaluate your arguments first, and then push them into a function. In lazy languages you call the function first, and it pulls in the value of its arguments as needed. In fact, in Haskell we have a strictness monad and in ocaml you can implement a lazy comonad. By and large, it's easier to write pull algorithms in Haskell. Push algorithms are much easier to implement in a language with side effects. In fact, one of the things that Haskell beginners need to learn is how to rewrite push algorithms as pull algorithms and eliminate those side effects.
What I think is interesting here is that this dichotomy between push and pull, scatter and gather, is pervasive all the way through computing, and it's quite pretty that this deep notion it can be captured nicely by a(n almost) monad and a comonad. Just to give an illustration of how pervasive it is consider 3D rendering. We typically want to take a list of primitives and turn it into an array of pixels. If we rasterise we push the primitives, asking for each primitive, what pixels does it cover. If we ray-trace we pull on the pixels asking, for each one, what primitives cover it. Many optimisations to both of these approaches consist of making judicious decisions about which part of the pipeline should be switched from push to pull or vice versa.
BTW I have an algorithm for automatically converting some types of pull algorithm into push algorithms and vice versa. It's another one of those papers that I keep meaning to finish and submit for publication one day...
Firstly, what does "wrong category" mean? In the category of vector spaces, every object is equipped with a commutative binary + operator. We can make no such assumption in Haskell. What's more, Haskell doesn't easily allow us to restrict type constructors to instances of Num say. So we can't easily implement monads in the category of vector spaces as instances of Haskell's
As I've mentioned on #haskell, convolution is comonadic. A convolution (more specifically, a discrete convolution) is a function that maps a (doubly infinite) sequence of real numbers to another such sequence of real numbers in such a way that each number in the new sequence is a weighted sum of numbers in the old sequence and the weights depend only on the relative positions of the numbers. For example: replacing each number in the sequence with the average of it and its neighbours is a convolution.
Here's a simple example. Consider the sequence ...0,0,1,2,3,0,0,... We'll replace each number with the sum of its neighbours and twice itself. So this maps to ...,0,0+0+1,0+2*1+2,1+2*2+3,2+2*3+0,3+2*0+0,0,... The structure of this computation is very similar to the structure of cellular automaton evaluation and we can reuse that code here:
> data Zipper a = Zipper [a] [a] deriving (Eq,Show)

> left (Zipper (a:as) bs) = Zipper as (a:bs)
> right (Zipper as (b:bs)) = Zipper (b:as) bs

> class Comonad w where
>    coreturn :: w a -> a
>    cobind :: (w a -> b) -> w a -> w b

> iterate1 f x = tail $ iterate f x

> instance Comonad Zipper where
>    cobind f a = fmap f $ Zipper (iterate1 left a) (iterate right a)
>    coreturn (Zipper _ (b:_)) = b

> a = Zipper (repeat 0) ([0,1,2,3]++repeat 0)
> f (Zipper (a:_) (b:c:_)) = a+2*b+c

> test = let Zipper u v = cobind f a in take 5 v
When we run test we get [1,4,8,8,3].
Now think about the structure of this computation. We write a function f that gathers up the value at a cell and its neighbours and computes the weighted sum. cobind then applies this function all the way through our sequence to get our result. The important thing is that f pulls in the data it needs, distilling it down to one value, and that's why it has type Zipper a -> a.
There's another approach to convolution. We could push or scatter data. At each point in the sequence we could take the value and push one copy left, one copy right, and leave double the original value in place. Each cell will end up with three values left in it and all we have to do is sum the values deposited in a cell. What we want therefore is to take a value in a cell, of type a, and generate an entire zipper full of values pushed from it, ie. a Zipper a. We'd then like bind for the monad to sum over the returned zippers, staggering them right and left as appropriate. Here's a table illustrating what I mean:
0 -> 0 0 0 0 0 0
1 -> 0 1 2 1 0 0
2 -> 0 0 2 4 2 0
3 -> 0 0 0 3 6 3
0 -> 0 0 0 0 0 0
----------------
     0 1 4 8 8 3
Unfortunately, as I pointed out above, bind for a monad can't perform summations, so I have to define bind' and return' instead.
> plus (Zipper a b) (Zipper a' b') = Zipper (plus' a a') (plus' b b') where
>        plus' (a:as) (b:bs) = (a+b) : plus' as bs
>        plus' a [] = a
>        plus' [] a = a
Note that I'm going to assume that elements past the end of a list (so to speak) actually represent zero and define new versions of left and right that produce the required zeros on demand:
> left' (Zipper (a:as) bs) = Zipper as (a:bs)
> left' (Zipper [] bs) = Zipper [] (0:bs)
> right' (Zipper as (b:bs)) = Zipper (b:as) bs
> right' (Zipper as []) = Zipper (0:as) []

> tail' [] = []
> tail' a = tail a
> stagger f [] = []
> stagger f (x:xs) = x : map f (stagger f xs)
> stagger1 f x = tail' (stagger f x)

> instance Functor Zipper where
>    fmap f (Zipper a b) = Zipper (map f a) (map f b)
Here's our fake monad:
> return' a = Zipper [] [a]
> bind' f x = let Zipper a b = fmap f x
>            in foldl1 plus (stagger left' b ++ stagger1 right' a)

> a' = Zipper [] [0,1,2,3]
> f' x = Zipper [x] [2*x,x]

> test' = let Zipper u v = bind' f' a' in take 5 v
Run test' and we get the same result as before by a quite different method.
You should be able to see that in some sense comonads describe lazy computations and monads represent strict ones. In strict languages you evaluate your arguments first, and then push them into a function. In lazy languages you call the function first, and it pulls in the value of its arguments as needed. In fact, in Haskell we have a strictness monad and in ocaml you can implement a lazy comonad. By and large, it's easier to write pull algorithms in Haskell. Push algorithms are much easier to implement in a language with side effects. In fact, one of the things that Haskell beginners need to learn is how to rewrite push algorithms as pull algorithms and eliminate those side effects.
What I think is interesting here is that this dichotomy between push and pull, scatter and gather, is pervasive all the way through computing, and it's quite pretty that this deep notion it can be captured nicely by a(n almost) monad and a comonad. Just to give an illustration of how pervasive it is consider 3D rendering. We typically want to take a list of primitives and turn it into an array of pixels. If we rasterise we push the primitives, asking for each primitive, what pixels does it cover. If we ray-trace we pull on the pixels asking, for each one, what primitives cover it. Many optimisations to both of these approaches consist of making judicious decisions about which part of the pipeline should be switched from push to pull or vice versa.
BTW I have an algorithm for automatically converting some types of pull algorithm into push algorithms and vice versa. It's another one of those papers that I keep meaning to finish and submit for publication one day...
Saturday, January 20, 2007
Fox's Ubiquitous Free Derivative pt. 2
As promised earlier, here are some Haskell definitions of derivatives that can be applied to regular expressions. They all give operators that might occasionally be of practical use. But what's more interesting to me is that we now have enough of an intuition pump going between types and regular expression that we can siphon off ideas from papers on types and use them with regexps.
First define a regular expression type:
I use lists instead of binary operators to represent products and sums because
addition and multiplication of regular expressions is associative.
Here's how to make a simple regular expression from a string
Exercise: Write a proper parser for these things so we can use conventional regexp notation!
Here's a test to see whether a regular expression matches the empty string:
I've decided to name these derivatives after people. So first I define the McBride derivative which is a generalisation of the dissection operator introduced in Clowns to the left.... The key idea is that if d = mcbride c j a then d (x <*> y) = (d x <*> j y) <+> (c x <*> d y). This needs to respect the associativity of <*> and one way to achieve this is by choosing c and j that are multiplicative homomorphisms so that, for example, c(x <*> y) = c x <*> c y.
And now I can define all the Leibniz, Fox and Brzozowski derivatives as special cases of the mcbride derivative. The latter each come in left- and right-handed pairs.
brzozowski_l is the usual Brzozowski derivative. If r matches some language, brzozowski_l a t matches the sublanguage of strings beginning with a and with that a removed. We can define regular expression matching in the usual way in terms of it:
Now we can start matching.
ex1 would normally be written as "abc|b*c".
brzozowski_r chews off a symbol from the right:
leibniz a allows you to leave out one a from anywhere in the regexp.
ex3 matches "abracadabra" as it might be shouted by a wizard who might lengthen the second last 'a' to make sure the spirits can hear. ex4 matches such strings with precisely one missing 'r'.
ex3 would normally be written as "abracada*bra".
fox_l a makes regular expressions accept any prefix ending just before an a. Combining fox_l and fox_r allows you to search for all elements of a language just between a chosen pair of symbols.
In ex5 we build a regexp for certain types of statement in a simple language and then pull out from it the part corresponding to substrings within parentheses. The undifferentiated part of ex5 would normally be written as "x = ([0-9]+[0-9]); *".
Open Question: There are more derivatives that can be constructed from the parts I've given. What do they do? What other multiplicative homomorphisms can you define? What derivatives do they give? (Hint: consider the property "R matches only a finite language").
Oh...I almost forgot the whole point of this. It's now possible to see that McBride's l-operator is a version of the Brzozowski derivative. In fact, the theorems he proves about l are pretty similar to the theorems that get proved about the Brzozowski derivative such as Theorem 4.4 here.
Some helper functions:
splits x returns all the ways of splitting x into pairs u and v such that u ++ v == x and v is non-empty.
Some (incomplete) simplification rules for regular expressions
First define a regular expression type:
> import List
> data RE a = Symbol a | Star (RE a) | Sum [RE a] | Prod [RE a]
>   deriving (Eq,Show,Ord)
I use lists instead of binary operators to represent products and sums because
addition and multiplication of regular expressions is associative.
> a <*> b = Prod [a,b]
> a <+> b = Sum [a,b]

> zero = Sum []
> one = Prod []
Here's how to make a simple regular expression from a string
> re x = Prod $ map Symbol x
Exercise: Write a proper parser for these things so we can use conventional regexp notation!
Here's a test to see whether a regular expression matches the empty string:
> acceptsEmpty (Symbol _) = False
> acceptsEmpty (Star _) = True
> acceptsEmpty (Sum l) =  or $ map acceptsEmpty l
> acceptsEmpty (Prod l) = and $ map acceptsEmpty l
I've decided to name these derivatives after people. So first I define the McBride derivative which is a generalisation of the dissection operator introduced in Clowns to the left.... The key idea is that if d = mcbride c j a then d (x <*> y) = (d x <*> j y) <+> (c x <*> d y). This needs to respect the associativity of <*> and one way to achieve this is by choosing c and j that are multiplicative homomorphisms so that, for example, c(x <*> y) = c x <*> c y.
> mcbride _ _ a (Symbol a') = if a==a' then one else zero
> mcbride c j a (Sum p) = Sum $ map (mcbride c j a) p
> mcbride _ _ _ (Prod []) = zero
> mcbride c j a (Prod x) = Sum $ map f (splits x) where
>     f (x,y:ys) = Prod $ map c x ++ [mcbride c j a y] ++ map j ys
> mcbride c j a (Star p) = c (Star p) <*> mcbride c j a p <*> j (Star p)
And now I can define all the Leibniz, Fox and Brzozowski derivatives as special cases of the mcbride derivative. The latter each come in left- and right-handed pairs.
> delta p = if acceptsEmpty p then one else zero

> leibniz,fox_l,fox_r,brzozowski_l :: (Ord a,Eq a) => a -> RE a -> RE a
> leibniz a p = simplify $ mcbride id id a p
> fox_l a p = simplify $ mcbride id (const (one)) a p
> fox_r a p = simplify $ mcbride (const (one)) id a p
> brzozowski_l a p = simplify $ mcbride delta id a p
> brzozowski_r a p = simplify $ mcbride id delta a p
brzozowski_l is the usual Brzozowski derivative. If r matches some language, brzozowski_l a t matches the sublanguage of strings beginning with a and with that a removed. We can define regular expression matching in the usual way in terms of it:
> matches re s = acceptsEmpty (matches' re s) where
>   matches' re [] = re
>   matches' re (a:as) = matches' (brzozowski_l a re) as
Now we can start matching.
ex1 would normally be written as "abc|b*c".
> ex1 = (re "abc") <+> (Star (re "b") <*> Symbol 'c')
> test1 = map (matches ex1) ["abc","bbc","bbbbc","abbbbc"]
brzozowski_r chews off a symbol from the right:
> test2 = map (matches (brzozowski_r 'c' ex1)) ["abc","bbc","ab","bbbbb"]
leibniz a allows you to leave out one a from anywhere in the regexp.
ex3 matches "abracadabra" as it might be shouted by a wizard who might lengthen the second last 'a' to make sure the spirits can hear. ex4 matches such strings with precisely one missing 'r'.
ex3 would normally be written as "abracada*bra".
> ex3 = re "abracad" <*> Star (re "a") <*> re "bra"
> test3 = map (matches ex3) ["abracadabra","abracadaaaaabra"]
> ex4 = leibniz 'r' ex3
> test4 = map (matches ex4) ["abracadabra","abacadabra","abracaaaaadaba","abacadaba"]
fox_l a makes regular expressions accept any prefix ending just before an a. Combining fox_l and fox_r allows you to search for all elements of a language just between a chosen pair of symbols.
In ex5 we build a regexp for certain types of statement in a simple language and then pull out from it the part corresponding to substrings within parentheses. The undifferentiated part of ex5 would normally be written as "x = ([0-9]+[0-9]); *".
> ex5 = simplify $ fox_r '(' $ fox_l ')' $
>   let digits = Star (Sum (map Symbol "0123456789")) in
>        re "x = (" <*> digits <*> re "+" <*> digits <*> re ");" <+> Star (re " ")
> test5 = map (matches ex5) ["1+2","7-4"]
Open Question: There are more derivatives that can be constructed from the parts I've given. What do they do? What other multiplicative homomorphisms can you define? What derivatives do they give? (Hint: consider the property "R matches only a finite language").
Oh...I almost forgot the whole point of this. It's now possible to see that McBride's l-operator is a version of the Brzozowski derivative. In fact, the theorems he proves about l are pretty similar to the theorems that get proved about the Brzozowski derivative such as Theorem 4.4 here.
Some helper functions:
splits x returns all the ways of splitting x into pairs u and v such that u ++ v == x and v is non-empty.
> splits [] = []
> splits (a:as) = ([],a:as) : map f (splits as) where
>   f (x,y) = (a:x,y)
Some (incomplete) simplification rules for regular expressions
> simplify a = let b = simplify' a in if a==b then b else simplify b where
>   simplify' (Prod [a]) = a
>   simplify' (Prod a) | zero `elem` a = zero
>   simplify' (Prod (a:b)) = case a of
>       Prod x -> Prod $ x ++ map simplify b
>       a -> Prod $ filter (/= one) $ map simplify (a:b)
>
>   simplify' (Sum [a]) = a
>   simplify' (Sum (a:b)) = case a of
>       Sum x -> Sum $ x ++ map simplify b
>       a -> Sum $ nub $ sort $ filter (/= zero) $ map simplify (a:b)
>
>   simplify' (Star a) = Star (simplify a)
>   simplify' a = a
Tuesday, January 16, 2007
Fox's Ubiquitous Free Derivative
A post in three acts.
Every regular expression defines a language - the set of strings exactly matching the expression. Given a language L made from the symbols in S, define ∂sL, where s is a symbol in S, to be the language made by taking all of the prefixes in L that end just before an s, deleting the final s. For example, if the language were L={MADAM} then ∂ML={∅,MADA}, ∂AL={M,MAD} and ∂DL={MA}. We can write the regular expressions for these languages as 1+MADA, M+MAD and MA. So in this case, applying ∂s trivially gives another regular language. So here's a problem: is the set of prefixes of a regular language L, ending at s, also regular?
Let's use ∂s to define an operation on regular expressions that computes the regular expression for the prefixes.
Consider a regular expression of the form ab, where a and b are regular expresions. A prefix for the language ending at symbol s either ands in the 'a' part, corresponding to something matching ∂sa, or it ends in the b part in which case it matches a∂sb.
But so far I've just mentioned finite languages. What about the * operator. Well a prefix in a* must consist of a sequence of strings matching a but end as a prefix of a. Ie. we need ∂s(a*)=a*∂sa.
So it's not hard to see (I hope) that
works nicely and proves that the answer to the above question is yes.
Rather than regurgitate someone else's words, take a peek at Dissecting Data Structures. Define the operator, acting on types, ∂, by ∂ F X = Δ F X 1, where Δ is my poor man's version of del with a vertical line through it. From the definition of Δ you can see it satisfies:
∂(K A) X = 0
∂Id X = 1
∂(F+G) X=∂F X+∂G X
&part(F×G) X=∂F X×G 1+F X×∂G X
If you read McBride's paper, you'll see that the ∂ operator slices a type in half, throwing away the elements in the right half, keeping just the 'shape' of the right half.
Check out the definition of the Fox derivative in section 4 of Free Differential Calculus. The Fox derivative is used to compute the Alexander polynomial of a knot.
But I hope you can see that we have yet another definition that looks very similar. The common theme is differentiation with a twist. When you differentiate a product fg, one term is the usual one, fD(g), but the other term isn't D(f)g but the g is replaced by a drastically simplified version (either 1, or g(1)). Both versions 1 and 2 have a notion of chopping something in half at some point and keeping the left half. (Actually, you could tweak the definition in part 2 so that g is replaced by 1 too, then you'd no longer preserve the shape of the right half of the type and you'd really have a slicing operator, and the analogies would become clearer.)
I just need to relate the * operator in part 1 to the derivative of the inverse in the free derivative. Let me do this in a hand-waving manner: Conceptually, a*=1+a+a²+… which might be considered the same as 1/(1-a). ∂(1/(1-a)) = (using 4(ii)) 1/(1-a)∂a = a*∂a.
So what does it all mean? I've no idea. I'm just pointing out that the Fox derivative, or something like it, has what I think are hitherto unnoticed applications to computer science. Anyway, some of this will become clearer when I post some Haskell code implementing no less than five different types of derivatives of regular expressions (some time in the next week when I have a spare moment), and that should partially answer my question that I posed on λtU.
On further reflection, I can say something about what this means. The way to view derivatives is as an operation that chops things in 'half', destroying something in the middle. The Leibniz rules corresponds to the notion that when you chop a product you must either chop in the left side of the product or the right side. In the usual Leibniz rule you reassemble the pieces on either side - leaving a hole. With the Fox derivative you throw away what's on the right. With the ∂ operator in part 2 you keep only the shape on the right. And McBride's Δ operator gives you a choice of what do do with the left and right hand sides.
1. Regular Expressions
Every regular expression defines a language - the set of strings exactly matching the expression. Given a language L made from the symbols in S, define ∂sL, where s is a symbol in S, to be the language made by taking all of the prefixes in L that end just before an s, deleting the final s. For example, if the language were L={MADAM} then ∂ML={∅,MADA}, ∂AL={M,MAD} and ∂DL={MA}. We can write the regular expressions for these languages as 1+MADA, M+MAD and MA. So in this case, applying ∂s trivially gives another regular language. So here's a problem: is the set of prefixes of a regular language L, ending at s, also regular?
Let's use ∂s to define an operation on regular expressions that computes the regular expression for the prefixes.
Consider a regular expression of the form ab, where a and b are regular expresions. A prefix for the language ending at symbol s either ands in the 'a' part, corresponding to something matching ∂sa, or it ends in the b part in which case it matches a∂sb.
But so far I've just mentioned finite languages. What about the * operator. Well a prefix in a* must consist of a sequence of strings matching a but end as a prefix of a. Ie. we need ∂s(a*)=a*∂sa.
So it's not hard to see (I hope) that
∂ss = 1
∂ss' = 0 for symbol s'≠s
∂s(a+b) = ∂sa+∂sb
∂s(ab) = ∂sa+a∂sb
∂s(a*)=a*∂sa
works nicely and proves that the answer to the above question is yes.
2. Dissecting types
Rather than regurgitate someone else's words, take a peek at Dissecting Data Structures. Define the operator, acting on types, ∂, by ∂ F X = Δ F X 1, where Δ is my poor man's version of del with a vertical line through it. From the definition of Δ you can see it satisfies:
∂(K A) X = 0
∂Id X = 1
∂(F+G) X=∂F X+∂G X
&part(F×G) X=∂F X×G 1+F X×∂G X
If you read McBride's paper, you'll see that the ∂ operator slices a type in half, throwing away the elements in the right half, keeping just the 'shape' of the right half.
3. Fox's Free Derivatives
Check out the definition of the Fox derivative in section 4 of Free Differential Calculus. The Fox derivative is used to compute the Alexander polynomial of a knot.
But I hope you can see that we have yet another definition that looks very similar. The common theme is differentiation with a twist. When you differentiate a product fg, one term is the usual one, fD(g), but the other term isn't D(f)g but the g is replaced by a drastically simplified version (either 1, or g(1)). Both versions 1 and 2 have a notion of chopping something in half at some point and keeping the left half. (Actually, you could tweak the definition in part 2 so that g is replaced by 1 too, then you'd no longer preserve the shape of the right half of the type and you'd really have a slicing operator, and the analogies would become clearer.)
I just need to relate the * operator in part 1 to the derivative of the inverse in the free derivative. Let me do this in a hand-waving manner: Conceptually, a*=1+a+a²+… which might be considered the same as 1/(1-a). ∂(1/(1-a)) = (using 4(ii)) 1/(1-a)∂a = a*∂a.
So what does it all mean? I've no idea. I'm just pointing out that the Fox derivative, or something like it, has what I think are hitherto unnoticed applications to computer science. Anyway, some of this will become clearer when I post some Haskell code implementing no less than five different types of derivatives of regular expressions (some time in the next week when I have a spare moment), and that should partially answer my question that I posed on λtU.
On further reflection, I can say something about what this means. The way to view derivatives is as an operation that chops things in 'half', destroying something in the middle. The Leibniz rules corresponds to the notion that when you chop a product you must either chop in the left side of the product or the right side. In the usual Leibniz rule you reassemble the pieces on either side - leaving a hole. With the Fox derivative you throw away what's on the right. With the ∂ operator in part 2 you keep only the shape on the right. And McBride's Δ operator gives you a choice of what do do with the left and right hand sides.
Saturday, January 06, 2007
Oriented Fish and Hairy Balls
I have to admit, I have a tendency to write about abstract nonsense here. But I do so for entirely practical reasons - I don't want to run afoul of my employer by mentioning anything that could be construed as a trade secret. But today I thought I'd mention a small application of topology to computer graphics. The reason I can safely mention it is that I won't be revealing a technique or algorithm. Instead, I want to point out the opposite: a proof that a certain algorithm cannot possibly exist.
From time to time, anyone who works in computer graphics is likely to want to implement a function with this specification:
This kind of function is ubiquitous in graphics and most math libraries geared towards graphics that I have seen have some kind of implementation of this. A typical application is as follows: suppose you're animating shoals of fish. Using a variety of methods its easy to generate nice paths that guide the motion of thousands of fish. For example you could assume that the motion of the fish is approximately described by a divergence-free vector field (so that the fish don't 'pile up' anywhere) and then integrate these fields to give streamlines that the fish can follow. Unfortunately there is a slight catch with this. If you have some 3D geometry representing the fish's shape, knowing the position of the fish isn't enough to specify how it looks. You also need to give its orientation. An obvious choice is to orient the fish so that the line from tail to nose points along the flow. But you still need to be able to describe its orientation around this axis. To do this, we need to complete this orientation vector along the fish to an orthogonal basis ie. find a set of mutually orthogonal unit vectors, e1, e2, and e3 such that e1 points from tail to nose. We can easily define e3 to be e1×e2, so if we had the function f above we could write e2=f(e1).
The function f appears in a multitude of other contexts too. It's useful when orienting 'virtual' cameras. For example the user might want to specify that the camera points at a target and have the graphics system select an orientation with this property.
However, anyone who's met these problems immediately hits an issue. Try writing code to do this for yourself if you haven't already. Chances are you'll end up with a conditional branch in your code, and when you flip from one branch to another you'll see it clearly causing ugly flips in the animation. So the above spec needs to be revised to:
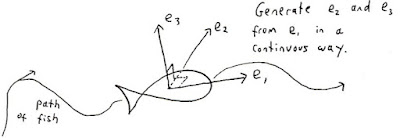
And here's the rub: the Hairy Ball Theorem says there is no such function. So if you're having trouble writing one, it's not because you're not being ingenious enough. It just can't be done! (Though there are lots of other solutions to the animation problems I mention above.) See, topology is useful after all, it can save you wasting your time on impossible tasks.
(Funnily enough though, the best way to see that this is true is using a suitable functor...)
Actually, I think anyone who works in graphics ought to read up on the Hairy Ball Theorem, the Ham Sandwich Theorem and the Borsuk-Ulam theorem as well as learning about the double cover of SO(3) (which I'll write about here in the near future).
That was a public service announcement.
From time to time, anyone who works in computer graphics is likely to want to implement a function with this specification:
Implement a function f:R3→R3 such that for all non-zero x, f(x) is also non-zero and is perpendicular to x.
This kind of function is ubiquitous in graphics and most math libraries geared towards graphics that I have seen have some kind of implementation of this. A typical application is as follows: suppose you're animating shoals of fish. Using a variety of methods its easy to generate nice paths that guide the motion of thousands of fish. For example you could assume that the motion of the fish is approximately described by a divergence-free vector field (so that the fish don't 'pile up' anywhere) and then integrate these fields to give streamlines that the fish can follow. Unfortunately there is a slight catch with this. If you have some 3D geometry representing the fish's shape, knowing the position of the fish isn't enough to specify how it looks. You also need to give its orientation. An obvious choice is to orient the fish so that the line from tail to nose points along the flow. But you still need to be able to describe its orientation around this axis. To do this, we need to complete this orientation vector along the fish to an orthogonal basis ie. find a set of mutually orthogonal unit vectors, e1, e2, and e3 such that e1 points from tail to nose. We can easily define e3 to be e1×e2, so if we had the function f above we could write e2=f(e1).
The function f appears in a multitude of other contexts too. It's useful when orienting 'virtual' cameras. For example the user might want to specify that the camera points at a target and have the graphics system select an orientation with this property.
However, anyone who's met these problems immediately hits an issue. Try writing code to do this for yourself if you haven't already. Chances are you'll end up with a conditional branch in your code, and when you flip from one branch to another you'll see it clearly causing ugly flips in the animation. So the above spec needs to be revised to:
Implement a continuous function f:R3→R3 such that for all non-zero x, f(x) is also non-zero and is perpendicular to x.

And here's the rub: the Hairy Ball Theorem says there is no such function. So if you're having trouble writing one, it's not because you're not being ingenious enough. It just can't be done! (Though there are lots of other solutions to the animation problems I mention above.) See, topology is useful after all, it can save you wasting your time on impossible tasks.
(Funnily enough though, the best way to see that this is true is using a suitable functor...)
Actually, I think anyone who works in graphics ought to read up on the Hairy Ball Theorem, the Ham Sandwich Theorem and the Borsuk-Ulam theorem as well as learning about the double cover of SO(3) (which I'll write about here in the near future).
That was a public service announcement.
Wednesday, December 27, 2006
Tying Knots Generically
A comment by a friend and a puzzle on Lambda the Ultimate made me realise that the function loeb that I defined a few weeks back does have a nice application.
The problem it helps to solve is this: building circular datastructures in Haskell, otherwise known as Tying the Knot. loeb solves this problem in a very generic way that imposes the minimum of restrictions on the user.
Remember how in my previous article I showed how you could view loeb as a kind of spreadsheet evaluator. You have a container of functions and that is converted into another container by applying these functions to the final container. This is a circular definition, we're applying the functions to the final result to get the final result. If we think of the final container as a collection of answers to a bunch of problems, loeb allows each element to be constructed using references to any of the other answers in the container, even if they haven't actually been found yet. This is exactly what we need to make circular references.
Firstly, let's look at doing something similar to the Tying the Knot web page to solve Derek's puzzle. Here potential links are made by using a dictionary structure to allow names of objects to stand for direct references to objects. So define an operator to perform pointwise concatenation of string-valued functions:
Now define lookup into the dictionary, substituting a default value if needed:
And now we can translate some example equations into Haskell by hand. I'm considering define a x *b and define b y *a. Note how it's trivial to write a parser to make these objects because there's nothing circular going on:
We now just apply loeb to get a dictionary containing the actual values:
We can use a similar method to make a doubly linked list. Here is "A", "B" and "C" in a list with each letter pointing to its predecessor and successor if it exists:
b is now a doubly linked list and we can use lft and rt to walk up and down it.
And here's a nice advantage of using loeb. You don't have to restrict yourself to storing information about links in a dictionary. Any functorial container will do. For example here's a doubly linked circular list of the integers from 0 to 99 made without using any names:
Note how working your way up and down zlist is a slow process because you need to use the slow (!!) to access elements. But stepping up and down any element of z takes time O(1). Potentially very useful!
But there is a slight problem with loeb. I'd like to be able to handle errors better and the obvious way to do that is by allowing the use of monads to handle exceptions, for example if a name lookup in a dictionary fails. I attempted to do this as follows:
But attempting to evaluate u overfows the stack. It also failed when I tried modifying it to use MonadFix. So here's a puzzle. Can you write a monadic version of loeb? It seems like something that would be very useful for writing interpreters for programming languages that allow mutually recursive definitions.
So my original intuition a few weeks back was right. Taking an interesting axiom of modal logic, interpreting as a type, and them finding an implementation, did lead to something useful.
By the way, while I was thinking about loeb I was led to consider what I call tautological containers. These are containers where each element tells you how to extricate it from the container. For example, these can be thought of as tautological: (fst,snd), [head,head.tail], [(!!n) | n <- [0..]] and [("a",fromJust . lookup "a"),("b",fromJust . lookup "b")]. Can you see any use for these objects? Are they universal for some category diagram? I have partial answers to these questions but maybe you can make more sense of them than me.
Update: Ocaml version by Matias Giovannini.
> import Maybe
> import Data.Map

> loeb :: Functor a => a (a x -> x) -> a x
> loeb x = fmap (\a -> a (loeb x)) x
The problem it helps to solve is this: building circular datastructures in Haskell, otherwise known as Tying the Knot. loeb solves this problem in a very generic way that imposes the minimum of restrictions on the user.
Remember how in my previous article I showed how you could view loeb as a kind of spreadsheet evaluator. You have a container of functions and that is converted into another container by applying these functions to the final container. This is a circular definition, we're applying the functions to the final result to get the final result. If we think of the final container as a collection of answers to a bunch of problems, loeb allows each element to be constructed using references to any of the other answers in the container, even if they haven't actually been found yet. This is exactly what we need to make circular references.
Firstly, let's look at doing something similar to the Tying the Knot web page to solve Derek's puzzle. Here potential links are made by using a dictionary structure to allow names of objects to stand for direct references to objects. So define an operator to perform pointwise concatenation of string-valued functions:
> f +++ g = \x -> f x ++ g x
Now define lookup into the dictionary, substituting a default value if needed:
And now we can translate some example equations into Haskell by hand. I'm considering define a x *b and define b y *a. Note how it's trivial to write a parser to make these objects because there's nothing circular going on:
> equations = fromList
>     [
>         ("a",const "x"+++lookup "b"),
>         ("b",const "y"+++lookup "a")
>     ] where lookup = Data.Map.findWithDefault ""
We now just apply loeb to get a dictionary containing the actual values:
> values = loeb equations
> a = fromJust $ Data.Map.lookup "a" values
We can use a similar method to make a doubly linked list. Here is "A", "B" and "C" in a list with each letter pointing to its predecessor and successor if it exists:
> data DList a = Nil | Node a (DList a) (DList a) deriving Show
>
> val (Node a _ _) = a
> rt (Node _ _ r) = r
> lft (Node _ l _) = l
>
> nodes = fromList
>    [
>        ("a", \d -> Node "A" Nil (lookup "b" d)),
>        ("b", \d -> Node "B" (lookup "a" d) (lookup "c" d)),
>        ("c", \d -> Node "C" (lookup "b" d) Nil)
>    ] where lookup = Data.Map.findWithDefault Nil
>
> abc = loeb nodes
> b = fromJust $ Data.Map.lookup "b" abc
b is now a doubly linked list and we can use lft and rt to walk up and down it.
And here's a nice advantage of using loeb. You don't have to restrict yourself to storing information about links in a dictionary. Any functorial container will do. For example here's a doubly linked circular list of the integers from 0 to 99 made without using any names:
> zlist = [\z -> Node i (z!!((i-1) `mod` 100)) (z!!((i+1) `mod` 100)) | i <- [0..99]]
> z = loeb zlist
Note how working your way up and down zlist is a slow process because you need to use the slow (!!) to access elements. But stepping up and down any element of z takes time O(1). Potentially very useful!
But there is a slight problem with loeb. I'd like to be able to handle errors better and the obvious way to do that is by allowing the use of monads to handle exceptions, for example if a name lookup in a dictionary fails. I attempted to do this as follows:
> class Monad m => MFunctor m f where
>     fmapM :: (a -> m b) -> f a -> m (f b)

> instance Monad m => MFunctor m [] where
>     fmapM = mapM

> loebM :: (Monad m,MFunctor m a) => a (a x -> m x) -> m (a x)
> loebM x = r where
>     r = do
>         lx <- r
>         fmapM (\a -> a lx) x

> u = loebM [const (Just 1),const (Just 2)]
But attempting to evaluate u overfows the stack. It also failed when I tried modifying it to use MonadFix. So here's a puzzle. Can you write a monadic version of loeb? It seems like something that would be very useful for writing interpreters for programming languages that allow mutually recursive definitions.
So my original intuition a few weeks back was right. Taking an interesting axiom of modal logic, interpreting as a type, and them finding an implementation, did lead to something useful.
By the way, while I was thinking about loeb I was led to consider what I call tautological containers. These are containers where each element tells you how to extricate it from the container. For example, these can be thought of as tautological: (fst,snd), [head,head.tail], [(!!n) | n <- [0..]] and [("a",fromJust . lookup "a"),("b",fromJust . lookup "b")]. Can you see any use for these objects? Are they universal for some category diagram? I have partial answers to these questions but maybe you can make more sense of them than me.
Update: Ocaml version by Matias Giovannini.
Tuesday, December 19, 2006
Evaluating cellular automata is comonadic
Paul Potts's post inspired me to say something about cellular automata too.
So here's the deal: whenever you see large datastructures pieced together from lots of small but similar computations there's a good chance that we're dealing with a comonad. In cellular automata we compute the value of each cell in the next generation by performing a local computation based on the neighbourhood of that cell. So cellular automata look like they might form a good candidate for comonadic evaluation.
I want to work on 'universes' that extend to infinity in both directions. And I want this universe to be constructed lazily on demand. One way of doing that is to represent a 'universe' as a centre point, a list of all elements to the left of that centre point and a list of all elements to the right. Here's a suitable
type:
For example U [-1,-2..] 0 [1,2..] can be thought of as representing all of the integers in sequence.
But this actually contains slightly more information than a list that extends to infinity both ways. The centre point forms a kind of focus of attention. We could shift that focus of attention left or right. For example consider
This represents the same sequence of integers but the focus has been shifted left. So think of the type U x as being a doubly infinite sequence with a cursor. (In fact, this makes it a kind of zipper.)
We can formalise the notion of shifting left and right as follows:
An object of type U is semantically like a C pointer into a const block of memory. You can increment it, decrement it and dereference it using the function I'll call coreturn below.
As U is a kind of list structure, it needs a map. In fact, we can define fmap for it:
Now the fun starts. First I'll bemoan the fact that Comonads aren't in the standard Haskell libraries (at least I don't think they are). So I have to define them myself:
cojoin is the dual to the usual join function. I've chosen to do things the category theoretical way and define =>> in terms of cojoin.
And here's why U forms a Comonad:
Look closely at cojoin. It turns a into a 'universe' of 'universes' where each element is a copy of a shifted left or right a number of times. This is where all the work is happening. The reason we want to do this is as follows: we want to write rules that work on the local neighbourhoods of our universe. We can think of a universe with the cursor pointing at a particular element as being an element with a neighbourhood on each side. For example, we can write a cellular automaton rule like this:
In order to apply this everywhere in the universe we need to apply the rule to each possible shift of the universe. And that's what cojoin does, it constructs a universe of all possible shifts of a. Compare with what I said here. So believe it or not, we've already written the code to evaluate cellular automata. u =>> rule applies the rule to u. The rest is just boring IO:
Lazy infinite structures, comonads, zippers. I think I'm just beginning to get the hang of this functional programming lark! Over Xmas I might feel ready to try writing a piece of code longer than a dozen or so lines.
Anyway, I must end with a credit. I probably wouldn't have come up with this if I hadn't read this paper by Uustalu and Vene.
So here's the deal: whenever you see large datastructures pieced together from lots of small but similar computations there's a good chance that we're dealing with a comonad. In cellular automata we compute the value of each cell in the next generation by performing a local computation based on the neighbourhood of that cell. So cellular automata look like they might form a good candidate for comonadic evaluation.
I want to work on 'universes' that extend to infinity in both directions. And I want this universe to be constructed lazily on demand. One way of doing that is to represent a 'universe' as a centre point, a list of all elements to the left of that centre point and a list of all elements to the right. Here's a suitable
type:
> data U x = U [x] x [x]
For example U [-1,-2..] 0 [1,2..] can be thought of as representing all of the integers in sequence.
But this actually contains slightly more information than a list that extends to infinity both ways. The centre point forms a kind of focus of attention. We could shift that focus of attention left or right. For example consider
U [-2,-3..] (-1) [0,1..]
This represents the same sequence of integers but the focus has been shifted left. So think of the type U x as being a doubly infinite sequence with a cursor. (In fact, this makes it a kind of zipper.)
We can formalise the notion of shifting left and right as follows:
> right (U a b (c:cs)) = U (b:a) c cs
> left  (U (a:as) b c) = U as a (b:c)
An object of type U is semantically like a C pointer into a const block of memory. You can increment it, decrement it and dereference it using the function I'll call coreturn below.
As U is a kind of list structure, it needs a map. In fact, we can define fmap for it:
> instance Functor U where
>    fmap f (U a b c) = U (map f a) (f b) (map f c)
Now the fun starts. First I'll bemoan the fact that Comonads aren't in the standard Haskell libraries (at least I don't think they are). So I have to define them myself:
> class Functor w => Comonad w where
>    (=>>)    :: w a -> (w a -> b) -> w b
>    coreturn :: w a -> a
>    cojoin     :: w a -> w (w a)
>    x =>> f = fmap f (cojoin x)
cojoin is the dual to the usual join function. I've chosen to do things the category theoretical way and define =>> in terms of cojoin.
And here's why U forms a Comonad:
> instance Comonad U where
>    cojoin a = U (tail $ iterate left a) a (tail $ iterate right a)
>    coreturn (U _ b _) = b
Look closely at cojoin. It turns a into a 'universe' of 'universes' where each element is a copy of a shifted left or right a number of times. This is where all the work is happening. The reason we want to do this is as follows: we want to write rules that work on the local neighbourhoods of our universe. We can think of a universe with the cursor pointing at a particular element as being an element with a neighbourhood on each side. For example, we can write a cellular automaton rule like this:
> rule (U (a:_) b (c:_)) = not (a && b && not c || (a==b))
In order to apply this everywhere in the universe we need to apply the rule to each possible shift of the universe. And that's what cojoin does, it constructs a universe of all possible shifts of a. Compare with what I said here. So believe it or not, we've already written the code to evaluate cellular automata. u =>> rule applies the rule to u. The rest is just boring IO:
> shift i u = (iterate (if i<0 then left else right) u) !! abs i
>
> toList i j u = take (j-i) $ half $ shift i u where
>    half (U _ b c) = [b] ++ c
>
> test = let u = U (repeat False) True (repeat False)
>       in putStr $
>          unlines $
>          take 20 $
>          map (map (\x -> if x then '#' else ' ') . toList (-20) 20) $
>          iterate (=>> rule) u
Lazy infinite structures, comonads, zippers. I think I'm just beginning to get the hang of this functional programming lark! Over Xmas I might feel ready to try writing a piece of code longer than a dozen or so lines.
Anyway, I must end with a credit. I probably wouldn't have come up with this if I hadn't read this paper by Uustalu and Vene.
Wednesday, December 13, 2006
Why isn't ListT [] a monad?
Well I'm back from my vacation. But this isn't my personal blog so I think it's time to dive right in. Anything to take my mind off these mosquito bites...
So consider the free semiring R generated by some set S. In other words, S consists of finite sums and products of 0, 1 and elements of S and where the only simplification rules allowed are
For example, consider a term like ab+c(ef+gh). We can use distributivity to multiply this out to ab+cef+cgh. There's not much else we can do to simplify this. Now notice that if you multiply out all of the brackets wherever you can, ie. use distributivity until you can no longer, you end up with an expression that is a sum of terms and each term is a product of generators from S. (The sum of terms may be empty, in which case it's zero, and each of the terms may be a product of zero generators, in which case it is 1). This allows us to write elements of R in a canonical form: as a set of terms where each term is an ordered list of generators. For example, we could write ab+cef+cgh as {[a,b],[c,e,f],[c,g,h]}. Notice how the commutativity of addition is represented by the fact that we're using a set of terms, but each term is a list of generators because we're making no assumption about the commutativity of multiplication.
In Haskell it's more convenient to work with lists. Se we'll represent our running example as [['a','b'],['c','e','f'],['c','g','h']]. So if S is the Haskell type corresponding to our set of generators, then [[S]] can be thought of as the free semiring generated by elements of S, with the proviso that we consider two elements equal if one can be reordered to the other. Note that []=0 and [[]] = 1.
Now suppose that S is itself a free semiring generated by T. Then R = [[ [[T]] ]], modulo ordering. If you think about it, there's a nice way to use the algebraic structure to 'flatten' an element of [[ [[T]] ]] down to an element of [[T]]. R is freely generated by elements of S, in other words it consists of sums of products of elements of S. But the elements of S are themselves sums and products. So we have sums of products of sums of products. I emphasised two words in that sentence. This is because R contains subparts that are products of sums. If we multiply these out in the usual way, we get sums of sums of products of products. Group the sums and products together, and we get back to sums of products. Here's an example: any element of T trivially gives an element of S. So if a,b,c,e,f,g and h are all in T, then a,b,c and ef+gh are all in S and hence are generators of R, so ab+c(ef+gh) is in R. Multiply out and we obviously have the element ab+cef+cgh of S. It's not hard to see how this generalises to map any element of S back down to T. So we have maps
Look to you like a monad? Of course it does! :-) But what monad is it?
First, let's implement the map [[ [[T]] ]] -> [[T]]. After tinkering I came up with
We can test it out
It multiplies out exactly the way we want.
Now compare with running this:
In other words, apart from the ListT fluff, join for ListT [] is flatten. So if we consider lists as a mechanism to represent sets, ListT [] is revealed as the monad of semirings. I'm not sure, but I think that historically this is where monads originally came from. Certainly there are many papers on the relationship between monads and algebraic structures like semirings.
And now I can answer my original question. In a semiring, addition is commutative, so the order of terms doesn't matter. But in ListT [], we're using lists, and order does matter in a list. So if we do take order into account, then really ListT [] is the monad of semirings where both addition and multiplication is non-commutative. And here's the problem: in general, there is no such thing as a freely generated semiring with non-commutative addition.
Here's why: consider the expression ((a+b)+(a+b))*((a+b)+(a+b)). Multiply out the inner parentheses first and we get
Now multiply out the outer parentheses first and we get
The terms are coming out in a different order. Essentially distributivity doesn't work in a semiring with non-commutative addition.
This translates directly into failure of one of the monad laws. First write our expression as an object of type ListT []:
u = a+b
v = (a+b)+(a+b)
w = ((a+b)+(a+b))*((a+b)*(a+b))
join multiplies out parentheses. So working from the outer parentheses inwards we can use:
Working outwards from the inner parentheses we get:
(Note how I use fmap to 'duck down' through the outer layer of parentheses so as to multiply out each of the subexpressions first.)
Evaluate go1 and go2 and you'll see that they corresponds to the two ways of multiplying out that I gave above. And more importantly, the values of expanded1 and expanded2 aren't equal, meaning that join . join = join . fmap join isn't satisfied. You may recognise this: it's one of the monad laws. (At least it's one of the monad laws written the way category theorists write them.) So we ain't got no monad.
I think this is now a fairly complete analysis of what ListT [] is all about. So one obvious remaining question is: where do games come into all this? The answer is that games form a semiring in a way that I haven't seen documented anywhere (though is surely common knowledge). I'd explain but I've run out of time...
Note that the reason ListT [] isn't a monad is that [] isn't commutative, in some sense. This has been observed many times in the past. Two papers mentioning this are this and this.
I actually figured out all of this stuff before this. I realised that the trees I was scribbling on the backs of my envelopes to represent elements of semirings could actually be generalised to just about any kind of tree, so I wrote about the general case first.
I prefer my example of ListT [] failing to be a monad to the examples given here. The latter make use of the IO monad so they aren't quite as 'pure'.
So consider the free semiring R generated by some set S. In other words, S consists of finite sums and products of 0, 1 and elements of S and where the only simplification rules allowed are
a+0=a, a+b=b+a, a+(b+c)=(a+b)+c
a1=1, a(bc) = (ab)c
a(b+c) = ab+ac and (a+b)c = ac+bc.
For example, consider a term like ab+c(ef+gh). We can use distributivity to multiply this out to ab+cef+cgh. There's not much else we can do to simplify this. Now notice that if you multiply out all of the brackets wherever you can, ie. use distributivity until you can no longer, you end up with an expression that is a sum of terms and each term is a product of generators from S. (The sum of terms may be empty, in which case it's zero, and each of the terms may be a product of zero generators, in which case it is 1). This allows us to write elements of R in a canonical form: as a set of terms where each term is an ordered list of generators. For example, we could write ab+cef+cgh as {[a,b],[c,e,f],[c,g,h]}. Notice how the commutativity of addition is represented by the fact that we're using a set of terms, but each term is a list of generators because we're making no assumption about the commutativity of multiplication.
In Haskell it's more convenient to work with lists. Se we'll represent our running example as [['a','b'],['c','e','f'],['c','g','h']]. So if S is the Haskell type corresponding to our set of generators, then [[S]] can be thought of as the free semiring generated by elements of S, with the proviso that we consider two elements equal if one can be reordered to the other. Note that []=0 and [[]] = 1.
Now suppose that S is itself a free semiring generated by T. Then R = [[ [[T]] ]], modulo ordering. If you think about it, there's a nice way to use the algebraic structure to 'flatten' an element of [[ [[T]] ]] down to an element of [[T]]. R is freely generated by elements of S, in other words it consists of sums of products of elements of S. But the elements of S are themselves sums and products. So we have sums of products of sums of products. I emphasised two words in that sentence. This is because R contains subparts that are products of sums. If we multiply these out in the usual way, we get sums of sums of products of products. Group the sums and products together, and we get back to sums of products. Here's an example: any element of T trivially gives an element of S. So if a,b,c,e,f,g and h are all in T, then a,b,c and ef+gh are all in S and hence are generators of R, so ab+c(ef+gh) is in R. Multiply out and we obviously have the element ab+cef+cgh of S. It's not hard to see how this generalises to map any element of S back down to T. So we have maps
T -> [[T]] (by trivial inclusion of generators)
[[ [[T]] ]] -> [[T]] (by above argument)
Look to you like a monad? Of course it does! :-) But what monad is it?
First, let's implement the map [[ [[T]] ]] -> [[T]]. After tinkering I came up with
> import Control.Monad.List

> flatten x = concatMap (map concat . sequence) x
We can test it out
> x = [[ [['a']],[['b']] ], [ [['c']],[['e','f'],['g','h']] ]]
> test1 = flatten x
It multiplies out exactly the way we want.
Now compare with running this:
> x' = ListT [[ ListT [['a']],ListT [['b']] ],
>           [ ListT [['c']],ListT [['e','f'],['g','h']] ]]
> test2 = runListT $ join x'
In other words, apart from the ListT fluff, join for ListT [] is flatten. So if we consider lists as a mechanism to represent sets, ListT [] is revealed as the monad of semirings. I'm not sure, but I think that historically this is where monads originally came from. Certainly there are many papers on the relationship between monads and algebraic structures like semirings.
And now I can answer my original question. In a semiring, addition is commutative, so the order of terms doesn't matter. But in ListT [], we're using lists, and order does matter in a list. So if we do take order into account, then really ListT [] is the monad of semirings where both addition and multiplication is non-commutative. And here's the problem: in general, there is no such thing as a freely generated semiring with non-commutative addition.
Here's why: consider the expression ((a+b)+(a+b))*((a+b)+(a+b)). Multiply out the inner parentheses first and we get
(a+b+a+b)*(a+b+a+b)
= a*a+a*b+a*a+a*b+…
Now multiply out the outer parentheses first and we get
(a+b)*(a+b)+(a+b)*(a+b)+(a+b)*(a+b)+(a+b)*(a+b)
= a*a+a*b+b*a+b*b+…
The terms are coming out in a different order. Essentially distributivity doesn't work in a semiring with non-commutative addition.
This translates directly into failure of one of the monad laws. First write our expression as an object of type ListT []:
u = a+b
> u = ListT [["a"],["b"]]
v = (a+b)+(a+b)
> v = ListT [[u],[u]]
w = ((a+b)+(a+b))*((a+b)*(a+b))
> w = ListT [[v,v]]
join multiplies out parentheses. So working from the outer parentheses inwards we can use:
> expanded1 = join $ join w
> go1 = runListT expanded1
Working outwards from the inner parentheses we get:
> expanded2 = join $ fmap join w
> go2 = runListT expanded2
(Note how I use fmap to 'duck down' through the outer layer of parentheses so as to multiply out each of the subexpressions first.)
Evaluate go1 and go2 and you'll see that they corresponds to the two ways of multiplying out that I gave above. And more importantly, the values of expanded1 and expanded2 aren't equal, meaning that join . join = join . fmap join isn't satisfied. You may recognise this: it's one of the monad laws. (At least it's one of the monad laws written the way category theorists write them.) So we ain't got no monad.
I think this is now a fairly complete analysis of what ListT [] is all about. So one obvious remaining question is: where do games come into all this? The answer is that games form a semiring in a way that I haven't seen documented anywhere (though is surely common knowledge). I'd explain but I've run out of time...
Note that the reason ListT [] isn't a monad is that [] isn't commutative, in some sense. This has been observed many times in the past. Two papers mentioning this are this and this.
I actually figured out all of this stuff before this. I realised that the trees I was scribbling on the backs of my envelopes to represent elements of semirings could actually be generalised to just about any kind of tree, so I wrote about the general case first.
I prefer my example of ListT [] failing to be a monad to the examples given here. The latter make use of the IO monad so they aren't quite as 'pure'.
Saturday, December 02, 2006
A Yonedic Addendum
Firstly, blogger.com seems to have temporarily lost the preview feature so I'm writing this as blind HTML. I won't know exactly how it looks until I hit 'publish'. (It's not real HTML so it's no good just pasting into a web page.)
I kept meaning to follow up on my earlier post about the Yoneda lemma by working out if each of the three examples I considered were Theorems for Free! But it's tedious work to decrypt the free theorem as it is generated by the procedure in Wadler's paper. But then I suddenly realised that lambdabot could do the work for me. I looked at all three examples that I gave, but I'll just spell out the details for the last one here. Consider machines of type forall b. (A -> b) -> C -> b. What free theorem do we get from that? If you don't have lambdabot you can see here. But first I need to point out either a limitation in that free theorem prover, or a limitation of my understanding of it. It seems to attach a forall for every free variable. But I want to have A and C fixed, but unknown. It makes a difference. In the end a cheated by considering the type
(Float -> b) -> Char -> b
The free theorem is
where t1 :: forall b. (Float -> b) -> Char -> b. With a tiny bit of work we can deduce
Using my earlier notation, that is essentially check3 . uncheck3 = id. Similar results followed for the other examples. So I conjecture that for functors F, the free theorems for (a -> b) -> F b are just proofs of the Yoneda lemma (well, the less trivial direction at least). I'm guessing this is all blindingly obvious to type theorists but it's all new to me.
Anyway, a couple of thoughts come to mind. This stuff is all about parametricty, and part of what makes this work is that any polymorphic function (with the same restrictions in Theorems for Free!) that looks like a natural transformation is a natural transformation in the category of Haskell types. But Theorems for Free! also talks about functions that don't look like natural transformations. For example consider the type (a->a)->(a->a). The free theorem reflects the fact that any such function must simply raise its argument to some non-negative integer power. But it seems to me that when the free theorem is written in point-free style, then functions (ie. functions that map objects to arrows like the way natural transformations do) in a general category that satisfy this theorem are also in some sense 'natural'. So is there a wider sense of 'natural' in a category that I should know about?
What I find interesting here isn't necessarily the type theory in itself. What I think is interesting is that the type theory provides nice intuition for other applications for the Yoneda lemma, and indeed other parts of category theory. Up to now, my spare time reading of computer science hasn't really fed back back into my understanding of other branches of mathematics. But this time it has. Even though the category of Haskell types and functions looks a lot like Set, it has nice properties of its own that deepen your understanding of categories in general.
Anyway, while I'm on the subject of things Yonedic, here's an application of category theory to the composition of music. The author s claim the Yoneda lemma has applications in this field. Yes, you read that correctly. No, it's not April 1. In fact, I discovered this by doing a google code search on yoneda.
One last thing. I should credit augustss for getting me to think about the mathematical significance of parametricity in the first place. That was 6 months ago. Trying to do mathematics when you only have a couple of hours free a week is slow going.
I kept meaning to follow up on my earlier post about the Yoneda lemma by working out if each of the three examples I considered were Theorems for Free! But it's tedious work to decrypt the free theorem as it is generated by the procedure in Wadler's paper. But then I suddenly realised that lambdabot could do the work for me. I looked at all three examples that I gave, but I'll just spell out the details for the last one here. Consider machines of type forall b. (A -> b) -> C -> b. What free theorem do we get from that? If you don't have lambdabot you can see here. But first I need to point out either a limitation in that free theorem prover, or a limitation of my understanding of it. It seems to attach a forall for every free variable. But I want to have A and C fixed, but unknown. It makes a difference. In the end a cheated by considering the type
(Float -> b) -> Char -> b
The free theorem is
h1 (f1 x2) = g1 x2) => h1 (t1 f1 x1) = t1 g1 x1
where t1 :: forall b. (Float -> b) -> Char -> b. With a tiny bit of work we can deduce
t1 h1 = h1 . t1 id.
Using my earlier notation, that is essentially check3 . uncheck3 = id. Similar results followed for the other examples. So I conjecture that for functors F, the free theorems for (a -> b) -> F b are just proofs of the Yoneda lemma (well, the less trivial direction at least). I'm guessing this is all blindingly obvious to type theorists but it's all new to me.
Anyway, a couple of thoughts come to mind. This stuff is all about parametricty, and part of what makes this work is that any polymorphic function (with the same restrictions in Theorems for Free!) that looks like a natural transformation is a natural transformation in the category of Haskell types. But Theorems for Free! also talks about functions that don't look like natural transformations. For example consider the type (a->a)->(a->a). The free theorem reflects the fact that any such function must simply raise its argument to some non-negative integer power. But it seems to me that when the free theorem is written in point-free style, then functions (ie. functions that map objects to arrows like the way natural transformations do) in a general category that satisfy this theorem are also in some sense 'natural'. So is there a wider sense of 'natural' in a category that I should know about?
What I find interesting here isn't necessarily the type theory in itself. What I think is interesting is that the type theory provides nice intuition for other applications for the Yoneda lemma, and indeed other parts of category theory. Up to now, my spare time reading of computer science hasn't really fed back back into my understanding of other branches of mathematics. But this time it has. Even though the category of Haskell types and functions looks a lot like Set, it has nice properties of its own that deepen your understanding of categories in general.
Anyway, while I'm on the subject of things Yonedic, here's an application of category theory to the composition of music. The author s claim the Yoneda lemma has applications in this field. Yes, you read that correctly. No, it's not April 1. In fact, I discovered this by doing a google code search on yoneda.
One last thing. I should credit augustss for getting me to think about the mathematical significance of parametricity in the first place. That was 6 months ago. Trying to do mathematics when you only have a couple of hours free a week is slow going.
BTW I'm in Mexico on vacation for the next week and a half. On the plane I'll be reading (at least) the papers on cake cutting and Venn diagrams mentioned here: Ars Mathematica.
Friday, November 24, 2006
How Telescopes Really Work and What You Can See Through Them
For my birthday a few weeks ago (40!) I received an 8" dobsonian telescope from my wife and her family. Of course the weather here in Northern California suddenly took a turn for the worse immediately after I brought it home, but there have still been a few clear nights.
One of the frustrating things about astronomy is that what you can see with an amateur telescope from your back yard in a well lit city is quite different from what you can see from the wilderness with a telescope the size of a truck. Unfortunately, even a great book like The Backyard Astronomer's Guide is dominated by the latter type of picture (like that fantasic picture of the Andromeda galaxy on its cover). So I thought I'd tell it like it really is and give you an idea of what you can see from my location.
Before that, I want to mention something about telescopes. My telescope is a Newtonian reflector and if you look at the pictures on Wikipedia you'll notice that the secondary mirror forms an obstruction that blocks some of the light entering the telescope. A frequently asked question is "why can't you see the obstruction through the scope"? In fact, if you put your hand in front of the aperture the effect on what you see, if the image is in focus, is negligible, just a little darkening. The explanation is very simple, but nobody seems to phrase it the same as me.
The idea is this: a lens, that's in focus, is a device that converts direction into position. Suppose the telescope is oriented along the x-axis. Think of a ray of light as having the equation y=mx+c. Think of m as the ray direction and c as its position. If that ray passes through a lens or mirror and is projected onto a screen, denote the position at which it arrives on the screen by f(m,c). It's clearly a function of m and c. The crucial point is that for a screen at precisely the focal length away from the lens or mirror, f(m,c) is independent of c. That's the raison d'être of a telescope. All rays with gradient m arrive at the same point. So we end up with a bright image because we can collect lots of rays coming from the same direction. But also, any information about the ray's position, ie. c, has been erased. Information about the shape of the obstruction is positional information contained in c. This has been erased, and hence you can't see the obstruction. In practice you really need to consider primary lens (or mirror), plus eyepiece, plus lens of the eye projecting onto the retina, but the principle is the same. For the more formally inclined, the erasure of c information corresponds to a zero in a transfer matrix.
In brief: a lens or mirror focussed on infinity is a position eraser.
My first two subjects were probably the same as every other amateur astronomer. I started with the Andromeda galaxy. Through binoculars it looks like a faint fuzzy blob. And here's the truth of how it looks through a telescope: it looks like a fuzzy blob, at least from a well lit city. I couldn't make out any kind of structure at all, let alone spiral arms. It didn't even look elliptical, just a circular blob with brightness falling off radially from the centre. I also saw one of its neighbours, M32 or M110. At first I thought that the fuzzy blob was the galaxy and that I needed more magnification to see detail. But now I think that I was seeing just the core of the Andromeda galaxy with the arms filling a wider area but remaining invisible because they're no brighter that the sky in my part of the world.
The Orion nebula, on the other hand, was stunning! In outline, it looked remarkably like the picture at wikipedia, but without the colour. When I switched to using a filter (a narrow bandpass Lumicon UHC filter) it became even clearer. Not only could I clearly see the shape of the nebula but I could also see structure all the way through the cloud. It looked even better after I'd been viewing it for a while, probably as my eyes became better adapted to the dark. This was the best thing I've seen through a telescope ever!
I'll mention the last thing I looked at: γ Andromedae, otherwise known as Almach. It's a binary star system that can't be resolved with the naked eye. I used a wide field of view lens and was disappointed to see that it still looked like a single star. But then I switched eyepieces and I saw it - a beautiful pair of stars, one brighter and yellowy orange and the other deep blue. You read about the colour of stars but it's often a disappointment. A single star on its own tends to look white with a hint of colour because the eye doesn't register colour well in such low light conditions. But when you see two contrasting stars so close together it makes a world of difference. The deep blue of the smaller star was unmistakable and the blue really was astonishingly blue. That must be quite a sight for the γ Andromedans. But I should add that the blue star is in fact a triple star system in its own right, so γ Andromedae is actually a quadruple star system. I was unable to resolve more stars than two (and you can only tell there are four by inference from spectrography, not direct viewing).
I also tried to find the Crab Nebula. I'm 99% sure that I was pointing at the right part of the sky and I did in fact see a faint smudge just at the limits of my perception. I had a jiggle the telescope around a bit just to be sure I wasn't imagining it, but sure enough, it appeared to be attached to the sky, not the scope or my eyes. But it certainly didn't look like the pictures.
Anyway, now you have a better idea of what you can see from a city.
One of the frustrating things about astronomy is that what you can see with an amateur telescope from your back yard in a well lit city is quite different from what you can see from the wilderness with a telescope the size of a truck. Unfortunately, even a great book like The Backyard Astronomer's Guide is dominated by the latter type of picture (like that fantasic picture of the Andromeda galaxy on its cover). So I thought I'd tell it like it really is and give you an idea of what you can see from my location.
How Telescopes Work
Before that, I want to mention something about telescopes. My telescope is a Newtonian reflector and if you look at the pictures on Wikipedia you'll notice that the secondary mirror forms an obstruction that blocks some of the light entering the telescope. A frequently asked question is "why can't you see the obstruction through the scope"? In fact, if you put your hand in front of the aperture the effect on what you see, if the image is in focus, is negligible, just a little darkening. The explanation is very simple, but nobody seems to phrase it the same as me.
The idea is this: a lens, that's in focus, is a device that converts direction into position. Suppose the telescope is oriented along the x-axis. Think of a ray of light as having the equation y=mx+c. Think of m as the ray direction and c as its position. If that ray passes through a lens or mirror and is projected onto a screen, denote the position at which it arrives on the screen by f(m,c). It's clearly a function of m and c. The crucial point is that for a screen at precisely the focal length away from the lens or mirror, f(m,c) is independent of c. That's the raison d'être of a telescope. All rays with gradient m arrive at the same point. So we end up with a bright image because we can collect lots of rays coming from the same direction. But also, any information about the ray's position, ie. c, has been erased. Information about the shape of the obstruction is positional information contained in c. This has been erased, and hence you can't see the obstruction. In practice you really need to consider primary lens (or mirror), plus eyepiece, plus lens of the eye projecting onto the retina, but the principle is the same. For the more formally inclined, the erasure of c information corresponds to a zero in a transfer matrix.
In brief: a lens or mirror focussed on infinity is a position eraser.
And What You Can See Through Them
Andromeda Galaxy
My first two subjects were probably the same as every other amateur astronomer. I started with the Andromeda galaxy. Through binoculars it looks like a faint fuzzy blob. And here's the truth of how it looks through a telescope: it looks like a fuzzy blob, at least from a well lit city. I couldn't make out any kind of structure at all, let alone spiral arms. It didn't even look elliptical, just a circular blob with brightness falling off radially from the centre. I also saw one of its neighbours, M32 or M110. At first I thought that the fuzzy blob was the galaxy and that I needed more magnification to see detail. But now I think that I was seeing just the core of the Andromeda galaxy with the arms filling a wider area but remaining invisible because they're no brighter that the sky in my part of the world.
Orion Nebula
The Orion nebula, on the other hand, was stunning! In outline, it looked remarkably like the picture at wikipedia, but without the colour. When I switched to using a filter (a narrow bandpass Lumicon UHC filter) it became even clearer. Not only could I clearly see the shape of the nebula but I could also see structure all the way through the cloud. It looked even better after I'd been viewing it for a while, probably as my eyes became better adapted to the dark. This was the best thing I've seen through a telescope ever!
Almach
I'll mention the last thing I looked at: γ Andromedae, otherwise known as Almach. It's a binary star system that can't be resolved with the naked eye. I used a wide field of view lens and was disappointed to see that it still looked like a single star. But then I switched eyepieces and I saw it - a beautiful pair of stars, one brighter and yellowy orange and the other deep blue. You read about the colour of stars but it's often a disappointment. A single star on its own tends to look white with a hint of colour because the eye doesn't register colour well in such low light conditions. But when you see two contrasting stars so close together it makes a world of difference. The deep blue of the smaller star was unmistakable and the blue really was astonishingly blue. That must be quite a sight for the γ Andromedans. But I should add that the blue star is in fact a triple star system in its own right, so γ Andromedae is actually a quadruple star system. I was unable to resolve more stars than two (and you can only tell there are four by inference from spectrography, not direct viewing).
I also tried to find the Crab Nebula. I'm 99% sure that I was pointing at the right part of the sky and I did in fact see a faint smudge just at the limits of my perception. I had a jiggle the telescope around a bit just to be sure I wasn't imagining it, but sure enough, it appeared to be attached to the sky, not the scope or my eyes. But it certainly didn't look like the pictures.
Anyway, now you have a better idea of what you can see from a city.
Monday, November 20, 2006
From Löb's Theorem to Spreadsheet Evaluation
> import Control.Monad.Reader
I've run 3 miles, the Thanksgiving turkey's in the oven, now I just need to do something impossible before I can have breakfast.
As I've mentioned in the past, sometimes you can write useful Haskell code merely by writing something that type checks successfully. Often there's only one way to write the code to have the correct type. Going one step further: the Curry-Howard isomorphism says that logical propositions corresponds to types. So here's a way to write code: pick a theorem, find the corresponding type, and find a function of that type.
One area that seems fruitful for this approach is modal logic. The axioms of various modal logics correspond to the types of familiar objects in Haskell. For example the distribution axiom:
Looks just like the type of ap :: (Monad m) => m (a -> b) -> m a -> m b.
So I'm looking at the books on my shelf and there's The Logic of Provability by Boolos. It's about a kind of modal logic called provability logic in which □a roughly means "a is provable". One of the axioms of this logic is a theorem known as Löb's theorem.
Before getting onto Löb's Theorem, I should mention Curry's Paradox. (Before today I didn't know Haskell Curry had a paradox associated with his name - though I've met the paradox itself before as it got me into trouble at (high) school once...) It goes like this:
Let S be the proposition "If S is true, Santa Claus exists".
Suppose
Then
So, still assuming our hypothesis, we have
And hence
In other words, assuming S is true, it follows that Santa Claus
exists. In otherwords, we have proved
regardless of the hypothesis.
But that's just a restatement of S so we have proved
and hence that
Fortunately we can't turn this into a rigorous mathematical proof though we can try, and see where it fails. In order to talk about whether or not a proposition is true we have to use some kind of Gödel numbering scheme to turn propositions into numbers and then if a proposition has number g, we need a function True so that True(g)=1 if g is the Gödel number of something true and 0 otherwise. But because of Tarski's proof of the indefinability of truth, we can't do this (to be honest, the argument above should be enough to convince you of this, unless you believe in Santa). On the other hand, we can replace True with Provable, just like in Gödel's incompleteness theorems, because provability is just a statement about deriving strings from strings using rewrite rules. If we do this, the above argument (after some work) turns into a valid proof - in fact, a proof of Löb's theorem. Informally it says that if it is provable that "P is provable implies P" then P is provable. We did something similar above with P="Santa Claus exists". In other words
So I'm going to take that as my theorem from which I'll derive a type. But what should □ become in Haskell? Let's take the easy option, we'll defer that decision until later and assume as little as possible. Let's represent □ by a type that is a Functor. The defining property of a functor corresponds to the theorem □(a→b)→□a→□b.
So now to actually find an implementation of this.
Suppose a is some kind of container. The argument of loeb is a container of functions. They are in fact functions that act on the return type of loeb. So we have a convenient object for these functions to act on, we feed the return value of loeb back into each of the elements of the argument in turn. Haskell, being a lazy language, doesn't mind that sort of thing. So here's a possible implementation:
Informally you can think of it like this: the parts are all functions of the whole and loeb resolves the circularity. Anyway, when I wrote that, I had no idea what loeb did.
So here's one of the first examples I wrote to find out:
loeb test is [2,2]. We have set the second element to equal the first one and the first one is the length of the list. Even though element 1 depends on element 0 which in turn depends on the size of the entire list containing both of them, this evaluates fine. Note the neat way that the second element refers to something outside of itself, the previous element in the list. To me this suggests the way cells in a spreadsheet refer to other cells. So with that in mind, here is a definition I found on the web. (I'm sorry, I want to credit the author but I can't find the web site again):
With these definitions we can add, multiply and negate Num valued
functions. For example:
Armed with that we can define something ambitious like the following:
Think of it as a spreadsheet with (!!n) being a reference to cell number n. Note the way it has forward and backward references. And what kind of spreadsheet would it be without the sum function? To evaluate the spreadsheet we just use loeb test. So loeb is the spreadsheet evaluation function.
Now don't get the wrong idea. I'm not claiming that there's a deep connection betwen Löb's theorem and spreadsheet evaluation (though there is a vague conceptual similarity as both rely on a notion of borrowing against the future). Provability logic (as defined by Boolos) is classical, not intuitionistic. But I definitely found it interesting the way I was led directly to this function by some abstract nonsense.
Anyway, happy Thanksgiving!
PS There are other uses for loeb too. Check out this implementation of factorial which shows loeb to be usable as a curious monadic variant of the Y combinator:
I've run 3 miles, the Thanksgiving turkey's in the oven, now I just need to do something impossible before I can have breakfast.
As I've mentioned in the past, sometimes you can write useful Haskell code merely by writing something that type checks successfully. Often there's only one way to write the code to have the correct type. Going one step further: the Curry-Howard isomorphism says that logical propositions corresponds to types. So here's a way to write code: pick a theorem, find the corresponding type, and find a function of that type.
One area that seems fruitful for this approach is modal logic. The axioms of various modal logics correspond to the types of familiar objects in Haskell. For example the distribution axiom:
□(a→b)→(□a→□b)
Looks just like the type of ap :: (Monad m) => m (a -> b) -> m a -> m b.
So I'm looking at the books on my shelf and there's The Logic of Provability by Boolos. It's about a kind of modal logic called provability logic in which □a roughly means "a is provable". One of the axioms of this logic is a theorem known as Löb's theorem.
Before getting onto Löb's Theorem, I should mention Curry's Paradox. (Before today I didn't know Haskell Curry had a paradox associated with his name - though I've met the paradox itself before as it got me into trouble at (high) school once...) It goes like this:
Let S be the proposition "If S is true, Santa Claus exists".
Suppose
S is true.
Then
If S is true, Santa Claus exists.
So, still assuming our hypothesis, we have
S is true and if S is true, Santa Claus exists.
And hence
Santa Claus exists.
In other words, assuming S is true, it follows that Santa Claus
exists. In otherwords, we have proved
If S is true then Santa Claus exists
regardless of the hypothesis.
But that's just a restatement of S so we have proved
S is true
and hence that
Santa Claus exists.
Fortunately we can't turn this into a rigorous mathematical proof though we can try, and see where it fails. In order to talk about whether or not a proposition is true we have to use some kind of Gödel numbering scheme to turn propositions into numbers and then if a proposition has number g, we need a function True so that True(g)=1 if g is the Gödel number of something true and 0 otherwise. But because of Tarski's proof of the indefinability of truth, we can't do this (to be honest, the argument above should be enough to convince you of this, unless you believe in Santa). On the other hand, we can replace True with Provable, just like in Gödel's incompleteness theorems, because provability is just a statement about deriving strings from strings using rewrite rules. If we do this, the above argument (after some work) turns into a valid proof - in fact, a proof of Löb's theorem. Informally it says that if it is provable that "P is provable implies P" then P is provable. We did something similar above with P="Santa Claus exists". In other words
□(□P→P)→□P.
So I'm going to take that as my theorem from which I'll derive a type. But what should □ become in Haskell? Let's take the easy option, we'll defer that decision until later and assume as little as possible. Let's represent □ by a type that is a Functor. The defining property of a functor corresponds to the theorem □(a→b)→□a→□b.
> loeb :: Functor a => a (a x -> x) -> a x
So now to actually find an implementation of this.
Suppose a is some kind of container. The argument of loeb is a container of functions. They are in fact functions that act on the return type of loeb. So we have a convenient object for these functions to act on, we feed the return value of loeb back into each of the elements of the argument in turn. Haskell, being a lazy language, doesn't mind that sort of thing. So here's a possible implementation:
> loeb x = fmap (\a -> a (loeb x)) x
Informally you can think of it like this: the parts are all functions of the whole and loeb resolves the circularity. Anyway, when I wrote that, I had no idea what loeb did.
So here's one of the first examples I wrote to find out:
> test1 = [length,\x -> x!!0]
loeb test is [2,2]. We have set the second element to equal the first one and the first one is the length of the list. Even though element 1 depends on element 0 which in turn depends on the size of the entire list containing both of them, this evaluates fine. Note the neat way that the second element refers to something outside of itself, the previous element in the list. To me this suggests the way cells in a spreadsheet refer to other cells. So with that in mind, here is a definition I found on the web. (I'm sorry, I want to credit the author but I can't find the web site again):
> instance Show (x -> a)
> instance Eq (x -> a)

> instance (Num a,Eq a) => Num (x -> a) where
>     fromInteger = const . fromInteger
>     f + g = \x -> f x + g x
>     f * g = \x -> f x * g x
>     negate = (negate .)
>     abs = (abs .)
>     signum = (signum .)
With these definitions we can add, multiply and negate Num valued
functions. For example:
> f x = x*x
> g x = 2*x+1

> test2 = (f+g) 3
Armed with that we can define something ambitious like the following:
> test3 = [ (!!5), 3, (!!0)+(!!1), (!!2)*2, sum . take 3, 17]
Think of it as a spreadsheet with (!!n) being a reference to cell number n. Note the way it has forward and backward references. And what kind of spreadsheet would it be without the sum function? To evaluate the spreadsheet we just use loeb test. So loeb is the spreadsheet evaluation function.
Now don't get the wrong idea. I'm not claiming that there's a deep connection betwen Löb's theorem and spreadsheet evaluation (though there is a vague conceptual similarity as both rely on a notion of borrowing against the future). Provability logic (as defined by Boolos) is classical, not intuitionistic. But I definitely found it interesting the way I was led directly to this function by some abstract nonsense.
Anyway, happy Thanksgiving!
PS There are other uses for loeb too. Check out this implementation of factorial which shows loeb to be usable as a curious monadic variant of the Y combinator:
> fact n = loeb fact' n where
>     fact' 0 = return 1
>     fact' n = do
>         f <- ask
>         return $ n*f (n-1)
Saturday, November 18, 2006
Oliver Heaviside
A while back I mentioned that I recently found out that Heaviside was responsible for a bunch of mathematical techniques I've known since my training for the Cambridge entrance exam. I decided to read more about Heaviside and I've just finished this book on the Victorian mathematical physicist, Oliver Heaviside. There's a bit of information about Heaviside on the web, but I thought I'd mention two highlights from this book that may hint at why he was a genius ahead of his time.
There's an example of Heaviside style operational calculus in the link I posted to above. One of the reasons I became interested in this subject again is that I was getting into electronics and I wanted to simplify computations of properties of simple linear circuits. I had this crazy idea that capacitors and inductors could be treated as resistors whose resistance is differential operator valued. Turns out that this wasn't an original move. This is exactly what Heaviside did well over 100 years ago and it was the secret weapon he used for much of his work. He could solve a wide array of ordinary and partial differential equations with ease. Very briefly, his idea was to write the differential operator d/dx as the symbol p and then treat p much like a conventional algebraic variable. He turned differential equations into ordinary algebraic equations.
A great example of this was when he studied the electrical signal that emerges from a long cable as a function of what was sent into the other end. If W is the outgoing signal, and V is the incoming signal, he showed that in his model, W = √(A+Bp)/√(C+Dp) V, for some constants A, B, C and D, that depend on the properties of the cable. At first sight this is meaningless - what is the meaning of the square root of a differential operator? Heaviside had ways to deal with these things, but that's not what he did here. He noticed that if he picked A, B, C and D such that A/B=C/D then he could cancel the p from top and bottom. The net effect was that if this condition held, the signal emerging was the same as the signal entering (apart from a time delay). In physical terms this meant that adding inductance to a long cable would allow it to carry the signal without distorting it. His contemporaries had been declaring long-distance telegraphy impossible because inductance would distort the signal, but here was Heaviside suggesting that inductors be added. The British Post Office ignored Heaviside's claims and it was left to a physicist in the US to put his ideas into practice - ideas that today formed the backbone for the nascent global telecommunications industry. Heaviside couldn't even get much of his work published because mathematicians like Burnside (boo! hiss!) rejected it as unrigorous. Needless to say, Heaviside died a bitter neglected old man...
I'm fascinated by some of the theoretical clues about relativity that were appearing before Einstein. There were obvious results like the Michelson-Morley experiment and the Lorentz-Fitzgerald contraction proposed to explain it. But there were clues in other places too. HG Wells, in The Time Machine, said "There is no difference between Time and any of the three dimensions of Space except that our consciousness moves along it", so we already have a popularisation of the idea of a symmetry between space and time. Heaviside spent much of his time working with Maxwell's equations (which should really be called Heaviside's equations) which inherently has Lorentz group symmetry. This means that any physical predictions made from Maxwell's equations must also have Lorentz invariance. As nobody had explicitly recognised this as a symmetry of nature at the time, it meant for some unusual seeming results. For example, at the time Heaviside was working, the notion that the electromagnetic field stored energy was becoming popular. Heaviside compared the field of a static charge and a moving charge and noticed that for the same charge, the latter stored more energy. This meant that to accelerate a charge required putting extra energy into it which would go into the field. In other words, a charge should feel like it has more mass than it has. The apparent mass contained a familiar 1/√(1-v²/c²) factor and so he noticed that this mass increase grew as the charge's velocty approached that of light. In particular he noticed that the mass would become infinite at the speed of light, exactly as predicted by Special Relativity. Heaviside was never deterred by anything as trivial as an infinity so he went on to study the properties of superluminal particles and predicted and derived the properties of what should be called Heaviside radiation.
(BTW When Heaviside tried to study the geometry of the field around a moving spherical charge he initially made a few mistakes that were eventually fixed by someone else using Heaviside's own methods correctly. One thing that was noted was that the spherical symmetry was flattened. Yet another hint of Lorentz-Fitzgerald contraction.)
I'd love to also say something about Heaviside's battles with Preece and Tait because they are highly entertaining. But instead, I just recommend reading the book for yourself.
Operational Calculus and Distortionless Transmission
There's an example of Heaviside style operational calculus in the link I posted to above. One of the reasons I became interested in this subject again is that I was getting into electronics and I wanted to simplify computations of properties of simple linear circuits. I had this crazy idea that capacitors and inductors could be treated as resistors whose resistance is differential operator valued. Turns out that this wasn't an original move. This is exactly what Heaviside did well over 100 years ago and it was the secret weapon he used for much of his work. He could solve a wide array of ordinary and partial differential equations with ease. Very briefly, his idea was to write the differential operator d/dx as the symbol p and then treat p much like a conventional algebraic variable. He turned differential equations into ordinary algebraic equations.
A great example of this was when he studied the electrical signal that emerges from a long cable as a function of what was sent into the other end. If W is the outgoing signal, and V is the incoming signal, he showed that in his model, W = √(A+Bp)/√(C+Dp) V, for some constants A, B, C and D, that depend on the properties of the cable. At first sight this is meaningless - what is the meaning of the square root of a differential operator? Heaviside had ways to deal with these things, but that's not what he did here. He noticed that if he picked A, B, C and D such that A/B=C/D then he could cancel the p from top and bottom. The net effect was that if this condition held, the signal emerging was the same as the signal entering (apart from a time delay). In physical terms this meant that adding inductance to a long cable would allow it to carry the signal without distorting it. His contemporaries had been declaring long-distance telegraphy impossible because inductance would distort the signal, but here was Heaviside suggesting that inductors be added. The British Post Office ignored Heaviside's claims and it was left to a physicist in the US to put his ideas into practice - ideas that today formed the backbone for the nascent global telecommunications industry. Heaviside couldn't even get much of his work published because mathematicians like Burnside (boo! hiss!) rejected it as unrigorous. Needless to say, Heaviside died a bitter neglected old man...
Foreshadowings of Special Relativity
I'm fascinated by some of the theoretical clues about relativity that were appearing before Einstein. There were obvious results like the Michelson-Morley experiment and the Lorentz-Fitzgerald contraction proposed to explain it. But there were clues in other places too. HG Wells, in The Time Machine, said "There is no difference between Time and any of the three dimensions of Space except that our consciousness moves along it", so we already have a popularisation of the idea of a symmetry between space and time. Heaviside spent much of his time working with Maxwell's equations (which should really be called Heaviside's equations) which inherently has Lorentz group symmetry. This means that any physical predictions made from Maxwell's equations must also have Lorentz invariance. As nobody had explicitly recognised this as a symmetry of nature at the time, it meant for some unusual seeming results. For example, at the time Heaviside was working, the notion that the electromagnetic field stored energy was becoming popular. Heaviside compared the field of a static charge and a moving charge and noticed that for the same charge, the latter stored more energy. This meant that to accelerate a charge required putting extra energy into it which would go into the field. In other words, a charge should feel like it has more mass than it has. The apparent mass contained a familiar 1/√(1-v²/c²) factor and so he noticed that this mass increase grew as the charge's velocty approached that of light. In particular he noticed that the mass would become infinite at the speed of light, exactly as predicted by Special Relativity. Heaviside was never deterred by anything as trivial as an infinity so he went on to study the properties of superluminal particles and predicted and derived the properties of what should be called Heaviside radiation.
(BTW When Heaviside tried to study the geometry of the field around a moving spherical charge he initially made a few mistakes that were eventually fixed by someone else using Heaviside's own methods correctly. One thing that was noted was that the spherical symmetry was flattened. Yet another hint of Lorentz-Fitzgerald contraction.)
I'd love to also say something about Heaviside's battles with Preece and Tait because they are highly entertaining. But instead, I just recommend reading the book for yourself.
Subscribe to:
Posts (Atom)