I've been slow to write the last couple of parts on my untangling series as I've been pretty busy lately. Among other things I've finally got around to submitting a couple of graphics related papers (that I actually wrote ages ago) for publication. Not sure they'll get accepted but there's no harm trying. I'll probably write blog posts about these in the near future now that I have permission from my employer to talk about them.
Note: Neither of these are anything I actually use at work. Well, I've used the adjoint one a tiny bit. The latter is in the spirit of computational geometry papers: it demonstrates an algorithm that runs (asymptotically) in the fastest possible time, but in practice you'll probably want to use an approximation that looks just as good. I was amazed I was able to find a practical application for a result that came out of toric varieties, but it's going to be tough on the reviewers as there seem to be so few people in the graphics world who know about multidimensional DSP techniques.
Two Tricks for the
Price of One: Linear Filters and their Adjoints
Fast and Exact
Convolution with Polygonal Filters
Of course, straight after submitting I noticed a bunch of pieces missing from some expressions. In places designed to help disambiguate things for the reviewers as well. Ho hum.
I also recently presented a very short presentation at the "Stupid Rat Tricks" part of the Renderman User Group: quine.sl: a self-shading shader. (For more on RSL see Wikipedia.) The source is available here. I don't think the company lawyers fully appreciated that this shader now allows their handiwork to be used like a texture map.
My presentation was completely blown away by the guy who implemented a large part of the Renderman interface completely in bourne shell. I can't think of a stupider thing than that! :-)
Back to untangling in the next post.
Update: I added a Mathematica 5 notebook illustrating the transfer functions in the polygonal filter paper.
Tuesday, September 16, 2008


Sunday, August 31, 2008
Untangling with Continued Fractions: Part 3
It's time to return to the vector space monad. But first, after some Haskell preamble, I need to talk about the Einstein summation convention.
We're going to be dealing with multidimensional arrays of values that I'll call tensors. We can refer to the individual elements of these arrays by providing tuples of indices drawn from some set of indices. For example we might refer to the elements of a 10 by 10 array by using pairs of indices, each drawn from the set {0,1,2,...,9}. We'll write some indices as subscripts and some as superscripts. Here are some examples: vi, wj,Tij,Wijkl. vi means the ith value in array v, Tij means the (i,j)-th element of T and so on.
We can form sums over such indices like this
where the sum is over the corresponding index sets for j and k.
The Einstein summation convention is simply this: if an expression has an index repeated once as a subscript and once as a superscript then we implicitly assume a sum over the index without writing the summation symbol. So the above expression becomes simply
The vector space monad allows us to express something similar using do-notation. Let's use the type Bool for our index set, so we're selecting elements of our arrays using the values {False,True} rather than integers. Let ei be the (2-dimensional) vector with the property that its j-component is 1 for j=i and 0 for j≠i. In do-notation this is represented by return i. We use superscripts to indicate the components of a vector so the components of ei are eji. We can write the vector v=3eFalse-5eTruea, with components (3,-5) as
Dual to vectors we have covectors. You can think of these as linear functions that consume vectors and return reals. We can define a basis of covectors fi with the property that fi(ej) is 1 for i=j and 0 otherwise. In our Haskell code it'll be more convenient to think of covectors as mapping vectors to the one-dimensional vector space whose basis element is labelled by (). When we make a vector using an expression like return True, that True is a constructor for the type Bool. We expect to use the dual operation for covectors, and that dual is case analysis. So, for example, we can write w = fFalse+2*fTrue, wih components (1,2), as
Applying w to v gives the expression viwi using the summation convention. Using do-notation it looks like
The point to note is that just like with the summation convention, we don't need to explicitly sum over i. i serves as a kind of iterator object and a vector v automatically supplies i with values in the appropriate range. w then consumes i. So we can translate the summation convention to do-notation by thinking of upper indices corresponding to places that iterators can emerge from, and thinking of lower indices as places where iterators can be consumed.
Another example is matrix representing a transformation of a vector to a vector. It must consume one iterator and emit another one. In the Einstein summation convention such a transformation might be written ri=Mijvj. We could write a simple 2D 2x scale and 90 degree rotation matrix as
We can then write the transformation as
Another simple example is an inner product. We can represent the ordinary dot product as a matrix dij and write the square length of v as v . v = dijvivj. We can implement this as
where we define
Similarly, tuples of superscripts correspond to iterators that are tuples of indices.
With that in place, we're now in a position to consider what monadic notation for knots means in the vector-space-over Bool monad. Essentially what we're doing is representing 'components' of a tangle or knot, the cups, caps and crossings, as tensors. When we glue these components with labels we're forming sums. In fact, each labelled edge connecting two components corresponds to an index and so we can think of it as possibly taking two different values, False or True. So the monadic expression corresponds to a sum over all possible ways to assign values from Bool to the indices with a corresponding weight for each term. This should be familiar to some people, it's just like what takes place in statistical thermodynamics. We consider a bunch of particles and form a sum over all of the possible states that those particles could have, with a corresponding weight for each configuration of states. A good example is the Ising model in which electrons sit at the vertices of a regular lattice. Two neighbouring electrons in a ferromagnet tend to want to align the same way, so confgurations in which neighbouring electrons have the same spin will get assigned a higher weight.
In our tangle problem, the trick is to find a magic set of weights with the property that two different summations representing isotopic knots or tangles give the same result. This turns out to be too hard, but we relax it a bit we will be led to one of the most fruitful new approaches in knot theory in recent years - the Jones Polynomial. Vaughan Jones was investigating certain types of model from statistical mechanics and came to realise that some of the equations that were arising were the same ones needed to get suitable weights for knot theory. From this realisation emerged his eponymous polynomial. But, that's all I'll be saying about this polynomial in this post.
Anyway, to make things clearer here's an example:
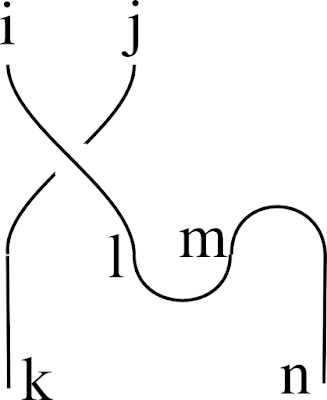
We interpret cap, cup, over and under as the tensors Mij, Nij, Sijkl and Tijkl. In monadic notation we get
With the summation convention in mind this evaluates to:
and without it we see that all we're doing is computing
We can try an elementary choice for our tensors above. We can define M and N to be given by identity matrices:
We can then choose S and T to simply swap their arguments:
With these choices, the weighting is such that a non-zero weight is assigned to a knot or tangle if and only if all of the labels along a single strand are assigned the same value, in other words we're now summing over ways of assigning labels to entire strands. For rational tangles we can only end up with three possible values corresponding to the three ways the two outputs can be connected to the two inputs. (Straight through, the tangle I called ∞; straight through with a swap, the tangle called -1; and connecting together both the inputs, and both the outputs, the tangle called 0.)
Only test2 succeeds so we know example is a tangle that forms its outputs by swapping the inputs.
So even with this simple assignment we're able to extract some basic connectivity information from our monadic representation. With smarter choices we'll get more information, but that's enough for now. We now have the prerequisites and in the next installment we can start doing some proper knot theory.
> {-# LANGUAGE MultiParamTypeClasses,FlexibleInstances,FunctionalDependencies #-}

> module Main where

> import qualified Data.Map as M
> import Control.Monad
> import Test.QuickCheck

> infixl 4 .+
> infixl 4 .-
> infixl 5 .*
We're going to be dealing with multidimensional arrays of values that I'll call tensors. We can refer to the individual elements of these arrays by providing tuples of indices drawn from some set of indices. For example we might refer to the elements of a 10 by 10 array by using pairs of indices, each drawn from the set {0,1,2,...,9}. We'll write some indices as subscripts and some as superscripts. Here are some examples: vi, wj,Tij,Wijkl. vi means the ith value in array v, Tij means the (i,j)-th element of T and so on.
We can form sums over such indices like this
ΣjkTijWjkvk
where the sum is over the corresponding index sets for j and k.
The Einstein summation convention is simply this: if an expression has an index repeated once as a subscript and once as a superscript then we implicitly assume a sum over the index without writing the summation symbol. So the above expression becomes simply
TijWjkvk
The vector space monad allows us to express something similar using do-notation. Let's use the type Bool for our index set, so we're selecting elements of our arrays using the values {False,True} rather than integers. Let ei be the (2-dimensional) vector with the property that its j-component is 1 for j=i and 0 for j≠i. In do-notation this is represented by return i. We use superscripts to indicate the components of a vector so the components of ei are eji. We can write the vector v=3eFalse-5eTruea, with components (3,-5) as
> v :: V Float Bool
> v = 3 .*return False .- 5 .*return True
Dual to vectors we have covectors. You can think of these as linear functions that consume vectors and return reals. We can define a basis of covectors fi with the property that fi(ej) is 1 for i=j and 0 otherwise. In our Haskell code it'll be more convenient to think of covectors as mapping vectors to the one-dimensional vector space whose basis element is labelled by (). When we make a vector using an expression like return True, that True is a constructor for the type Bool. We expect to use the dual operation for covectors, and that dual is case analysis. So, for example, we can write w = fFalse+2*fTrue, wih components (1,2), as
> w :: Bool -> V Float ()
> w i = case i of
>   False -> return ()
>   True -> 2 .* return ()
Applying w to v gives the expression viwi using the summation convention. Using do-notation it looks like
> vw :: V Float ()
> vw = reduce $ do
>   i <- v
>   w i
The point to note is that just like with the summation convention, we don't need to explicitly sum over i. i serves as a kind of iterator object and a vector v automatically supplies i with values in the appropriate range. w then consumes i. So we can translate the summation convention to do-notation by thinking of upper indices corresponding to places that iterators can emerge from, and thinking of lower indices as places where iterators can be consumed.
Another example is matrix representing a transformation of a vector to a vector. It must consume one iterator and emit another one. In the Einstein summation convention such a transformation might be written ri=Mijvj. We could write a simple 2D 2x scale and 90 degree rotation matrix as
> m :: Bool -> V Float Bool
> m j = case j of
>   False -> 2 .*return True
>   True -> -2 .*return False
We can then write the transformation as
> r = do
>   j <- v
>   i <- m j
>   return i
Another simple example is an inner product. We can represent the ordinary dot product as a matrix dij and write the square length of v as v . v = dijvivj. We can implement this as
> v2 = do
>   i <- v
>   j <- v
>   d (i,j)
where we define
> d (i,j) = case (i,j) of
>   (False,False) -> return ()
>   (True,True) -> return ()
>   otherwise -> mzero
Similarly, tuples of superscripts correspond to iterators that are tuples of indices.
With that in place, we're now in a position to consider what monadic notation for knots means in the vector-space-over Bool monad. Essentially what we're doing is representing 'components' of a tangle or knot, the cups, caps and crossings, as tensors. When we glue these components with labels we're forming sums. In fact, each labelled edge connecting two components corresponds to an index and so we can think of it as possibly taking two different values, False or True. So the monadic expression corresponds to a sum over all possible ways to assign values from Bool to the indices with a corresponding weight for each term. This should be familiar to some people, it's just like what takes place in statistical thermodynamics. We consider a bunch of particles and form a sum over all of the possible states that those particles could have, with a corresponding weight for each configuration of states. A good example is the Ising model in which electrons sit at the vertices of a regular lattice. Two neighbouring electrons in a ferromagnet tend to want to align the same way, so confgurations in which neighbouring electrons have the same spin will get assigned a higher weight.
In our tangle problem, the trick is to find a magic set of weights with the property that two different summations representing isotopic knots or tangles give the same result. This turns out to be too hard, but we relax it a bit we will be led to one of the most fruitful new approaches in knot theory in recent years - the Jones Polynomial. Vaughan Jones was investigating certain types of model from statistical mechanics and came to realise that some of the equations that were arising were the same ones needed to get suitable weights for knot theory. From this realisation emerged his eponymous polynomial. But, that's all I'll be saying about this polynomial in this post.
Anyway, to make things clearer here's an example:

We interpret cap, cup, over and under as the tensors Mij, Nij, Sijkl and Tijkl. In monadic notation we get
> example (i,j) = do
>   (k,l) <- over (i,j)
>   (m,n) <- cap
>   cup (l,m)
>   return (k,n)
With the summation convention in mind this evaluates to:
SijklNlmMm,n
and without it we see that all we're doing is computing
Σl,mSijklNlmMm,n
We can try an elementary choice for our tensors above. We can define M and N to be given by identity matrices:
> cap :: V Float (Bool,Bool)
> cap = return (False,False) .+ return (True,True)

> cup :: (Bool,Bool) -> V Float ()
> cup (i,j) = case (i,j) of
>   (False,False) -> return ()
>   (True,True) -> return ()
>   otherwise -> mzero
We can then choose S and T to simply swap their arguments:
> over,under :: (Bool,Bool) -> V Float (Bool,Bool)
> over (i,j) = return (j,i)
> under (i,j) = return (j,i)
With these choices, the weighting is such that a non-zero weight is assigned to a knot or tangle if and only if all of the labels along a single strand are assigned the same value, in other words we're now summing over ways of assigning labels to entire strands. For rational tangles we can only end up with three possible values corresponding to the three ways the two outputs can be connected to the two inputs. (Straight through, the tangle I called ∞; straight through with a swap, the tangle called -1; and connecting together both the inputs, and both the outputs, the tangle called 0.)
> tangleInfinity,tangleMinus1,tangleZero :: (Bool,Bool) -> V Float (Bool,Bool)
> tangleInfinity (i,j) = return (i,j)
> tangleMinus1 (i,j) = return (j,i)
> tangleZero (i,j) = do
>   cup (i,j)
>   cap

> test1 = quickCheck $ \x -> (example x == tangleInfinity x)
> test2 = quickCheck $ \x -> (example x == tangleMinus1 x)
> test3 = quickCheck $ \x -> (example x == tangleZero x)
Only test2 succeeds so we know example is a tangle that forms its outputs by swapping the inputs.
So even with this simple assignment we're able to extract some basic connectivity information from our monadic representation. With smarter choices we'll get more information, but that's enough for now. We now have the prerequisites and in the next installment we can start doing some proper knot theory.
> data V r b = V [(r,b)] deriving (Eq,Show)
> unV (V bs) = bs

> instance Num r => Functor (V r) where
>    fmap f (V bs) = V $ map (\(r,b) -> (r,f b)) bs

> scale x (bs) = map (\(r,b) -> (x*r,b)) bs

> instance Num r => Monad (V r) where
>    return b = V [(1,b)]
>    x >>= f = join (fmap f x)
>        where join x = g $ fmap unV x
>              g (V bs) = V $ concat $ map (uncurry scale) bs

> instance Num r => MonadPlus (V r) where
>    mzero = V []
>    mplus (V x) (V y) = V (x++y)

> class Num r => VectorSpace r v | v -> r where
>    zero :: v
>    (.+) :: v -> v -> v
>    (.*) :: r -> v -> v
>    (.-) :: v -> v -> v
>    v1 .- v2 = v1 .+ ((-1).*v2)

> swap (x,y) = (y,x)
> reduce x = V $ filter ((/=0) . fst) $ fmap swap $ M.toList $ M.fromListWith (+) $ fmap swap $ unV $ x

> instance (Num r,Ord b) => VectorSpace r (V r b) where
>    zero = V []
>    V v1 .+ V v2 = reduce (V (v1 ++ v2))
>    r .* V v = reduce (V $ scale r v)
Saturday, August 23, 2008
Untangling with Continued Fractions: Part 2
Recall that I defined a rational tangle to be what you get by starting with a pair of untangled strings whose ends are at infinity and then sliding the strings around as much as you like keeping the ends at infinity. If you don't like the infinity bit, just think of strings inside a sphere with the ends constrained to lie on (but free to slide around) the surface of the sphere. We also insist that the ends end up at the four diagonal directions.
Two rational tangles are considered to be isotopic if you can slide the strings about to turn one into the other, this time keeping the ends of the strings fixed. (Such a motion is called an isotopy.)
As I've previously mentioned, you only need twists, antitwists and rotations to untangle a rational tangle. Here are the twist operations again:

I'm using a box to represent some unknown tangle. The antitwist really is an inverse for the twist because one followed by the other gives you what you started with once you pull the strings straight:

We can also draw a rotation like this:

Let's call the twist T (so the antitwist is T-1) and the rotation S and write products of operations from right to left in the usual way. As both S and T are invertible, they generate a group. It's pretty clear that S4=1, where 1 is the identity operation. So we don't need a clockwise rotation, we can just use S3.
But here's a surprising fact: S2=1. If we perform a 180 degree rotation on a rational tangle the result might look different at first, but it is isotopic to what we started with. I'll leave you to convince yourself of this, but you can prove it by induction on the number of twists or antitwists you have in your diagram. Try it for simple rational tangles first, maybe real ones made with real string.
Here's an even more surprising fact, (TS)3=1. I can demonstrate this pictorially. Start with he result of applying T:

The result of ST:

The result of TST:
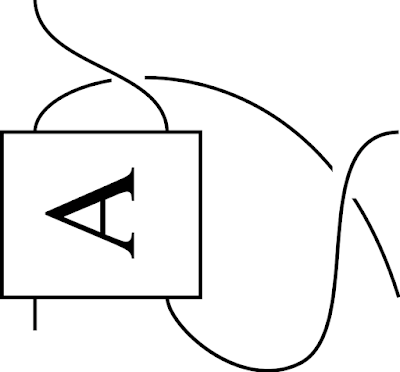
The result of STST:
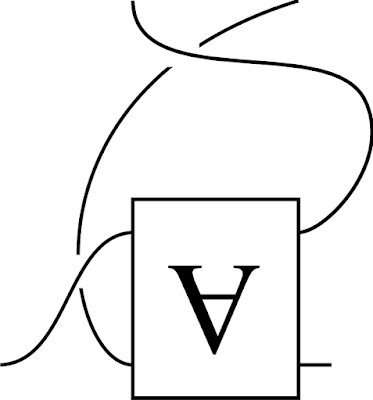
After TSTST:

But by sliding one string behind the tangle, allowed in an isotopy, we find that that is isotopic to this:

It's not hard to see that another S brings us back to where we started. (To do that we need to rotate the block labelled A, but that is allowed in an isotopy as we're not moving the ends of the strings.) This means we can write an antitwist in terms of twists and rotations. But it's convenient to keep using antitwists.
So we have S2=1 and (ST)3=1. It can also be proved that any other relationships between S and T can be derived from these using the operations in a group. But this is a well studied group. We can approach it like this. Define two functions s and t by
It's easy to show that s2=identity=(st)3. In fact, we have an isomorphism between the group of operations we can perform on rational tangles and the functions we can build with s and t. It goes further.
Take the rational numbers and throw in ∞ to give us the extended rationals. Let s and t act in the usual way on most of the rationals but throw in the extra rules s(∞)=0, s(0)=∞ and t(∞)=∞ to handle infinity. We have defined an action of s and t on the extended rationals. We can exactly parallel this with the rational tangles. Call this tangle 0:
We can reach every rational tangle by applying the operations S and T to 0. But if we replace S with s and T with t then the sequence of s's and t's will give us an extended rational number that labels the tangle. Because S and T obey the same equations as s and t, isotopic knots will end up getting the same extended rational. So we can use extended rationals to label the rational tangles. Here are some examples:
Firstly just an antiwist, T-1. That corresponds to t-1(0)=-1.

Two antitwists gives -2:

Composing a 90 degree rotation gives

And applying another antitwist subtracts one again giving:

The name rational tangle is justified.
So, given any any rational tangle we simply need to find the corresponding extended rational and then figure out how to write it as a composition of s's and t's applied to 0. This is more or less the usual technique for finding the continued fraction representation of a rational. And once we know the sequence, we can then apply it in reverse to untangle the tangle.
But there's one catch, how can we go from the monadic representation of a tangle that I described previously to the corresponding extended rational? We'll start on that problem in my next post, but amazingly the vector space monad can be used to do almost all of the work. It's surprising: it's only a short bit of code that works out the untangling operations, but the explication is getting rather long now...
An amazing application of this work is in the study of the untangling of DNA. DNA is a double helix and the two parts of the helix must be separated in order to transcribe it. As you might imagine, the DNA can become incredibly tangled by this process. To deal with this, the topoisomerases snip, manipulate and repair the DNA so as to eliminate these tangles. It was realised that it was possible to work out exactly what operations the topoisomerases were performing by analysing the before and after DNA strings in terms of rational tangles.
The perosn who first figured out this relationship between tangles and rational numbers was the ubiquitous JH Conway.
For the proofs missing above, these references should fill in the details:
Rational Tangles, Kauffman and Goldman
Knots and Physics, Kauffman
And if I've lost you above, the following is a nice easy introduction:
Conway's Rational Tangles, Davis
Modeling protein-DNA complexes with tangles
One last thing. I've noticed some, but not all, papers define the twist oppositely from me.
Two rational tangles are considered to be isotopic if you can slide the strings about to turn one into the other, this time keeping the ends of the strings fixed. (Such a motion is called an isotopy.)
As I've previously mentioned, you only need twists, antitwists and rotations to untangle a rational tangle. Here are the twist operations again:

I'm using a box to represent some unknown tangle. The antitwist really is an inverse for the twist because one followed by the other gives you what you started with once you pull the strings straight:

We can also draw a rotation like this:

Let's call the twist T (so the antitwist is T-1) and the rotation S and write products of operations from right to left in the usual way. As both S and T are invertible, they generate a group. It's pretty clear that S4=1, where 1 is the identity operation. So we don't need a clockwise rotation, we can just use S3.
But here's a surprising fact: S2=1. If we perform a 180 degree rotation on a rational tangle the result might look different at first, but it is isotopic to what we started with. I'll leave you to convince yourself of this, but you can prove it by induction on the number of twists or antitwists you have in your diagram. Try it for simple rational tangles first, maybe real ones made with real string.
Here's an even more surprising fact, (TS)3=1. I can demonstrate this pictorially. Start with he result of applying T:

The result of ST:

The result of TST:

The result of STST:

After TSTST:

But by sliding one string behind the tangle, allowed in an isotopy, we find that that is isotopic to this:

It's not hard to see that another S brings us back to where we started. (To do that we need to rotate the block labelled A, but that is allowed in an isotopy as we're not moving the ends of the strings.) This means we can write an antitwist in terms of twists and rotations. But it's convenient to keep using antitwists.
So we have S2=1 and (ST)3=1. It can also be proved that any other relationships between S and T can be derived from these using the operations in a group. But this is a well studied group. We can approach it like this. Define two functions s and t by
s(x) = -1/x
t(x) = x+1.
It's easy to show that s2=identity=(st)3. In fact, we have an isomorphism between the group of operations we can perform on rational tangles and the functions we can build with s and t. It goes further.
Take the rational numbers and throw in ∞ to give us the extended rationals. Let s and t act in the usual way on most of the rationals but throw in the extra rules s(∞)=0, s(0)=∞ and t(∞)=∞ to handle infinity. We have defined an action of s and t on the extended rationals. We can exactly parallel this with the rational tangles. Call this tangle 0:

We can reach every rational tangle by applying the operations S and T to 0. But if we replace S with s and T with t then the sequence of s's and t's will give us an extended rational number that labels the tangle. Because S and T obey the same equations as s and t, isotopic knots will end up getting the same extended rational. So we can use extended rationals to label the rational tangles. Here are some examples:
Firstly just an antiwist, T-1. That corresponds to t-1(0)=-1.

Two antitwists gives -2:

Composing a 90 degree rotation gives

And applying another antitwist subtracts one again giving:

The name rational tangle is justified.
So, given any any rational tangle we simply need to find the corresponding extended rational and then figure out how to write it as a composition of s's and t's applied to 0. This is more or less the usual technique for finding the continued fraction representation of a rational. And once we know the sequence, we can then apply it in reverse to untangle the tangle.
But there's one catch, how can we go from the monadic representation of a tangle that I described previously to the corresponding extended rational? We'll start on that problem in my next post, but amazingly the vector space monad can be used to do almost all of the work. It's surprising: it's only a short bit of code that works out the untangling operations, but the explication is getting rather long now...
An amazing application of this work is in the study of the untangling of DNA. DNA is a double helix and the two parts of the helix must be separated in order to transcribe it. As you might imagine, the DNA can become incredibly tangled by this process. To deal with this, the topoisomerases snip, manipulate and repair the DNA so as to eliminate these tangles. It was realised that it was possible to work out exactly what operations the topoisomerases were performing by analysing the before and after DNA strings in terms of rational tangles.
The perosn who first figured out this relationship between tangles and rational numbers was the ubiquitous JH Conway.
References
For the proofs missing above, these references should fill in the details:
Rational Tangles, Kauffman and Goldman
Knots and Physics, Kauffman
And if I've lost you above, the following is a nice easy introduction:
Conway's Rational Tangles, Davis
Modeling protein-DNA complexes with tangles
One last thing. I've noticed some, but not all, papers define the twist oppositely from me.
Saturday, August 16, 2008
Untangling with Continued Fractions: Part 1
Continuing from before It's time now do discuss the problem of forming a representation of a knot or tangle in machine readable form.
I've defined rational tangles but I should set that in a wider context. A knot is essentially a single closed loop embedded in 3D space and a link is a non-intersecting union of a bunch of these. Any tangle, knot or link can be projected down to 2D space so that you get a finite collection of 'over' or 'under' crossings connected by arcs. You might have to jiggle things around a bit to ensure that you don't get any degeneracies like two separate parts of a knot being projected to the same segment of curve in 2D, but this is always possible. Here's an example of such a 2D projection, a knot diagram, for the photograph I posted last week:

Roughly speaking, two knots or links or tangles are equivalent if you can slide the strings about to get from one to the other without passing one string through another. In the case of rational tangles we have the extra constraint that the free ends mustn't move and must always remain 'at infinity' so you can't pass loops over the end. Given two diagrams for rational tangles, the task is to tell when they represent something equivalent. I'll start on this in a future posting, but for now I just want to consider the problem of getting diagrams like that above into machine readable from. (Incidentally, the rigorous mathematical definition of knot equivalence, ambient isotopy, relies on the notion of finding a continuous bijection between the space around the two knots, not the knot itself.)
We don't need anything particularly clever to form our representation as there is a fairly commonplace way to represent connectons between components using monads. If we have some kind of block with inputs a and b and outputs c and d we can represent this as a line of do-notation looking like
Examples of such notation are in Matthew Naylor's article on Lava. We could also use arrows but in this case there is no need.
So now we need to break up a diagram of a rational tangle into components and hook them up, working down the diagram from top to bottom. There are four essential components that can be discerned and I'm calling them cups, caps, overs and unders. Here are the corresponding diagrams for each one:

Cups have two inputs but no output and caps have two outputs and no inputs.
Now all we have to do is label the inputs and outputs of each arc, write the corresponding lines as above, and collect them together in a do-block. Here I've redrawn the above diagram marking the cups and caps with red circles and the overs and unders with green circles.

I've also labelled the inputs and outputs. We can now write the following block of code.
Note how this block has a pair of inputs (a,b) and a pair of outputs (m,z) corresponding to the strings at the top and bottom. Clearly knots and links should have no inputs or outputs but rational tangles should have a pair of inputs and a pair of outputs. The precise order shouldn't matter as long as you don't try to use a name that isn't yet in scope.
So what monad should we use? It's easy to imagine some kind of state monad that allows us to generate fresh labels for each of the connections and collects up a graph-like representation of our tangle. But the surprise is this: it turns out we don't need to do anything complicated like this. With suitable definitions of cup, cap, over and under, not only does the vector space monad give us the representation we want, it also does most of our computation for us. But first I need to explain the underlying mathematics in an upcoming installment.
I've defined rational tangles but I should set that in a wider context. A knot is essentially a single closed loop embedded in 3D space and a link is a non-intersecting union of a bunch of these. Any tangle, knot or link can be projected down to 2D space so that you get a finite collection of 'over' or 'under' crossings connected by arcs. You might have to jiggle things around a bit to ensure that you don't get any degeneracies like two separate parts of a knot being projected to the same segment of curve in 2D, but this is always possible. Here's an example of such a 2D projection, a knot diagram, for the photograph I posted last week:

Roughly speaking, two knots or links or tangles are equivalent if you can slide the strings about to get from one to the other without passing one string through another. In the case of rational tangles we have the extra constraint that the free ends mustn't move and must always remain 'at infinity' so you can't pass loops over the end. Given two diagrams for rational tangles, the task is to tell when they represent something equivalent. I'll start on this in a future posting, but for now I just want to consider the problem of getting diagrams like that above into machine readable from. (Incidentally, the rigorous mathematical definition of knot equivalence, ambient isotopy, relies on the notion of finding a continuous bijection between the space around the two knots, not the knot itself.)
We don't need anything particularly clever to form our representation as there is a fairly commonplace way to represent connectons between components using monads. If we have some kind of block with inputs a and b and outputs c and d we can represent this as a line of do-notation looking like
(c,d) <- block (a,b)
Examples of such notation are in Matthew Naylor's article on Lava. We could also use arrows but in this case there is no need.
So now we need to break up a diagram of a rational tangle into components and hook them up, working down the diagram from top to bottom. There are four essential components that can be discerned and I'm calling them cups, caps, overs and unders. Here are the corresponding diagrams for each one:

Cups have two inputs but no output and caps have two outputs and no inputs.
Now all we have to do is label the inputs and outputs of each arc, write the corresponding lines as above, and collect them together in a do-block. Here I've redrawn the above diagram marking the cups and caps with red circles and the overs and unders with green circles.

I've also labelled the inputs and outputs. We can now write the following block of code.
> example (a,b) = do
>   (c,d) <- over (a,b)
>   (e,f) <- cap
>   (g,h) <- over (c,e)
>   (i,j) <- over (f,d)
>   (m,n) <- cap
>   (k,l) <- cap
>   (q,r) <- over (h,k)
>   (s,y) <- over (l,i)
>   (o,p) <- over (n,g)
>   (t,u) <- under (p,q)
>   (v,w) <- under (r,s)
>   (x,z) <- over (y,j)
>   cup (o,t)
>   cup (u,v)
>   cup (w,x)
>   return (m,z)
Note how this block has a pair of inputs (a,b) and a pair of outputs (m,z) corresponding to the strings at the top and bottom. Clearly knots and links should have no inputs or outputs but rational tangles should have a pair of inputs and a pair of outputs. The precise order shouldn't matter as long as you don't try to use a name that isn't yet in scope.
So what monad should we use? It's easy to imagine some kind of state monad that allows us to generate fresh labels for each of the connections and collects up a graph-like representation of our tangle. But the surprise is this: it turns out we don't need to do anything complicated like this. With suitable definitions of cup, cap, over and under, not only does the vector space monad give us the representation we want, it also does most of our computation for us. But first I need to explain the underlying mathematics in an upcoming installment.
Saturday, August 09, 2008
Untangling with Continued Fractions: Part 0
A rational tangle is what you get when you take two initially separate lengths of rope and then allow them to interact while keeping the ends 'at infinity'. You're allowed to do whatever tangling you like with the proviso that you can't pass the ends of the ropes through your tangle. We'll also insist that tangles are arranged so that the four loose ends go off in directions corresponding (at least roughly) to the four diagonals. This is, of course, mathematics, so there'll be some idealisation going on too.
Here is an example of a tangle:

My goal over the next few posts is to sketch how these tangles can be classified mathematically and develop a short Haskell program to tell you how to untangle them. Along the way we'll meet a monad that gives a simple embedded language to describe knots and tangles as well as an amazing connection with continued fractions noticed by John Conway. We'll also briefly touch on some statistical thermodynamics, quantum field theory, quantum computing, genetics as well as a little bit of knot theory. Amazingly these subjects are all tied together in surprising ways.
The important idea is that all such tangles can be untangled by composing a sequence of just three operations: a rotation, a twist and an antitwist. A rotation is simply a 90 degree rotation anticlockwise. A twist brings the lower right string over the upper right string so that the upper and lower right strings end up swapping places. An antitwist is the inverse to the twist so that a twist followed by an untwist cancels out. It's a bit like solving Rubik's cube.

If I enter machine readable notation describing the above photo into my program the output should be:
Here is a movie showing how that solution gets played out. That's one initial frame plus 12 more for each of the moves listed above:
(Note that I used bungee cords which are quite rigid so doing a twist would sometimes flip the innards of the tangle itself, for example on the first antitwist. That's allowed. The restriction is that I can't bring the ends into 'the picture' at any point.)
Anyway, it took a while to put that video together so that's all for now. In the next post I'll discuss how we form a machine readable description of the tangle above using monadic do-notation. (It'd be cool if I had some smart image processing code to do this, but alas, we're going to have to enter it by hand.)
Here is an example of a tangle:

My goal over the next few posts is to sketch how these tangles can be classified mathematically and develop a short Haskell program to tell you how to untangle them. Along the way we'll meet a monad that gives a simple embedded language to describe knots and tangles as well as an amazing connection with continued fractions noticed by John Conway. We'll also briefly touch on some statistical thermodynamics, quantum field theory, quantum computing, genetics as well as a little bit of knot theory. Amazingly these subjects are all tied together in surprising ways.
The important idea is that all such tangles can be untangled by composing a sequence of just three operations: a rotation, a twist and an antitwist. A rotation is simply a 90 degree rotation anticlockwise. A twist brings the lower right string over the upper right string so that the upper and lower right strings end up swapping places. An antitwist is the inverse to the twist so that a twist followed by an untwist cancels out. It's a bit like solving Rubik's cube.

If I enter machine readable notation describing the above photo into my program the output should be:
rotate
antitwist
rotate
twist
rotate
antitwist
rotate
twist
rotate
antitwist
antitwist
antitwist
Here is a movie showing how that solution gets played out. That's one initial frame plus 12 more for each of the moves listed above:
(Note that I used bungee cords which are quite rigid so doing a twist would sometimes flip the innards of the tangle itself, for example on the first antitwist. That's allowed. The restriction is that I can't bring the ends into 'the picture' at any point.)
Anyway, it took a while to put that video together so that's all for now. In the next post I'll discuss how we form a machine readable description of the tangle above using monadic do-notation. (It'd be cool if I had some smart image processing code to do this, but alas, we're going to have to enter it by hand.)
Saturday, August 02, 2008
Hopf Algebra = Group + Monad
I have two goals in this post. Firstly I want to revisit the vector space monad I've used before. This time I want to show how it provides a great domain specific language for working with multilinear functions on vector spaces. Secondly I want to apply this monad to talk about Hopf algebras. In particular I want to address the issue of why Hopf algebras and groups are actually the same thing. In fact, I want to push this idea to the point where I can use exactly the same code to perform operations in both groups and Hopf algebras. By parameterising the definition of groups in the right way, Hopf algebras appear as if by magic simply by tweaking one parameter. What this means is that if you understand groups and vector spaces, and are comfortable with monads in Haskell, then despite their notoriety as something whose definition is a little opaque, you'll have some idea of what a Hopf algebra is well before the end this post.
Of course there's the question of why anyone would want to know about Hopf algebras. They appear in combinatorics, topology and knot theory, and theoretical physics among other subjects. In fact, there's a review paper on their ubiquity. As topics in mathematics go, this is a hot one.
First some administrivia, because this is, as always, a literate Haskell post.
We'll start with a type class for vector spaces v over a base field k:
.+ is vector space addition and .* is scalar multiplication by elements of the base field.
And now I need a concrete instance. I'll be working with vector spaces equipped with a basis. I'll use the obvious representation: a list of pairs of coefficients and basis elements. So 2x-3y is represented as V [(2,x),(3,y)]. Sometimes it will be clearer if I write 2ex-3ey. x and y aren't really the basis elements but labels. The ex and ey are the actual basis elements. But it's often more readable to write x and y.
The problem with this representation is that basis elements might appear in any order, the same basis element might appear multiple times, and some basis elements might appear with redundant zero coefficients. We need a suitable definition of equality. (I'm sidestepping the usual issues with Eq and Monad.)
V is a functor. fmap f just applies f to the basis elements.
Given any type a, V k a is the type of vectors over k generated by elements of a. So V k (V k a) is the type of vectors whose basis elements are themselves labeled by vectors in V k a. We can think of an element of V k (V k a) looking something like 2(2x+3y)-5(3x-y). It's tempting to say this is equal to what we get when we multiply out, but where I wrote '2x+3y' I really meant e2x+3y. Nonetheless, we can define a function that does the multiplying out. I'll call this function join. So we get a function join :: V k (V k a) -> V k a. In fact, we get a monad.
What's really going on here is that the "vector space over basis" functor is a monad in the category Set, but in the category of Haskell types and functions we're stuck with lists.
V k is not just a monad, it's also a MonadPlus.
So what's the use of making our vector space into a monad? If m is a monad, then any function f:a→mb can be lifted to a function f':ma→mb. f maps the basis elements in a to elements of mb. It's a standard fact about vector spaces that a linear function is completely defined by its value on a basis. f' is the corresponding linear function. So we only need to implement linear functions for basis elements and the function can be automatically lifted to a linear function on the whole vector space. An arrow of the form a→mb is a Kleisli arrow and what I've just argued is that the Kleisli category of the V k monad is the category of vector spaces with basis.
This gives us lots of advantages. For example, we can't accidentally implement a function that isn't linear this way. If we implement the action on a basis, the lift can't help but be linear. Also, working with basis elements rather than the vector space gives us greater flexibility. For example, it'll be easy to form tensor products of vector spaces by directly working with their bases.
Here's the instantiation of the vector space type:
I could have implemented .* using scale but this definition is more in the spirit of what's to come.
Now we switch to groups. Here's a first attempt at writing a group type class
Now we can try testing some of the group laws. For example
If we run ex1 we gain some confidence that we have a group. If we want to be more categorial then we need to express as much as possible as compositions of functions. So let's break down test_inverse1 as a composition of elementary operations.
There's a nice symmetry in test_inverse2. If we make diag part of the definition of a group that we can make this highly symmetric definition of a group:
I've even made a (useless looking) symmetric partner for unit1 and I've renamed the inverse operation as anti, short for antipode. Let's make Z an instance of this class.
I hope I haven't done anything too tricky yet. This is just the familiar definition of a group except I've made a trivial 'counit' and the diagonal function part of the definition. Now comes the most important step in this post: I'll tweak this definition so that all of the associated functions are now Kleisli arrows:
We can now straightforwardly reimplement Z as an instance of this class.
Apart from writing it monad-agnostically, it's just like before. We can exactly recover what we had before with the help of the identitiy monad.
Now we can rewrite the group laws. Before checking to see if aa-1=1 we'll make sure aa-1=a-1a.
For aa-1 we need to compare with the identity. We make an identity by applying unit to (). We could just provide a () but we get something more symmetrical if we construct it using the counit.
We can test associativity easily
In the interest of symmetry, there ought to be a coassociativity law for comultiplication. Here it is:
One issue is that we've introduced comult without making much demand on it. Here's a law that is obviously true in any group that helps to pin down comult. It's simply evaluating (p,q) →(pq,pq) in two different ways.
Out of laziness I'm not going to test every group law, but shortly I'll show you where to find all of the laws, including the new laws for comult.
Identity Z is just the usual group of integers with addition. But the time has come to switch monads. What's H=V Float Z? It's clearly a vector space with basis elements labelled with integers. It's also an instance of Group (V Float) meaning it comes equipped with implementations of functions like unit and comult. But note this: counit is no longer trivial. We have counit :: Z -> V Float (). In other words counit lifts to a linear map from H to V Float (), which is isomorphic to Float. In fact, it sums the coefficients if the basis elements. unit now embeds the ground field in our new structure. But what's mult? Well V Float (Z,Z) is H⊗H. So mult lifts to a bilinear map from H×H to H. We have a vector space with a bilinear multiplication law. Is this law associative? We could write code to check. But here's the really cool bit: we can just reuse test_assocn from above.
By switching monad, we automatically get a new algebraic structure and new 'semantics' for the group laws. Unpacking ex8 reveals that it gives the associativity law for an algebra. Unpacking further group laws in this context gives bialgebra laws.
And 'monadifying' the laws about group inverses give rise to the Hopf algebra laws for the antipode:
In other words, a Hopf algebra over k is nothing other than a group in the generalised sense above using the monad V k. The underlying object and all of the Hopf algebra laws just follow automatically as soon as you switch monads. Groups and Hopf algebras are the same thing.
But we still have this example Hopf algebra V Float Z to think about. It's none other than the group algebra of Z. It's essentially the algebra of Laurent polynomials. Clearly we could repeat this group algebra construction for any group and Z was just an example.
Now I have this machinery for working with Hopf algebras I might as well construct some examples that aren't simply generated by some underlying group. I found some pretty combinatorial examples in this paper.
Firstly I'd like to define some combinatorial operations on lists: cat, chop, shuffle and excise.
cat simply joins a pair of lists.
chop computes a kind of inverse of cat. This inverse is multivalued so depending on which monad is used it can return all of the possible pairs that could have been catted to make a particular list.
shuffle finds all the ways that two lists can be riffle shuffled together.
excise is the multivalued inverse of shuffle in that it finds all of the ways pairs of lists could have been riffle shuffled together to give a particular list.
We can now define a pair of Hopf algebras as follows.
We can now test some of the Hopf algebra laws
Unfortunately my code is a inefficient, and the shuffles cause combinatorial explosions, so it's probably best not to run these examples. This post is about expressing algebraic structures rather than making practical computations in them.
And of course you can try the same with Hopf2.
There's one last important thing to come out of these. We have a powerful notation for working with tensor products of vector spaces but the notation is so easy to use that it's hidden the fact that there's complex stuff going on under the hood. When we're dealing with the Identity monad then a line like (p,q) <- comult u is pretty straightforward to interpret as an assignment. But in the vector space monad it means something very different. Nonetheless, we can often reason (with care) as if it were just an assignment. This is what Sweedler Notation is about. But it kind of just appears automatically here.
What they say is right. Hopf algebras really are groups in disguise. Just take all of the functions that make up the structure of a group and convert each one to a Kleisli arrow for the vector space monad. You end up with Hopf algebras.
I'm amazed at the way I could express this level of abstraction in Haskell. I don't know of any computer algebra package that comes near to this level of expressivity. Although algebra packages often come with amazing implementations of algebraic algorithms, the programming languages they come with are generally completely uninteresting in themselves. I'm looking forward to the day when computational algebraists and programming language theorists get talking to each other.
By the way, this kind of manipulation was what monads were invented for. It's nice to see the two different applications work so well together.
Of course there's the question of why anyone would want to know about Hopf algebras. They appear in combinatorics, topology and knot theory, and theoretical physics among other subjects. In fact, there's a review paper on their ubiquity. As topics in mathematics go, this is a hot one.
First some administrivia, because this is, as always, a literate Haskell post.
> {-# LANGUAGE MultiParamTypeClasses,FlexibleInstances,FunctionalDependencies,GeneralizedNewtypeDeriving #-}

> module Main where

> import qualified Data.Map as M
> import Control.Monad
> import Test.QuickCheck

> infixl 5 .+
> infixl 6 .*

> swap (x,y) = (y,x)
Vector Spaces
We'll start with a type class for vector spaces v over a base field k:
> class Num k => VectorSpace k v | v -> k where
>     zero :: v
>     (.+) :: v -> v -> v
>     (.*) :: k -> v -> v
>     (.-) :: v -> v -> v
>     v1 .- v2 = v1 .+ ((-1).*v2)
.+ is vector space addition and .* is scalar multiplication by elements of the base field.
And now I need a concrete instance. I'll be working with vector spaces equipped with a basis. I'll use the obvious representation: a list of pairs of coefficients and basis elements. So 2x-3y is represented as V [(2,x),(3,y)]. Sometimes it will be clearer if I write 2ex-3ey. x and y aren't really the basis elements but labels. The ex and ey are the actual basis elements. But it's often more readable to write x and y.
> data V k a = V { unV :: [(k,a)] } deriving (Show)
The problem with this representation is that basis elements might appear in any order, the same basis element might appear multiple times, and some basis elements might appear with redundant zero coefficients. We need a suitable definition of equality. (I'm sidestepping the usual issues with Eq and Monad.)
> reduce x = filter ((/=0) . fst) $ fmap swap $ M.toList $ M.fromListWith (+) $ fmap swap $ x

> instance (Ord a,Num k) => Eq (V k a) where
>   V x==V y = reduce x==reduce y

> instance (Ord a,Num k,Ord k) => Ord (V k a) where
>   compare (V x) (V y) = compare (reduce x) (reduce y)
V is a functor. fmap f just applies f to the basis elements.
> instance Num k => Functor (V k) where
>     fmap f (V as) = V $ map (\(k,a) -> (k,f a)) as
Given any type a, V k a is the type of vectors over k generated by elements of a. So V k (V k a) is the type of vectors whose basis elements are themselves labeled by vectors in V k a. We can think of an element of V k (V k a) looking something like 2(2x+3y)-5(3x-y). It's tempting to say this is equal to what we get when we multiply out, but where I wrote '2x+3y' I really meant e2x+3y. Nonetheless, we can define a function that does the multiplying out. I'll call this function join. So we get a function join :: V k (V k a) -> V k a. In fact, we get a monad.
> instance Num k => Monad (V k) where
>     return a = V [(1,a)]
>     x >>= f = join (fmap f x)
>         where join x = V $ concat $ fmap (uncurry scale) $ unV $ fmap unV x
>               scale k1 as = map (\(k2,a) -> (k1*k2,a)) as
What's really going on here is that the "vector space over basis" functor is a monad in the category Set, but in the category of Haskell types and functions we're stuck with lists.
V k is not just a monad, it's also a MonadPlus.
> instance Num r => MonadPlus (V r) where
>     mzero = V []
>     mplus (V x) (V y) = V (x++y)
So what's the use of making our vector space into a monad? If m is a monad, then any function f:a→mb can be lifted to a function f':ma→mb. f maps the basis elements in a to elements of mb. It's a standard fact about vector spaces that a linear function is completely defined by its value on a basis. f' is the corresponding linear function. So we only need to implement linear functions for basis elements and the function can be automatically lifted to a linear function on the whole vector space. An arrow of the form a→mb is a Kleisli arrow and what I've just argued is that the Kleisli category of the V k monad is the category of vector spaces with basis.
This gives us lots of advantages. For example, we can't accidentally implement a function that isn't linear this way. If we implement the action on a basis, the lift can't help but be linear. Also, working with basis elements rather than the vector space gives us greater flexibility. For example, it'll be easy to form tensor products of vector spaces by directly working with their bases.
Here's the instantiation of the vector space type:
> instance (Num k,Ord a) => VectorSpace k (V k a) where
>     zero = V []
>     V x .+ V y = V (x ++ y)
>     (.*) k = (>>= (\a -> V [(k,a)]))

> e = return :: Num k => a -> V k a
> coefficient b (V bs) = maybe 0 id (lookup b (map swap (reduce bs)))
I could have implemented .* using scale but this definition is more in the spirit of what's to come.
Groups
Now we switch to groups. Here's a first attempt at writing a group type class
> class Group1 a where
>    unit1 :: a
>    mult1 :: a -> a -> a
>    inverse1 :: a -> a

> newtype Z = Z Int deriving (Eq,Ord,Show,Arbitrary,Num)

> instance Group1 Z where
>    unit1 = Z 0
>    mult1 = (+)
>    inverse1 = negate
Now we can try testing some of the group laws. For example
> test_inverse1 a = mult1 a (inverse1 a)
> ex1 = quickCheck (\a -> test_inverse1 a==(unit1::Z))
If we run ex1 we gain some confidence that we have a group. If we want to be more categorial then we need to express as much as possible as compositions of functions. So let's break down test_inverse1 as a composition of elementary operations.
> diag a = (a,a)
> both f g (a,b) = (f a,g b)
> test_inverse2 = uncurry mult1 . (id `both` inverse1) . diag
> ex2 = quickCheck (\a -> test_inverse2 a==(unit1::Z))
There's a nice symmetry in test_inverse2. If we make diag part of the definition of a group that we can make this highly symmetric definition of a group:
> class Group2 a where
>     unit2 :: () -> a
>     counit2 :: a -> ()
>     mult2 :: (a,a) -> a
>     comult2 :: a -> (a,a)
>     anti2 :: a -> a
I've even made a (useless looking) symmetric partner for unit1 and I've renamed the inverse operation as anti, short for antipode. Let's make Z an instance of this class.
> instance Group2 Z where
>   unit2 () = Z 0
>   counit2 _ = ()
>   mult2 = uncurry (+)
>   comult2 a = diag a
>   anti2 = negate
I hope I haven't done anything too tricky yet. This is just the familiar definition of a group except I've made a trivial 'counit' and the diagonal function part of the definition. Now comes the most important step in this post: I'll tweak this definition so that all of the associated functions are now Kleisli arrows:
> class Group m a where
>     unit :: () -> m a
>     counit :: a -> m ()
>     mult :: (a,a) -> m a
>     comult :: a -> m (a,a)
>     anti :: a -> m a
We can now straightforwardly reimplement Z as an instance of this class.
> instance Monad m => Group m Z where
>     unit _ = return (Z 0)
>     counit _ = return ()
>     mult = return . uncurry (+)
>     comult = return . diag
>     anti = return . negate
Apart from writing it monad-agnostically, it's just like before. We can exactly recover what we had before with the help of the identitiy monad.
> newtype Identity a = I a deriving (Eq,Ord,Show)

> instance Monad Identity where
>     return x = I x
>     I x >>= f = f x
Now we can rewrite the group laws. Before checking to see if aa-1=1 we'll make sure aa-1=a-1a.
> test_antipode1 a = do
>     (u,t) <- comult a
>     u' <- anti u
>     mult (u',t)

> test_antipode2 a = do
>     (u,t) <- comult a
>     t' <- anti t
>     mult (u,t')

> ex3 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_antipode1 :: Z -> Identity Z
>   rhs = test_antipode2 :: Z -> Identity Z
For aa-1 we need to compare with the identity. We make an identity by applying unit to (). We could just provide a () but we get something more symmetrical if we construct it using the counit.
> test_antipode3 a = do
>   x <- counit a
>   unit x

> ex4 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_antipode1 :: Z -> Identity Z
>   rhs = test_antipode3 :: Z -> Identity Z
We can test associativity easily
> test_assoc1 (a,b,c) = do
>     ab <- mult (a,b)
>     mult (ab,c)

> test_assoc2 (a,b,c) = do
>     bc <- mult (b,c)
>     mult (a,bc)

> ex5 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_assoc1 :: (Z,Z,Z) -> Identity Z
>   rhs = test_assoc2 :: (Z,Z,Z) -> Identity Z
In the interest of symmetry, there ought to be a coassociativity law for comultiplication. Here it is:
> test_coassoc1 x = do
>     (u,v) <- comult x
>     (s,t) <- comult v
>     return (u,s,t)

> test_coassoc2 x = do
>     (u,v) <- comult x
>     (s,t) <- comult u
>     return (s,t,v)

> ex6 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_coassoc1 :: Z -> Identity (Z,Z,Z)
>   rhs = test_coassoc2 :: Z -> Identity (Z,Z,Z)
One issue is that we've introduced comult without making much demand on it. Here's a law that is obviously true in any group that helps to pin down comult. It's simply evaluating (p,q) →(pq,pq) in two different ways.
> test_multcomult1 (u,v) = do
>     (p,q) <- comult u
>     (r,s) <- comult v
>     u' <- mult (p,r)
>     v' <- mult (q,s)
>     return (u',v')

> test_multcomult2 (u,v) = do
>     w <- mult (u,v)
>     comult w

> ex7 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_multcomult1 :: (Z,Z) -> Identity (Z,Z)
>   rhs = test_multcomult2 :: (Z,Z) -> Identity (Z,Z)
Out of laziness I'm not going to test every group law, but shortly I'll show you where to find all of the laws, including the new laws for comult.
Hopf Algebras
Identity Z is just the usual group of integers with addition. But the time has come to switch monads. What's H=V Float Z? It's clearly a vector space with basis elements labelled with integers. It's also an instance of Group (V Float) meaning it comes equipped with implementations of functions like unit and comult. But note this: counit is no longer trivial. We have counit :: Z -> V Float (). In other words counit lifts to a linear map from H to V Float (), which is isomorphic to Float. In fact, it sums the coefficients if the basis elements. unit now embeds the ground field in our new structure. But what's mult? Well V Float (Z,Z) is H⊗H. So mult lifts to a bilinear map from H×H to H. We have a vector space with a bilinear multiplication law. Is this law associative? We could write code to check. But here's the really cool bit: we can just reuse test_assocn from above.
> ex8 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_assoc1 :: (Z,Z,Z) -> V Float Z
>   rhs = test_assoc2 :: (Z,Z,Z) -> V Float Z
By switching monad, we automatically get a new algebraic structure and new 'semantics' for the group laws. Unpacking ex8 reveals that it gives the associativity law for an algebra. Unpacking further group laws in this context gives bialgebra laws.
> ex9 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_multcomult1 :: (Z,Z) -> V Float (Z,Z)
>   rhs = test_multcomult2 :: (Z,Z) -> V Float (Z,Z)
And 'monadifying' the laws about group inverses give rise to the Hopf algebra laws for the antipode:
> ex10 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_antipode1 :: Z -> V Float Z
>   rhs = test_antipode2 :: Z -> V Float Z
In other words, a Hopf algebra over k is nothing other than a group in the generalised sense above using the monad V k. The underlying object and all of the Hopf algebra laws just follow automatically as soon as you switch monads. Groups and Hopf algebras are the same thing.
But we still have this example Hopf algebra V Float Z to think about. It's none other than the group algebra of Z. It's essentially the algebra of Laurent polynomials. Clearly we could repeat this group algebra construction for any group and Z was just an example.
Examples
Now I have this machinery for working with Hopf algebras I might as well construct some examples that aren't simply generated by some underlying group. I found some pretty combinatorial examples in this paper.
Firstly I'd like to define some combinatorial operations on lists: cat, chop, shuffle and excise.
cat simply joins a pair of lists.
> cat x = return $ uncurry (++) x
chop computes a kind of inverse of cat. This inverse is multivalued so depending on which monad is used it can return all of the possible pairs that could have been catted to make a particular list.
> chop :: (MonadPlus m, Functor m) => [a] -> m ([a], [a])
> chop [] = return ([],[])
> chop (a:as) = return ([],a:as) `mplus` fmap ((a:) `both` id) (chop as)
shuffle finds all the ways that two lists can be riffle shuffled together.
> shuffle ([],b) = return b
> shuffle (a,[]) = return a
> shuffle (a:as,b:bs) =
>     fmap (a:) (shuffle (as,b:bs)) `mplus`
>     fmap (b:) (shuffle (a:as,bs))
excise is the multivalued inverse of shuffle in that it finds all of the ways pairs of lists could have been riffle shuffled together to give a particular list.
> excise [] = return (mzero,mzero)
> excise (a:as) = do
>     (x,y) <- excise as
>     return (a:x,y) `mplus` return (x,a:y)
We can now define a pair of Hopf algebras as follows.
> newtype Hopf1 = H1 [Int] deriving (Ord,Eq,Show,Arbitrary)

> instance Group (V Float) Hopf1 where
>     unit _ = return (H1 [])
>     counit (H1 []) = return ()
>     counit _ = zero
>     mult (H1 x,H1 y) = fmap H1 $ cat (x,y)
>     comult (H1 x) = fmap (\(x,y) -> (H1 x,H1 y)) $ excise x
>     anti (H1 x) = (-1)^(length x) .* return (H1 $ reverse x)

> newtype Hopf2 = H2 [Int] deriving (Ord,Eq,Show,Arbitrary)

> instance Group (V Float) Hopf2 where
>     unit _ = return (H2 [])
>     counit (H2 []) = return ()
>     counit _ = zero
>     mult (H2 x,H2 y) = fmap H2 $ shuffle (x,y)
>     comult (H2 x) = fmap (\(x,y) -> (H2 x,H2 y)) $ chop x
>     anti (H2 x) = (-1)^(length x) .* return (H2 $ reverse x)
We can now test some of the Hopf algebra laws
> ex11 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_assoc1 :: (Hopf1,Hopf1,Hopf1) -> V Float Hopf1
>   rhs = test_assoc2 :: (Hopf1,Hopf1,Hopf1) -> V Float Hopf1
Unfortunately my code is a inefficient, and the shuffles cause combinatorial explosions, so it's probably best not to run these examples. This post is about expressing algebraic structures rather than making practical computations in them.
> ex12 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_coassoc1 :: Hopf1 -> V Float (Hopf1,Hopf1,Hopf1)
>   rhs = test_coassoc2 :: Hopf1 -> V Float (Hopf1,Hopf1,Hopf1)

> ex13 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_antipode1 :: Hopf1 -> V Float Hopf1
>   rhs = test_antipode2 :: Hopf1 -> V Float Hopf1

> ex14 = quickCheck (\a -> lhs a==rhs a) where
>   lhs = test_multcomult1 :: (Hopf1,Hopf1) -> V Float (Hopf1,Hopf1)
>   rhs = test_multcomult2 :: (Hopf1,Hopf1) -> V Float (Hopf1,Hopf1)
And of course you can try the same with Hopf2.
Sweedler Notation
There's one last important thing to come out of these. We have a powerful notation for working with tensor products of vector spaces but the notation is so easy to use that it's hidden the fact that there's complex stuff going on under the hood. When we're dealing with the Identity monad then a line like (p,q) <- comult u is pretty straightforward to interpret as an assignment. But in the vector space monad it means something very different. Nonetheless, we can often reason (with care) as if it were just an assignment. This is what Sweedler Notation is about. But it kind of just appears automatically here.
Summary
What they say is right. Hopf algebras really are groups in disguise. Just take all of the functions that make up the structure of a group and convert each one to a Kleisli arrow for the vector space monad. You end up with Hopf algebras.
I'm amazed at the way I could express this level of abstraction in Haskell. I don't know of any computer algebra package that comes near to this level of expressivity. Although algebra packages often come with amazing implementations of algebraic algorithms, the programming languages they come with are generally completely uninteresting in themselves. I'm looking forward to the day when computational algebraists and programming language theorists get talking to each other.
By the way, this kind of manipulation was what monads were invented for. It's nice to see the two different applications work so well together.
Saturday, July 26, 2008
The Fibonacci Numbers, Coalgebraicaly
> {-# LANGUAGE TypeSynonymInstances #-}
What kind of Haskell programmer can I call myself if I haven't written a fiendishly complex piece of code to inefficiently compute the Fibonacci numbers. Unfortunately, what follows isn't particularly fiendish and isn't wholly inefficient, but it'll have to do.
My real motivation is this: I've mentioned before that one difference between mathematics and computer science is that mathematics has more of a bias towards algebraic rather than coalgebraic structures. But coalgebras do appear in mathematics. For example, every Hopf Algebra is a coalgebra (and an algebra) and Hopf algebras play a prominent role due to the amazing discovery that they have a nice connection with combinatorics, especially helping to organise the combinatorics that come up in renormalisation.
The first thing to note is that the computer science and mathematics definitions of coalgebra are closely related but different. An algebra is essentially a vector space over some field K with a bilinear associative product and multiplicative identity. If our algebra is V, then we have a multiplication map V×V -> V that is linear in each of its arguments. That's the same as saying that multiplication is a linear map V⊗V->V. In a coalgebra we have the converse, a linear comultiplication map Δ:V→V⊗V. Similarly, a unit in an algebra gives a way to map your ground field into the algebra, you map x to x.1 so a counit gives a map from V down to K. The full definition is on wikipedia.
The Fibonacci sequence can be thought of as a function N→R, where
f(0)=1
f(1)=1
f(n)=f(n-1)+f(n-2) for n>=2
> f 0 = 1
> f 1 = 1
> f i = f (i-1)+f (i-2)
Many functions satisfy sum formulae like ex+y=exey and tan(x+y)=(tan(x)+tan(y))/(1-tan x tan y). f also has one. What's more, the formula is essentially the definition of a coproduct on a coalgebra.
Define a Fibonacci-like sequence to be a sequence s satisfying just the last part of the definition of f:
s(n)=s(n-1)+s(n-2) for n>=2
Because I have chosen maps to R, Fibonacci-like sequences form a vector space over R.
Let S be the space of Fibonacci-like sequences. We're going to try to make this into a coalgebra. It's easy to come up with a candidate for a counit: ε(f) = f(0).
We can express this in Haskell:
> class VectorSpace v where
>    zero :: v
>    (.*) :: Float -> v -> v
>    (.+) :: v -> v -> v
>    (.-) :: v -> v -> v
>    v .- w = v .+ ((-1) .* w)

> type Sequence = Int -> Float

> instance VectorSpace Sequence where
>    zero _ = 0
>    a .* v = \i -> a*v i
>    v .+ w = \i -> v i+w i

> epsilon f = f 0
We now need to consider S⊗S. Tensor products of infinite dimensional spaces can be a bit delicate. But S is a two-dimensional space because it is completely specified by its first two terms. This means that S⊗S is the obvious thing: a 2D grid of values where each row and each column is an element of S.
> type Sequence2 = Int -> Int -> Float

> instance VectorSpace Sequence2 where
>    zero _ _ = 0
>    a .* v = \i j -> a*v i j
>    v .+ w = \i j -> v i j+w i j
The tensor product operation is straightforward:
> (<*>) :: Sequence -> Sequence -> Sequence2
> v <*> w = \i j -> v i*w j
Let's define the operator D so that (Df)(i)=f(i+1). So D is a kind of shift operator. Dn shifts n times and we can form polynomials in D. Note that this space of polynomials, P, in D is also two-dimensional because D2=1+D by definition of Fibonacci-like.
> d :: Sequence -> Sequence
> d v i = v (i+1)
We can define a pairing between P and S by <f(D),s> = ε(f(D)s). This makes P dual to S. P has an obvious multiplication inherited from ordinary multiplication which we can denote by the map m:P×P→P. This suggests the idea of forming a kind of dual to multiplication, Δ:S→S⊗S, defined by
<f(D)g(D),s>=<f(D)⊗g(D),Δ(s)>
The fact that we have defined things through this duality ensures that (S,ε,Δ) is a coalgebra. (Note that the pairing extends to the tensor products via <f(D)⊗g(D),s⊗t>=<f(D),s><g(D),t>
By definition <Dm⊗Dn,Δ(s)>=<Dm+n,s>. So Δ(s) is simply the 2D grid made by arranging s along the edges and filling in with constant values along the diagonals.
> delta :: Sequence -> Sequence2
> delta v = \i j -> v (i+j)
Give Δ(s) we can extract s back out from it in many different ways. To get the ith element we need to pick j and k such that j+k=i and grab the ith element of the kth row. One choice is to pick k such that it is half of i rounded down:
> extract :: Sequence2 -> Sequence
> extract f i = let k = i `div` 2 in f k (i-k)
Now given a Fibonacci-like sequence s, we can think of the top left 2×2 block of Δ(s) as a matrix. Ie. s(i+j) for i=0,1;j=0,1 forms a matrix. It's clearly invertible by inspection. But there's a deeper reason why it's invertible. If there were a linear dependence between the rows of this matrix it would be a relationship between the shifts of the sequence and hence would give rise to a simpler definition of the Fibonacci sequence. For more general recursive sequences, if there is an nth order recurrence relation for the sequence, and no simpler relation, then the top left (n-1)⊗(n-1) block is full rank and invertible.
Write tij for the inverse of this matrix. Then
Σjf(i+j)tjk=δik for i,j,k=0,1.
Now here's a neat bit: any Fibonacci-like sequence is defined by its first n-1 elements. Any Fibonacci-like sequence is simply a linear combination of f and Df. So the above is actually true for any Fibonacci-like sequence. And as any shift of the Fibonacci sequence is itself a Fibonacci-like sequence, the above is true for any i,k>0.
Another matrix multiplication gives
Σj,kf(i+j)tjkf(k+l)=f(i+l) for j,k=0,1;i,l≥0
That's our Fibonacci summation formula. It tells us how to get f(i+l) in terms of f(i+j) and f(k+l) for j,k=0,1.
Using the definitions above we get
Σj,k<Di⊗Dl,tjkDjf⊗Dkf=e<Di+l,f>
So tjkDjf⊗Dkf satisfies the definition of Δ above, and so must in fact be the same thing. So we have:
Δ(f)=2s⊗f-f⊗Df-Df⊗f+Df⊗Df
(Where I actually computed the elements of the inverse matrix t.)
We can now use this as the basis for a recursive algorithm. We need the bootstrap function to get the recursion started:
> bootstrap :: [Float] -> Sequence -> Sequence
> bootstrap xs v i = if i<length xs then xs!!i else v i

> f' :: Sequence
> f' = bootstrap [1,1,2,3] $ extract $ 2 .* (f' <*> f') .- (f' <*> (d f')) .- ((d f') <*> f') .+ ((d f') <*> (d f'))
It's faster than the usual recursion. (Though that's not saying much.)
I'll leave it to you to extract out what's really going on above, and to generalise it to give sum formulae for other recurrence relations.
Note that the goal here isn't to write a fast algorithm. My main motivation is to view the sum formula as an identity about comultiplication and get some intuition about comultipliation so I can read some Hopf algebra papers.
> let's_go_slow = map f [0..]
> let's_go_faster = map f' [0..]
All of this, apart from the algorithm itself, is an unpacking and simplification of section 1 of Bialgebras of Recursive Sequences and Combinatorial Identities by Futia et al.
PS Tell me if you have trouble reading the above. I wrote a new pseudo-LaTeX to blogger-HTML converter and it might not actually be any good.
Saturday, July 12, 2008
MSFP 2008
I was invited by Conor McBride to give a talk MSFP 2008 in Reykjavik. I've put the slides online here. While rehearsing I wrote a 'script' that I've put here. That's not actually what I said but I felt I needed to write something out beforehand just so I could make sure I had an appropriate amount of material. Apologies for the silly chatty style in a written document but that's the sort of thing that came to mind while sitting in a hotel room. I got to meet in person a bunch of people whose papers I'd read including Thorsten Altenkirch, Tarmo Uustalu and Jeremy Gibbons.
I had an opportunity to explore around Reykjavik so I also put some photos online, including a terrible one of Conor and Tarmo Uustalu (sorry!). By curious coincidence I bumped into, and got to hang out with, an old work colleague as well as a friend of the person who sits one office down from me at work, and Eben Moglen. Small world.
I had an opportunity to explore around Reykjavik so I also put some photos online, including a terrible one of Conor and Tarmo Uustalu (sorry!). By curious coincidence I bumped into, and got to hang out with, an old work colleague as well as a friend of the person who sits one office down from me at work, and Eben Moglen. Small world.
Saturday, June 28, 2008
A blessed man's formula for holey containers
I love the way derivatives of types tell you about holes in containers. It works the other way too and holes can give insight into derivatives.
Suppose S and T are containers so that S(X) and T(X) are containers of elements of type X. Then S(T(X)) is an S-container of T-containers of X's. If we draw S as a square (rectangle actually) and T as a triangle then we can draw a picture of an example of such a thing:

Taking the nth derivative of a type gives the type with (an ordered sequence of) n holes. Here's that previous container with 3 holes made in it:

As the holes have an ordering I've numbered them from 1 to 3.
An S-container of T-containers with holes is essentially an S-container containing both ordinary T-containers, and some T-containers with holes. If we excise the T-containers with holes, we're left with an S-container containing just T-containers, and some holes. Here's a picture of that:

But there are a couple of problems with that. Once we've excised the holey sub T-containers we don't know which S-holes to plug them back into and we don't know how to reconstruct the original numbering of the holes. We need to keep a tiny bit more information. That's the set I wrote down: {{1,3},{2}}. Call each element of this set a block. I've written the elements of the blocks in ascending order and I've written the blocks in ascending order of their lowest elements. The first block corresponds to hole 1 in the S-container and the second block corresponds to hole 2. Similarly, we write the elements of the blocks into the holes in the T-containers. And that allows us to reconstruct the original ST-container.
Think about the general case. We make n holes in an ST-container. So up to n of the T-containers acquire holes. Let's say it's m holes. We can think of the S-container having m holes and these holes being filled by T-containers with b1, b2,...,bm holes where the sum of the bi is n. We're essentially just partitioning the original n holes {1,2,...,n} into m sets. So each ST-container with n holes gives a partition of {1,...,n}, an S-container with n holes, and m T-containers where the ith has bi holes. Writing containers with n holes as nth derivatives we get
Note that the equality above isn't just a numerical equality, it's an isomorphism of types. In fact, it's the type version of the 'combinatorial form' of the Faà di Bruno formula. Although that wikipedia page describes the formula as 'forbidding', if I've done my job right then I think the above picture make it seem almost trivial. I find it much easier to think of this version of the chain rule in terms of holes.
And the explanation for the title of this post: in 1988 Pope John Paul II beatified Faà di Bruno.
Suppose S and T are containers so that S(X) and T(X) are containers of elements of type X. Then S(T(X)) is an S-container of T-containers of X's. If we draw S as a square (rectangle actually) and T as a triangle then we can draw a picture of an example of such a thing:

Taking the nth derivative of a type gives the type with (an ordered sequence of) n holes. Here's that previous container with 3 holes made in it:

As the holes have an ordering I've numbered them from 1 to 3.
An S-container of T-containers with holes is essentially an S-container containing both ordinary T-containers, and some T-containers with holes. If we excise the T-containers with holes, we're left with an S-container containing just T-containers, and some holes. Here's a picture of that:

But there are a couple of problems with that. Once we've excised the holey sub T-containers we don't know which S-holes to plug them back into and we don't know how to reconstruct the original numbering of the holes. We need to keep a tiny bit more information. That's the set I wrote down: {{1,3},{2}}. Call each element of this set a block. I've written the elements of the blocks in ascending order and I've written the blocks in ascending order of their lowest elements. The first block corresponds to hole 1 in the S-container and the second block corresponds to hole 2. Similarly, we write the elements of the blocks into the holes in the T-containers. And that allows us to reconstruct the original ST-container.
Think about the general case. We make n holes in an ST-container. So up to n of the T-containers acquire holes. Let's say it's m holes. We can think of the S-container having m holes and these holes being filled by T-containers with b1, b2,...,bm holes where the sum of the bi is n. We're essentially just partitioning the original n holes {1,2,...,n} into m sets. So each ST-container with n holes gives a partition of {1,...,n}, an S-container with n holes, and m T-containers where the ith has bi holes. Writing containers with n holes as nth derivatives we get
dn(F(G(X))/dXn = sum over each partition P of {1,...,n} of d|P|F/dG|P| times the product over each block B in P of d|B|F/dX|B|
Note that the equality above isn't just a numerical equality, it's an isomorphism of types. In fact, it's the type version of the 'combinatorial form' of the Faà di Bruno formula. Although that wikipedia page describes the formula as 'forbidding', if I've done my job right then I think the above picture make it seem almost trivial. I find it much easier to think of this version of the chain rule in terms of holes.
And the explanation for the title of this post: in 1988 Pope John Paul II beatified Faà di Bruno.
Saturday, June 14, 2008
Categories of polynomials and comonadic plumbing
Suppose you have a Haskell program and you want to introduce a new global constant into your program. There are at least two approaches you could take:
Now I’m going to roughly sketch a more categorical view of both of these approaches. So let’s restrict ourselves to the subset of Haskell that corresponds to typed lambda calculus without general recursion so that we know all of our functions will be total and correspond to the mathematical notion of a function. Then all of our functions become arrows in the category that we’ll call Hask.
Firstly consider approach (1). Suppose we want to introduce a new constant, x, of type A. Category theory talks about arrows rather than elements of objects, so instead of introducing x of type A, introduce the function x:1->A where 1 is the terminal object in Hask, normally called (). An element of A is the same thing as an element of 1->A, but in the latter case we have an arrow in the category Hask.
Before continuing, let me digress to talk about polynomials. Suppose we have a ring (with an identity) R. We define R[x], where x is an indeterminate, to be the ring of polynomials in x. Another way to describe that is to say that R[x] is the smallest ring containing R and an indeterminate x, that makes no assumptions about x other than those required to make R[x] a ring. For example we know that (1+x)(1-x)=1-x2, because that must hold in any ring. Given a polynomial p in R[x] we can think of it as a function fp from R to R. fp(a) is the value we get when substituting the value of a for x in p. So a polynomial in R[x] is the same as a function from R to R that can be written in terms of elements of R, multiplication and addition.
We can do the same with category theory. Given a category A we can ask for the smallest category extending A and containing an indeterminate arrow x:1 -> A. Just as with polynomials we have to allow all possible arrows that can be made by composing arrows of A with x. The resulting expressions for arrows will contain x as a free variable, just like the way x appears in polynomials. In fact, by analogy we can call the resulting category, A[x], the category of polynomials in x:1->A. In the special case A=Hask, you can see that Hask[x] is the category of Haskell functions extended by a new constant of type x:1->A but assuming no equations other than those necessary to make Hask[x] a category. Just as an arrow in Hask is a Haskell function, an arrow in Hask[x] is a Haskell function making use of an as yet undefined constant x.
(I've glossed over some subtleties. Just as we need a suitable equivalence relation to ensure that (1+x)(1-x)=1-x2 in R[x], we need suitable equivalence relations in our category. I'll be showing you where to find the missing details later.)
Here's the implementation of a function, h, making use of a constant x:
(Note that I'll be using Edward Kmett's category-extras shortly so I need some imports)
Now consider the second approach. The easiest thing is to just give an implementation of the above using the reader monad:
Note how, as is typical in monadic code, I have to plumb f' and g' together using >>= so that 1.23456 is passed through f' and g'. Previously I've described another way to think about the composition of monadic functions. Using >>= we can compose functions of type a->m b and b->m c to make a function of type a->m c. The result is that given a monad we can form the Kleisli category of the monad. The objects are the same as in Hask, but an arrow from a->b in the Kleisli category is an arrow of type a->m b in Hask. It's not hard to show this satisfies all of the axioms of a category. When we program in the reader monad it's a bit like we've stopped using Hask and switched to the Kleisli category of the reader monad. It's not quite like that because we used functions like +. But in theory we could use lifted versions of those functions too, and then we'd be programming by composing things in the Kleisli category. If we call the reader monad R then we can call the corresponding Kleisli category HaskR. (Strictly speaking that R needs a subscript telling is the type of the value we intend to ask for.)
So here's the important point: Hask[x] is the same category as HaskR. In both cases the arrows are things, which when supplied a value of the right type (like 1.23456), give arrows in Hask from their head object to their tail object.
But there's another way to do this. We can use the reader comonad:
In a similar way, we're dealing with arrows of the form wa -> b and we can compose them using =>>. These arrows form the coKleisli category of the reader comonad, S, which we can write HaskS. So we must have
Now some back story. Over 20 years ago I was intrigued by the idea that logic might form a category with logical ‘and’ and ‘or’ forming a product and coproduct. I came across the book Introduction to Higher Order Categorical Logic by Lambek and Scott for ₤30.00. That’s ₤60.00 at today's prices, or about $120.00. On a student grant? What was I thinking? And as it bore no relation to anything I was studying at the time, I barely understood a word of it. I was probably fairly applied at that point doing courses in stuff like solid state physics and electromagnetism as well as a bit of topology and algebra. I doubt I'd heard of lambda calculus though I could program in BASIC and APL. So there it sat on my bookshelf for 22 years. Periodically I’d look at it, realise that I still didn’t understand enough of the prerequisites, and put it back on the shelf. And then a month or so ago I picked it up again and realised that the first third or so of it could be interpreted as being about almost trivial Haskell programs. For example, on page 62 was
The language is a little different. Lambek and Scott used the term cotriple instead of comonad and Kleisli category where I’d say coKleisli category. δ and ε are cojoin and coreturn. And Lambek and Scott's theorem applies to any cartesian closed category. But after staring at this claim for a while it dawned on me that all it was really saying was this: here are two ways to introduce new constants into a category. But there’s no way I would have seen that without having practical experience of programming with monads. Learning Haskell has finally paid off. It’s given me enough intuition about category theory for me to get some return on my ₤30.00 investment paid to Heffers all those years ago. I expected to take this book to my deathbed, never having read it.
Anyway, for the details I left out above, especially the correct equivalence relation on Hask[x], you'll just have to read the book yourself.
Also, note the similarity to the deduction theorem. This theorem says that if we can prove B, assuming A, then we can deduce A implies B without making any assumptions. It unifies two way to introduce a proposition A, either as a hypothesis, or as an antecedent in an implication. In fact, the above theorem is just a categorical version of the deduction theorem.
Also note the connection with writing pointfree code. In fact, the pointfree lambdabot plugin makes use good use of the reader monad to eliminate named parameters from functions.
I’m amazed by seeing a book from 1986 that describes how to use a comonad to plumb a value through some code. As far as I know, this predates the explicit use of the reader monad in a program, Wadler and Moggi’s papers on monads, and certainly Haskell. Of course monads and comonads existed in category theory well before this date, but not, as far as I know, for plumbing computer programs. I’d love to hear from anyone who knows more about the history these ideas.
- Simply introduce a new global constant. You could name it x and write something like x=1.23456 and refer to x throughout your code. This has the advantage of being easy to implement.
- Write all of your code in monadic style and make use of the reader monad. This is intrusive in the sense that you may have to make many changes to your code to support it. But it has the advantage that all of your functions now explicitly become functions of your global constant.
Now I’m going to roughly sketch a more categorical view of both of these approaches. So let’s restrict ourselves to the subset of Haskell that corresponds to typed lambda calculus without general recursion so that we know all of our functions will be total and correspond to the mathematical notion of a function. Then all of our functions become arrows in the category that we’ll call Hask.
Firstly consider approach (1). Suppose we want to introduce a new constant, x, of type A. Category theory talks about arrows rather than elements of objects, so instead of introducing x of type A, introduce the function x:1->A where 1 is the terminal object in Hask, normally called (). An element of A is the same thing as an element of 1->A, but in the latter case we have an arrow in the category Hask.
Before continuing, let me digress to talk about polynomials. Suppose we have a ring (with an identity) R. We define R[x], where x is an indeterminate, to be the ring of polynomials in x. Another way to describe that is to say that R[x] is the smallest ring containing R and an indeterminate x, that makes no assumptions about x other than those required to make R[x] a ring. For example we know that (1+x)(1-x)=1-x2, because that must hold in any ring. Given a polynomial p in R[x] we can think of it as a function fp from R to R. fp(a) is the value we get when substituting the value of a for x in p. So a polynomial in R[x] is the same as a function from R to R that can be written in terms of elements of R, multiplication and addition.
We can do the same with category theory. Given a category A we can ask for the smallest category extending A and containing an indeterminate arrow x:1 -> A. Just as with polynomials we have to allow all possible arrows that can be made by composing arrows of A with x. The resulting expressions for arrows will contain x as a free variable, just like the way x appears in polynomials. In fact, by analogy we can call the resulting category, A[x], the category of polynomials in x:1->A. In the special case A=Hask, you can see that Hask[x] is the category of Haskell functions extended by a new constant of type x:1->A but assuming no equations other than those necessary to make Hask[x] a category. Just as an arrow in Hask is a Haskell function, an arrow in Hask[x] is a Haskell function making use of an as yet undefined constant x.
(I've glossed over some subtleties. Just as we need a suitable equivalence relation to ensure that (1+x)(1-x)=1-x2 in R[x], we need suitable equivalence relations in our category. I'll be showing you where to find the missing details later.)
Here's the implementation of a function, h, making use of a constant x:
(Note that I'll be using Edward Kmett's category-extras shortly so I need some imports)
> import Control.Monad.Reader
> import Control.Comonad
> import Control.Comonad.Reader

> x = 1.23456

> f a = 2*a+x
> g a = x*a
> h a = f (g a)

> test1 = h 2
Now consider the second approach. The easiest thing is to just give an implementation of the above using the reader monad:
> f' a = do
>    x <- ask
>    return $ 2*a+x

> g' a = do
>    x <- ask
>    return $ x*a

> h' a = return a >>= g' >>= f'

> test2 = runReader (h' 2) 1.23456
Note how, as is typical in monadic code, I have to plumb f' and g' together using >>= so that 1.23456 is passed through f' and g'. Previously I've described another way to think about the composition of monadic functions. Using >>= we can compose functions of type a->m b and b->m c to make a function of type a->m c. The result is that given a monad we can form the Kleisli category of the monad. The objects are the same as in Hask, but an arrow from a->b in the Kleisli category is an arrow of type a->m b in Hask. It's not hard to show this satisfies all of the axioms of a category. When we program in the reader monad it's a bit like we've stopped using Hask and switched to the Kleisli category of the reader monad. It's not quite like that because we used functions like +. But in theory we could use lifted versions of those functions too, and then we'd be programming by composing things in the Kleisli category. If we call the reader monad R then we can call the corresponding Kleisli category HaskR. (Strictly speaking that R needs a subscript telling is the type of the value we intend to ask for.)
So here's the important point: Hask[x] is the same category as HaskR. In both cases the arrows are things, which when supplied a value of the right type (like 1.23456), give arrows in Hask from their head object to their tail object.
But there's another way to do this. We can use the reader comonad:
> f'' a = 2*extract a+askC a
> g'' a = extract a*askC a
> h'' a = a =>> g'' =>> f''

> test3 = runCoreader (h'' (Coreader 1.23456 2))
In a similar way, we're dealing with arrows of the form wa -> b and we can compose them using =>>. These arrows form the coKleisli category of the reader comonad, S, which we can write HaskS. So we must have
Hask[x]≅HaskR≅HaskS.
Now some back story. Over 20 years ago I was intrigued by the idea that logic might form a category with logical ‘and’ and ‘or’ forming a product and coproduct. I came across the book Introduction to Higher Order Categorical Logic by Lambek and Scott for ₤30.00. That’s ₤60.00 at today's prices, or about $120.00. On a student grant? What was I thinking? And as it bore no relation to anything I was studying at the time, I barely understood a word of it. I was probably fairly applied at that point doing courses in stuff like solid state physics and electromagnetism as well as a bit of topology and algebra. I doubt I'd heard of lambda calculus though I could program in BASIC and APL. So there it sat on my bookshelf for 22 years. Periodically I’d look at it, realise that I still didn’t understand enough of the prerequisites, and put it back on the shelf. And then a month or so ago I picked it up again and realised that the first third or so of it could be interpreted as being about almost trivial Haskell programs. For example, on page 62 was
Proposition 7.1
The category A[x] of all polynomials in the indeterminate x:1->A over the cartesian or cartesian closed category A is isomorphic to the Kleisli category AA=ASA of the cotriple (SA,&epsilonA,δA).
The language is a little different. Lambek and Scott used the term cotriple instead of comonad and Kleisli category where I’d say coKleisli category. δ and ε are cojoin and coreturn. And Lambek and Scott's theorem applies to any cartesian closed category. But after staring at this claim for a while it dawned on me that all it was really saying was this: here are two ways to introduce new constants into a category. But there’s no way I would have seen that without having practical experience of programming with monads. Learning Haskell has finally paid off. It’s given me enough intuition about category theory for me to get some return on my ₤30.00 investment paid to Heffers all those years ago. I expected to take this book to my deathbed, never having read it.
Anyway, for the details I left out above, especially the correct equivalence relation on Hask[x], you'll just have to read the book yourself.
Also, note the similarity to the deduction theorem. This theorem says that if we can prove B, assuming A, then we can deduce A implies B without making any assumptions. It unifies two way to introduce a proposition A, either as a hypothesis, or as an antecedent in an implication. In fact, the above theorem is just a categorical version of the deduction theorem.
Also note the connection with writing pointfree code. In fact, the pointfree lambdabot plugin makes use good use of the reader monad to eliminate named parameters from functions.
I’m amazed by seeing a book from 1986 that describes how to use a comonad to plumb a value through some code. As far as I know, this predates the explicit use of the reader monad in a program, Wadler and Moggi’s papers on monads, and certainly Haskell. Of course monads and comonads existed in category theory well before this date, but not, as far as I know, for plumbing computer programs. I’d love to hear from anyone who knows more about the history these ideas.
Friday, June 06, 2008
Drugs, Kate Moss, and Intuitionistic Logic
Before make the post I promised I'd make I thought I'd make a digression to point out a connection between Intuitionistic Logic and a recent news story.
Intuitionistic logic is what we get when we take ordinary everyday classical logic and drop the Law of the Excluded Middle (LEM), in other words, we drop the law that says that for any proposition, either it or its negation is true. This is such an ingrained notion that it's hard to imagine giving it up. For example, it seems obvious that either it's raining or it's not raining. But there are good reasons for not taking it for granted in mathematics. The main issue is that sometimes when we use LEM we find that we can prove the existence of something, but have no way of constructing it. Mathematics is full of such proofs. The best known example is probably the proof that an irrational number raised to the power of an irrational number can be rational. Some mathematicians (and many computer scientists) only like constructive proofs, ie. proofs that actually exhibit the thing whose existence is being proved. Using intuitionistic logic is a good way to always force this to be true. So, for example, in classical logic, you might find you have proved "A or B", but not have a proof of A or a proof of B. But in intuitionistic logic, if you prove "A or B", then you must have proved A or you must have proved B.
Now (British) criminal law is more lax than mathematical logic when it comes to proof. You only need to prove something beyond reasonable doubt, rather than providing a rigorous derivation from axioms. (Though admittedly mathematicians rarely do this in practice.) But criminal law does have one place where it has higher standards of proof than classical logic: you can't necessarily convict someone of "A or B" unless you have a proof of A or a proof of B. A proof of "A or B" will not do.
It seems that there is enough evidence to show that Kate Moss recently used a controlled substance of class A or class B. Unfortunately, the law requires either a proof that she had been using a class A drug, or a proof that she had been using a class B drug. A proof that she had been using one or the other will not do. And hence Kate Moss cannot be prosecuted. In this regard, the law is Intuitionistic. If you're going to have a legal system that doesn't recognise LEM then you really need to carve up crime-space as a semilattice so you can charge people with the join of two crimes :-)
Wednesday, May 21, 2008
Life in a Lazy Universe
I've seen lots of articles on simulated reality recently. Supposing for a bit that this is a sensible hypothesis to entertain and not just a science fictional conceit, what might be the consequences of supposing that such a 'reality' is running on a machine with lazy evaluation?
If your task were to simulate a universe well enough for its inhabitants to be convinced it was seamless, then there is an obvious optimisation that could be made. You could simulate just those parts that could be perceived by the inhabitants. But the catch is that if an inhabitant were to explore a new region, the simulation would be required to fill in that region. Just creating a blank new area wouldn't do, it's current state would need to be consistent with having had a plausible history and so the simulation would be required to fill in not just its current state, but also its past. This is precisely what is provided by lazy evaluation - demand driven evaluation that takes place only when results are observed. It seems natural that such a simulation should make use of laziness.
But such optimisation doesn't need to be limited to lazily computing 'new regions' where by 'region' we mean a spatially localised volume. We could also imagine implementing level of detail. If we don't look closely at an object in our grasp, there's no need to compute every single detail of it. We need only provide detail at the resolution at which it can be perceived. We'd like this built into every aspect of the simulation so that anything within it is computed only to a desired accuracy. I've spoken a few times about such a data structure in posts like this. This is precisely what the real numbers give us. Computationally, a real number is an object which when given a degree of accuracy, returns a rational number (or some other finitely manipulatable structure) that represents the real to this accuracy. The wikipedia article suggests that 'the use of continua in physics constitutes a possible argument against the simulation of a physical universe'. This is diametrically opposed to what I might argue: in fact the presence of continua suggests the existence of an efficient demand driven simulation with level of detail. The problem is that the people who have been thinking about these issues have been thinking in terms of traditional imperative style programming where a real number is typically represented to some fixed finite precision. But in fact there are infinitely many real numbers that can be represented exactly if we think in terms of lazy data structures.
But this is all idle speculation if we don't make predictions. So here is one. In a computer simulated universe, all physics must obviously be computable. But all computable functions are continuous. So in a simulated universe we'd expect the physical laws involving real numbers to make use of them only in a continuous way. Sound familiar?
The next section is an aside and I need to give a spoiler alert as I'll be mentioning some aspects of Greg Egan's Permutation City.
What exactly what is meant by 'demand driven' above? If we have implemented a simulated universe I expect we would be interested in looking in on it from time to time. So this is what is usually meant by 'demand'. Whenever the program performs I/O to show us what is going on, it would trigger the evaluation of the lazy thunks that had been sitting around. But consider how the universe might appear to its inhabitants. Whether or not we look in on it us surely irrelevant to the inhabitants, assuming we just look and don't try to communicate. But if I/O isn't performed, functional programmers don't make much of a distinction between an unevaluated thunk and an evaluated one. They are observationally equivalent. So do we in fact need to run the simulation for its inhabitants to consider themselves to exist? Anyway, I won't say anything more about this because Permutation City deals with this issue at length. I'm just rephrasing it as a lazy evaluation issue.
My next post will be on life in a monadic universe.
Update: I'm going to add some detail to the above. Suppose we represent real numbers as infinite sequences of digits. Suppose also that we have some module in a simulation that, let's say, resolves collisions between particles. You might ask it "what is the velocity, to 20 digits, of particle A after the collision". It must then look at all of the relevant inputs, decide how accurately it needs them, and then propagate new requests. For example it might work like this "if I need the velocity of A to 20 digits I need the mass of particle B to 25 digits and the velocity of particle C to 26 digits..." and so on. The idea of demand driven modules that produce outputs to a given accuracy by making requests of their inputs to a given accuracy exactly parallels the subject of analysis in mathematics. There you ask questions like "if I need to know f(x,y) with an error of no more than δ, what ε of error can I tolerate in x and y?". Functions that allow this kind of analysis are precisely the continuous ones. In other words, a simulated universe that is built from continuous functions lends itself to a demand driven implementation. One might argue that the whole of the fields of analysis (and topology) are the study of functions that can be evaluated in this way. And of course, in our universe, the functions we study in physics are typically the continuous functions. So contrary to the claim that the existence of continua argues against the idea that the universe is a simulation, I'd like to point out that they might actually make it more convenient to simulate our universe. In fact, we use this fact all the time in ordinary everyday physics simulations because we know we only need to work to a certain level of accuracy to get accurate results.
The claim that this universe can be simulated, and the claim that this universe is a simulation, are philosophical claims that I don't like to waste time on. But the claim that the existence of continua blocks the notion that the universe is a simulation is a fairly precise statement of logic, mathematics and physics. I claim it is wrong, and that's the only claim I'm making here.
Subscribe to:
Posts (Atom)